Brevitas is named Xilinx, authored by AMD, and licensed BSD-3 in code
Brevitas: neural network quantization in PyTorch
At a glance
- What is it?
- Brevitas is a PyTorch quantization library supporting post-training and quantization-aware training, with the repository still hosted under the Xilinx organisation while the setup file names AMD and carries a BSD license header. Those three identities disagree, and the license is the part that matters for anyone reusing it.
- Who is it for?
- Brevitas is a serious research library with a long release history and a broad set of layer implementations, and it is the right tool if you need to see inside a quantization scheme rather than call one. Before you build on it, resolve the licensing question, because the metadata declares nothing while the source header and the setup file point at a different company under a different name than the repository owner.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
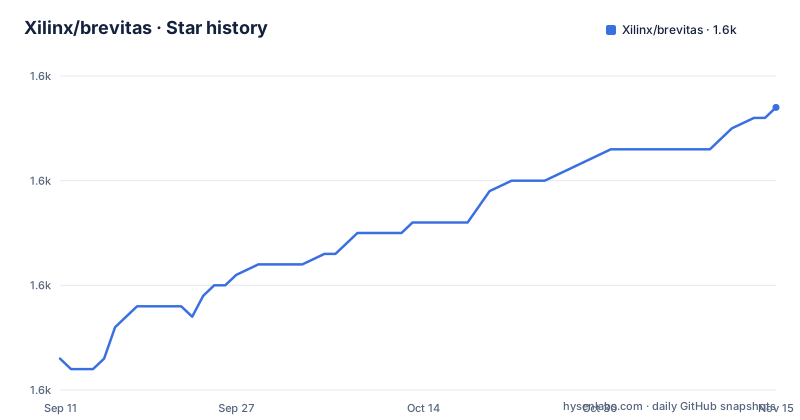
- Xilinx/brevitas1,597 ★ · +24
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| Xilinx/brevitas | 1.6k | 1.6k |
24 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three identities and a license header that differs from the metadata
The repository is hosted under the Xilinx organisation and the documentation site is served from that same namespace. The packaging file says something different: the author field names AMD Research and Advanced Development, and the contact address is an AMD one.
The third identity is in the source. The packaging file opens with a copyright line naming Advanced Micro Devices and carries an SPDX identifier for a three clause BSD license.
So the repository name, the package metadata and the source header each point somewhere different. None of that is necessarily wrong, since corporate acquisitions and reorganisations leave exactly this trail, and a project can legitimately be hosted under a legacy organisation while being maintained by another entity.
The part that affects you is the license. The repository metadata declares no license, so there is nothing authoritative to read from the project page, while the only license statement available is that line in the source header. For a research library that people fork, vendor into pipelines and cite, that is a thin basis, and the page itself says the project is a research project and not an official product of the company whose name is on the repository.
If reuse matters to you, ask before assuming terms.
The framework dependency has a tested ceiling and an open floor
The requirements section lists four things. Python 3.10 or newer. The deep learning framework at a minimum of one specific release and a maximum of a much later one, with a parenthetical explaining that more recent versions would be untested. One of the three major desktop operating systems. And GPU acceleration during training, marked optional but recommended.
That ceiling is unusual and worth taking seriously. The stated reason is not that newer versions break, but that nobody has run the test suite against them, which is a different and more honest reason. It also means the upper bound will move whenever someone runs the tests, and a project that pins a ceiling tends to lag behind the ecosystem by design rather than by neglect.
The floor is the more consequential number for adoption, since it excludes older environments outright. Combined, the range tells you which environments the library is actually validated on, which is useful information when you are choosing whether to adopt it in a pipeline you also have to maintain.
Installation itself is a single command from the package index:
pip install brevitasThe extras for notebooks, export, tests and documentation are declared through separate requirement files rather than inline.
The layer list is where the actual coverage is
The quantized layers live under one module, and the page names the common ones rather than claiming completeness: one and two dimensional convolutions, their transposed counterparts, multi-head attention, recurrent layers and a long short-term memory variant.
What makes those classes useful is the tuning granularity. For each layer, quantization of different tensors can be set individually, and the page names the tensors involved as inputs, weights, bias and outputs among others. That is the difference between a library that quantizes a network as a whole and one you can configure per tensor, which is what you need when a particular layer is where accuracy goes.
The reference flow is an image classification example that quantizes an existing model from the vision library under several configurations, with bit width and scale granularity given as the examples of what varies. So the intended entry point is: take a model you already have, pick a configuration, measure the result.
The layer list is also the project's real limit. Anything outside it, or a layer needing a specific quantization scheme, means writing a quantizer yourself, which the library supports but the page does not walk through.
The release history is long, dated, and annotated
The history section is unusual for a README: it is a dated log of every release going back to the first one on PyPI in early 2021, each line linking to its release notes.
What makes it informative is the annotations. Several entries describe what changed rather than just naming a version: one notes a re-release of the same version to fix a packaging problem, another describes adding support for a framework-level dispatch mechanism on the quantised tensor type, and another describes implementing shape and enum solvers inside a dependency injection system so that quantisers could be made self-contained. A later one mentions a tutorial notebook added for a conference.
Two patterns are visible in the dates. The project shipped frequently through 2021 and 2023, then slowed: the gap between the 2023 minor release and the 2024 one is months, and the 2025 releases are months apart rather than weeks. The most recent sequence is tight again, with four releases inside three months in 2026.
So the cadence recovered rather than faded. The most recent push is dated 2026-10-02 and the repository is not archived, which for a research library is a better signal than the version number alone.
The citation asks for a software DOI with a year you have to update
The page asks adopters to cite the project, and supplies a software citation rather than a paper citation: five named authors, a title consisting of the organisation and the repository name, the publisher given as a repository-agnostic archive, and a DOI.
Two details in that block are worth noting. The title is the repository path, not a package name, so the citation identifies the artefact by where it lives rather than by what it is called, which means a citation survives the project moving. And the year field is set to the current year in the template rather than to a release year, so a reader who copies it verbatim will cite the year they copied it, not the version they used.
For a library on a rolling release cadence that is a real problem, because there is no version in the citation to disambiguate. The DOI resolves to an archive that mints a citation per version, which is the right mechanism, and the page carries a badge for the archive's latest DOI as well.
So the project has both a fixed DOI for the project as a whole and an archive that can produce a version-specific one. The template uses the former and the badge points at the latter, and only the second pins an actual release.
Extras are declared as requirement files, one per capability
The packaging file declares its dependencies by reading them from separate text files rather than writing them inline, with a dedicated file per extra: one for the numpy variant, one for notebooks, development, documentation, export, a named transform, tests, text to speech, speech to text, a large language model extra, an export extra for that model family, an evaluation extra, and at least one more truncated from view.
That is a lot of extras, and the naming tells you what the library has grown to cover. Beyond quantization of vision models, there are extras for audio in both directions, for large language models, for evaluating them, and for two separate export paths.
The setup file itself is also not the whole picture. It derives its version from source control rather than hard coding it, which means a plain source checkout has no version until the tags are available, a common source of confusion when installing from a git URL. It also declares requirements for the build step through a separate file.
The repository layout follows the same separation, with a requirements directory, a source directory, both a configuration file and a packaging file, a test directory and a notebook directory, plus two documentation directories that appear to hold sources and generated output separately.
The project states its own status plainly
Two lines near the top of the page set expectations, and they are the most useful thing on it.
The first says the project is a research project and not an official product of the company whose name is on the repository. The second asks for a star as the simplest way to support it.
The first is a status declaration with consequences. A research project carries no compatibility promise, no support commitment and no obligation to respond to an issue, and anyone reading the page knows that before installing rather than after their first failed build. It also explains the version ceiling on the framework dependency without having to explain it separately.
The second is worth reading as what it is. Asking for stars as the support mechanism means there is no commercial channel behind this project, which is normal for research software and consistent with everything else on the page.
Taken together with the release history, the picture is coherent: an actively moving research library with a long public record, an explicit non-product status, and no stated support commitment. That is a perfectly good project, provided you are not expecting a vendor's warranty.
Editorial conclusion
Brevitas is a serious research library with a long release history and a broad set of layer implementations, and it is the right tool if you need to see inside a quantization scheme rather than call one. Before you build on it, resolve the licensing question, because the metadata declares nothing while the source header and the setup file point at a different company under a different name than the repository owner. Treat that as a question to ask rather than a detail to assume. Then check the version ceiling on the framework dependency, which is explicitly an untested boundary, and remember this is a research project by its own statement rather than a supported product with a maintenance commitment.
Frequently asked questions
What is brevitas and what does it do?
It is a PyTorch library for neural network quantization supporting both post-training quantization and quantization-aware training. It provides quantized implementations of common layers such as one and two dimensional convolutions, their transposed forms, multi-head attention, recurrent layers and an LSTM variant, with quantization of inputs, weights, bias and outputs tunable individually per layer.
What are the requirements for brevitas?
Python 3.10 or newer, a framework minimum of 1.13 and a ceiling of 2.13 with newer versions described as untested, and Windows, Linux or macOS. GPU acceleration during training is optional but recommended.
How do I install brevitas?
With a single pip command from the package index. Optional capability groups such as notebooks, export, tests and documentation are declared as separate extras, each backed by its own requirements file.
Who maintains brevitas and is it an official product?
The page states plainly that it is a research project and not an official product of the company named on the repository. The packaging file credits AMD Research and Advanced Development with an AMD contact address, while the repository itself is hosted under the Xilinx organisation.
How do I cite brevitas?
The page supplies a software citation with five named authors, the repository path as the title, an archive as the publisher and a DOI. The year field is a template value rather than a release year, so a per-version citation should come from the archive's latest DOI badge instead.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/xilinx-brevitas)Star history chart for your README
[](https://hysenlabs.com/projects/xilinx-brevitas)Was this useful?