MASR: one streaming flag, four decoders, and no public weights
MASR: a PyTorch implementation of streaming and non-streaming automatic speech recognition, compatible with both online and offline recognition. Currently supports Conformer, Squeezeformer and DeepSpeech2 models, with multiple data augmentation methods.
At a glance
- What is it?
- MASR is a PyTorch speech recognition framework whose Chinese README documents four model families, four decoders and both streaming and offline inference from one configuration flag. The published error rate tables are detailed and reproducible, and every download link in them points at a paid community instead of a URL.
- Who is it for?
- Judgment: MASR is a good codebase to read and an awkward one to start from, because the parts that make it attractive, the streaming switch, the decoder comparison, the augmentation config, are all public, while the part that makes it usable out of the box, the weights, sits behind a paid community.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 132 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
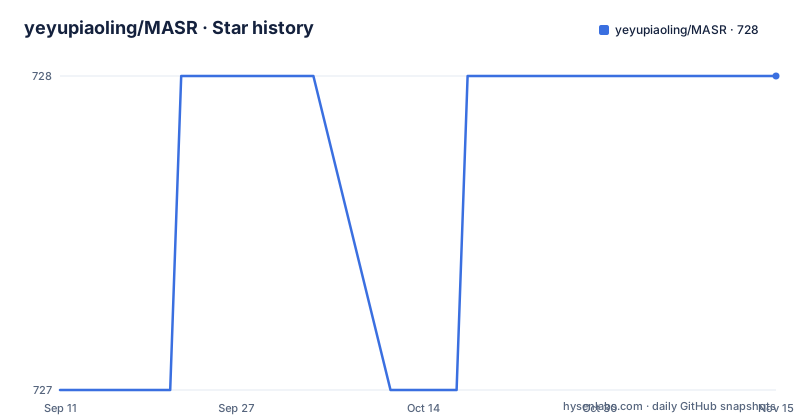
- yeyupiaoling/MASR728 ★ · +1
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| yeyupiaoling/MASR | 727 | 728 |
1 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Streaming is a configuration flag, not a separate model
The framework covers online and offline recognition with the same model classes. Streaming is a parameter named `streaming` in the configuration file, so the same Conformer that runs offline in one config runs chunk by chunk in another. The model list is deepspeech2, conformer, squeezeformer and efficient_conformer, and the decoder list is longer: `ctc_greedy_search`, `ctc_prefix_beam_search`, `attention_rescoring` and `ctc_beam_search`. Preprocessing choices are fbank and mfcc. Inference comes in four shapes, short audio, long audio, streaming, and speaker diarisation, which is a separate entry point at the repo root rather than a flag. What the published tables do not do is match the feature list: every download table lists only Conformer and DeepSpeech2, and squeezeformer and efficient_conformer appear nowhere in the weights section.
Every pretrained weight is behind the paid community, not a URL
The model tables are long and precise about error rates, and every single row ends in the same instruction, 加入知识星球获取, which means obtain it through the knowledge community. There is no download link, no model zoo URL and no release artefact anywhere in them. The same community is offered at the top of the page as the place to discuss the project, and the README states it also hosts model files for the author's other projects. The online demo is the one thing you can reach without joining anything: a web page at tools.yeyupiaoling.cn/speech/masr, alongside a WeChat mini program. So the practical position is that the framework, the configs, the training scripts and the evaluation script are all public, and the artefacts they produce are not.
The decoder changes the error rate more than any other listed knob
The WenetSpeech table, 10000 hours of Mandarin scored with character error rate, gives four decoders per model and shows how much the choice matters. Conformer with `ctc_greedy_search` reaches 0.14391 on test_net, `ctc_prefix_beam_search` 0.14326, `attention_rescoring` 0.13523 and `ctc_beam_search` 0.18227. The ranking is not the ranking on aishell_test, where the same `ctc_beam_search` row is the best of the four at 0.04981 against 0.06751 for greedy search. So the decoder that looks worst on one test set is the best on another, which makes the test set name part of the decision rather than a footnote. The search size is stated as 10 for `ctc_prefix_beam_search` and `attention_rescoring`. Two rows are empty rather than estimated: the DeepSpeech2 rows on WenetSpeech carry no numbers at all, and `ctc_beam_search` is a slash for Librispeech and for the mixed Chinese and English set.
Three error metrics across six datasets, and one dataset name typo
The tables switch metric with the language: character error rate for Chinese, word error rate for English, and a mixed error rate where the two are combined. WenetSpeech carries three test sets, test_net, test_meeting and aishell_test, and the largest row, a dataset of 16000 hours or more, reports all four numbers at once. AIShell is 179 hours, Librispeech is 960 hours, and beyond those there is Cantonese including Hong Kong Cantonese, a Chinese and English mixed set, and Uyghur trained on CommonVoice-Uyghur with THUYG20. That last one is spelled two ways in the same table, THUYG20 in the first Uyghur row and THUG20 in the third, so anyone joining the training data will have to decide which name is real. The note under the tables says the numbers come from eval.py and that three decoders were measured, while four decoder rows are printed above it.
setup.py deletes and recopies the configs directory every time it runs
The packaging script does its file copying at module level, before setup() is ever called. It imports the package to read `masr.__version__`, then runs `shutil.rmtree('./masr/configs/', ignore_errors=True)` and copies `./configs/` into `./masr/configs/` with `shutil.copytree`. After setup() returns, the same rmtree runs again. So importing or running setup.py has a side effect on the source tree, and the intent is clear: configs/ at the root is the editable copy, masr/configs/ is the packaged copy, and the package declares `package_data={'': ['configs/*']}` to ship it. Two details there are worth knowing. find_packages excludes download_data/, and the classifiers still advertise Python 3.7 through 3.11 while the environment section asks for Python 3.11 with Pytorch 2.5.1.
One dependency is pinned exactly, the rest float on a lower bound
requirements.txt is eighteen lines and mixes two styles. visualdl is fixed at 2.5.3 with an equality sign, everything else uses a lower bound or nothing: numpy>=1.19.2, scipy>=1.6.3, python-Levenshtein>=0.25.1, soundfile>=0.12.1, soundcard>=0.4.2, resampy>=0.2.2, zhconv>=1.4.2, ijson>=3.1.4, pyyaml>=5.4.1, scikit-learn>=1.0.2, typeguard>=2.13.3, onnxruntime>=1.17.1, sentencepiece>=0.2.0, loguru>=0.7.2, yeaudio>=0.0.7, kaldi_native_fbank>=1.20.0 and tqdm. Three of those carry the story of the V3 rewrite. kaldi_native_fbank replaced the previous preprocessing library for speed and platform coverage, sentencepiece replaced the old token method and is what makes mixed Chinese and English training workable, and the classifiers record Python 3.11 as the newest supported interpreter.
Five entry points for training work, four for inference
The repo root is a set of scripts rather than a package interface. Training side: train.py, create_data.py for building the dataset, extract_features.py, export_model.py, and eval.py, which is the script the error rate tables were produced with. Inference side: infer_path.py for files, infer_gui.py, infer_sd_asr.py for speaker diarisation, and infer_server.py. The GUI is a web one, since static/ and templates/ sit at the top level beside it. Around them sit configs/, dataset/, download_data/, tools/ and docs/. Three of those names are directories that do things rather than hold code, and download_data/ is excluded from packaging, which tells you the data scripts are meant to be run from a clone and not installed.
V3 is incompatible with V2, and the release log stops in March 2025
The version story is stated in one line at the top. The current version is V3, it is not compatible with V2, and anyone who wants V2 is pointed at the release/2.3.x branch. The default branch is develop. The three named differences between V2 and V3 are a reorganised project structure, the switch to kaldi_native_fbank, and the move to sentencepiece tokens that lower the cost of handling several languages and make mixed Chinese and English training possible. The update log has a single entry, 2025.3, marked as the release of the final V3. There are no GitHub releases at all, so that date and the branch names are the whole version history a newcomer gets. The repository is Apache-2.0, 728 stars, 115 forks, no open issues, and the last push landed on 6 July 2026.
Editorial conclusion
Judgment: MASR is a good codebase to read and an awkward one to start from, because the parts that make it attractive, the streaming switch, the decoder comparison, the augmentation config, are all public, while the part that makes it usable out of the box, the weights, sits behind a paid community. Anyone planning to evaluate it should train a small recipe first and reproduce one row of the error rate tables with eval.py before trusting the rest, since a table you cannot regenerate is just a claim. Two housekeeping checks first: setup.py rewrites the packaged configs directory every time it runs, so keep configs/ clean in a working tree, and remember that the default branch is develop while the V2 code lives on release/2.3.x.
Frequently asked questions
Which speech recognition models does MASR support?
deepspeech2, conformer, squeezeformer and efficient_conformer, and every one of them works in streaming and non-streaming mode through the streaming parameter in the configuration file. The published download tables only cover Conformer and DeepSpeech2.
How do I get the pretrained models that MASR lists?
Every row of the download tables points to the author's paid knowledge community rather than to a URL, and the community is also said to host model files for the author's other projects. Training from scratch is the only public route to weights.
What environment does MASR ask for?
Anaconda 3, Python 3.11, Pytorch 2.5.1, on Windows 11 or Ubuntu 22.04. requirements.txt floats most dependencies on a lower bound but fixes visualdl at 2.5.3, and setup.py's classifiers still advertise Python 3.7 through 3.11.
Is MASR V3 compatible with the V2 branch?
No. The README states that V3 is not compatible with V2 and points anyone who wants V2 at the release/2.3.x branch. The default branch is develop, and there are no GitHub releases to version against.
How were the MASR error rates measured?
With eval.py, according to the note under the tables, with a search size of 10 for ctc_prefix_beam_search and attention_rescoring. Character error rate is used for Chinese, word error rate for English, and a mixed rate where both appear.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/yeyupiaoling-masr)Star history chart for your README
[](https://hysenlabs.com/projects/yeyupiaoling-masr)Was this useful?