Chinese LLaMA Alpaca 2 splits long context into two different methods
Chinese LLaMA-2 and Alpaca-2 project (phase 2), including 64K long-context LLMs.
At a glance
- What is it?
- A second generation of Chinese Llama 2 models with a redesigned 55296 token vocabulary, LoRA based fine-tuning at 7B and 13B, and two separate long context paths: position interpolation for 16K and YaRN for 64K. Read this before you pick a size, because coverage is not uniform across the lineup.
- Who is it for?
- Pick these weights when you need a Chinese Llama 2 line with a released tokenizer and a 16K or 64K option, and stay at 7B if preference alignment matters to you. Skip them if you need a 13B long context build with RLHF, or if your serving stack needs a newer torch, since the published pins stop at transformers 4.35.0.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 6 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
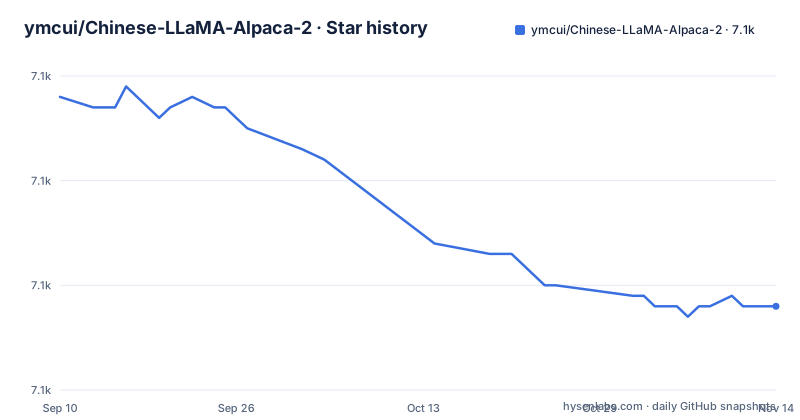
Star history
- ymcui/Chinese-LLaMA-Alpaca-27,098 ★ · -20
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| ymcui/Chinese-LLaMA-Alpaca-2 | 7.1k | 7.1k |
-20 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One 55296 token vocabulary serves base and chat models
The first generation project extended the original LLaMA and Alpaca tables to 49953 and 49954 tokens. This project threw that away and redesigned the vocabulary at 55296 tokens, then unified the LLaMA and Alpaca tables into a single one so the base and chat models stop mixing incompatible tokenizations. The stated payoff is encode and decode efficiency for Chinese text rather than new parameters. The practical consequence for a reader is that you must load the released tokenizer files and not the stock Llama 2 tokenizer, since the 55296 token vocabulary extends the original Llama 2 vocabulary.
16K leans on position interpolation, 64K leans on YaRN
Two different lengthening methods sit behind the two long context names. The 16K checkpoints at 7B and 13B come from position interpolation combined with NTK style scaling, support 16K context, and can be pushed toward 24K to 32K with NTK at inference time. The 64K checkpoints, offered at 7B alone, come from YaRN. The project also designed an adaptive empirical formula so a user does not hand tune NTK hyperparameters for each target length. Every model here was trained with FlashAttention 2, which matters because memory growth would otherwise blow up as the sequence lengthens. Keep in mind where the guarantee stops: a 16K checkpoint taken to 32K runs beyond the length it was trained for, so the quality drop at that setting is something you have to measure yourself.
7B and 13B are LoRA merges while 1.3B is tuned in full
The comparison table spells out the training recipe per size, and it is not uniform. The 1.3B base and chat models are trained full. The 7B and 13B base and chat models use LoRA plus fully trained embedding and lm-head layers. Incremental pretraining for the 7B base consumed 120G of Chinese corpus, the same volume used for the first generation Plus series, and instruction fine-tuning drew on 5M instruction examples. That is why the peft pin matters: LoRA training needs peft, and the requirements file pins peft==0.3.0, torch==2.0.1, transformers==4.35.0, sentencepiece==0.1.99 and bitsandbytes==0.41.1. Anyone starting a fresh fine-tune should expect to work inside that older stack rather than the newest releases.
Weights arrive as checkpoints, not as a package install
Nothing here installs a model. The repository holds scripts, notebooks, prompts, examples and a five line requirements file, while the weights are distributed separately as downloadable checkpoints. Local use on a personal CPU or GPU goes through quantization, and the v4.1 release added new GGUF builds using imatrix quantization plus AWQ quantized weights. The requirements file installs with:
pip install -r requirements.txtThat one line pulls torch 2.0.1, transformers 4.35.0, peft 0.3.0, sentencepiece 0.1.99 and bitsandbytes 0.41.1, which is what the pretraining and instruction tuning scripts expect. transformers, llama.cpp, text-generation-webui, LangChain, privateGPT and vLLM are all listed as supported ecosystems, so the serving stack is a separate decision with its own version constraints.
The 64K line and the RLHF line both stop at 7B
Coverage across the lineup is uneven, and the gaps decide what you can build. Base and chat models exist at 1.3B, 7B and 13B with 4K context. The 16K long context line covers 7B and 13B. The 64K line, built on YaRN, covers 7B alone. Preference aligned models, Chinese-Alpaca-2-RLHF, exist at 1.3B and 7B, so the 13B size has no aligned variant at all. The aligned checkpoints are described as a significant improvement in expressing correct values over the standard tuned models, and they are used exactly like the SFT models. The consequence for a reader is a forced tradeoff: a 13B pipeline that wants both long context and alignment has to accept 16K without RLHF, and the listed RLHF models are not offered in 16K or 64K variants at any size.
The system prompt was cut back on purpose
The first generation chat models used the Stanford Alpaca instruction template and system prompt. Experiments in this project found that the default Llama 2 Chat system prompt did not produce a statistically significant gain and that its content was too long. The Alpaca-2 series therefore keeps the Llama 2 Chat instruction template, for compatibility with the surrounding ecosystem, while simplifying the system prompt itself. If your prompts were tuned against first generation Chinese Alpaca output, expect the framing of replies to differ for the same question. Two smaller additions are worth knowing: CFG Sampling arrived as a decoding method in v2.0, and vLLM loading for YaRN long context models landed in v4.1.
A third generation project supersedes this one
On 2024/04/30 the author announced Chinese-LLaMA-Alpaca-3 with Llama-3-Chinese-8B and Llama-3-Chinese-8B-Instruct, and the notice recommends that users of both the first and second generation projects upgrade. This repository is not archived, yet the last push on record is 2026-04-19 while the newest tagged release is v4.1 from 2024-01-23, so the release history and the code history sit far apart. Treat the second generation line as a fixed point rather than a moving target: you get exactly the vocabulary, context lengths and quantizations listed here, and no further weight tuning is coming out of this repository.
Local runs mean quantized weights, not the full window
The project advertises fast local quantization and deployment on a personal computer CPU or GPU, and that is where the GGUF and AWQ builds fit. v4.1 also added vLLM support for loading YaRN long context models. Budget for your own measurement instead of inheriting a number.
Editorial conclusion
Pick these weights when you need a Chinese Llama 2 line with a released tokenizer and a 16K or 64K option, and stay at 7B if preference alignment matters to you. Skip them if you need a 13B long context build with RLHF, or if your serving stack needs a newer torch, since the published pins stop at transformers 4.35.0. The repository is Apache-2.0 while the base model comes from Meta's Llama 2, so check both sets of terms before you redistribute anything.
Frequently asked questions
What model sizes does Chinese LLaMA Alpaca 2 release?
Base and chat models come at 1.3B, 7B and 13B with 4K context. The 16K long context line covers 7B and 13B, the 64K line covers 7B only, and the RLHF aligned chat models cover 1.3B and 7B.
Which attention implementation does Chinese LLaMA Alpaca 2 use for training?
All models in the project were trained with FlashAttention 2. The stated reason is that it keeps memory growth in check when the context gets longer.
How much context can Chinese LLaMA Alpaca 2 16K models handle?
The 16K checkpoints support 16K tokens and can be extended toward 24K to 32K with NTK scaling at inference time. The 64K checkpoints at 7B use YaRN instead of position interpolation, and an adaptive formula removes the need to set NTK hyperparameters per length.
Can Chinese LLaMA Alpaca 2 be trained further by users?
Yes. The pretraining and instruction tuning scripts are open sourced, and requirements.txt pins peft 0.3.0, torch 2.0.1, transformers 4.35.0, sentencepiece 0.1.99 and bitsandbytes 0.41.1. The 7B and 13B recipes use LoRA with fully trained embedding and lm-head layers, while 1.3B is trained full.
What quantization formats does Chinese LLaMA Alpaca 2 publish?
Release v4.1 from 2024-01-23 added GGUF builds using imatrix quantization and AWQ quantized weights, together with vLLM support for loading YaRN long context models.
Is Chinese LLaMA Alpaca 2 still the newest Chinese Llama line from this author?
No. A 2024/04/30 announcement points both first and second generation users to Chinese-LLaMA-Alpaca-3, which released Llama-3-Chinese-8B and Llama-3-Chinese-8B-Instruct on a Llama 3 base.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ymcui-chinese-llama-alpaca-2)Star history chart for your README
[](https://hysenlabs.com/projects/ymcui-chinese-llama-alpaca-2)Was this useful?