KVCache-Factory puts seventeen cache methods behind one flag and admits the coverage is uneven
Unified KV Cache Compression Methods for Auto-Regressive Models
At a glance
- What is it?
- A research harness that started as one paper's method and became a comparison bench for the whole field: eviction, retrieval, cross-layer sharing, merging, quantization and lossless offloading, all reachable from the same command line. The interface is the achievement. The file is also candid about where the interface does not hold.
- Who is it for?
- KVCache-Factory is worth adopting if you are comparing cache policies rather than shipping one, because the value is that every method meets the same three runners and the same flags. It is not a library to depend on: the install steps put the repository on your Python path rather than installing a package.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 94 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
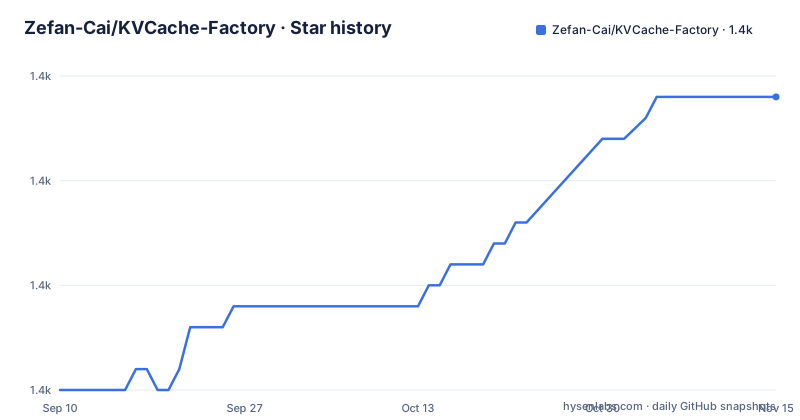
- Zefan-Cai/KVCache-Factory1,394 ★ · +14
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| Zefan-Cai/KVCache-Factory | 1.4k | 1.4k |
14 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Seventeen rows, four families, and a coverage warning in the same paragraph
The methods table is the centre of this project, and it is a taxonomy rather than a feature list.
The rows sort into families. Compression and eviction covers an attention sink with a sliding window, heavy hitter retention, observation window pooling, proxy token scoring with optional random eviction, historical importance accumulation with a fixed budget, and layer-wise pyramidal budgets. Retrieval covers page-level key metadata with query-aware selection, norm-based token selection, and head-aware allocation. Cross-layer compression appears once, with adjacent layer direction sharing and token retention. Merging appears once, with attention-informed value aggregation. Then key-channel pruning, adaptive budgets, lossless offloading, and sparse prefill acceleration.
The last row is three methods in one line: three quantization approaches selected by a flag rather than by the method flag.
So the row count and the selectable method count are not the same, which is the first thing to get right when you count them.
Then the warning, which is in the same breath as the table. Attention paths for two model families are supported for the main compression methods, some newer methods have narrower runner and model coverage, and the file tells you to check the runner argument choices before launching large jobs.
That sentence is the honest limit of the whole project: one interface, seventeen methods, and a compatibility matrix nobody has finished.
The default cache layout is the one it calls legacy
One flag decides the physical layout of the cache, and its default value is the one described as legacy.
The default selects a per-query-head granularity. The alternative selects per key head, described as the layout that is efficient for grouped-query attention. The file is direct that the first is the legacy layout, which tells you two things: the newer layout is the one to reach for on a model that uses grouped queries, and switching is a deliberate act rather than an automatic improvement.
There is a companion flag for the alternative layout, and it exists because the change creates a new question. When scores are computed per query head but the cache is stored per key head, you have to reduce the first to the second. Three reductions are offered, a mean by default, a maximum, and a sum. The choice is not neutral: a mean and a sum behave differently under a heavy outlier.
Coverage is listed method by method rather than globally. Six methods support the alternative layout outright, and two more are listed with their validation pending on the GPU. Two others are absent from the list entirely.
Two details make this a well-built flag rather than a source of surprises. There is a separate document describing the layout, and all three runners accept the same pair of flags, so a needle-in-a-haystack run and a ruler run take the same arguments as a long-context benchmark.
Two methods pin the attention implementation in opposite directions
There are three attention implementations to choose from and the file documents which methods need which.
The three are the FlashAttention v2 path, the scaled dot product path, and the eager path. A news entry from June 2024 records adding the first two for four of the original methods, and says that on a GPU without FlashAttention v2 support you should set the dot product path instead.
Then two methods constrain the choice. The key-channel pruning method requires the eager path, which is the slow one, and the file gives no reason for it.
And the lossless offloading method requires the FlashAttention v2 path, for the opposite reason: it wants the fused kernel so the offload and prefetch overlap with compute.
So there is no single attention setting that runs every method. One of them needs the slowest path and one needs a specific kernel, and the file states both requirements in the same list without drawing the conclusion.
That matters for the group with restricted attention implementations. If your GPU cannot run FlashAttention v2, you are on the dot product or eager path, which rules out the offloading method outright and puts the key pruning method on the slow route.
The quickstart budget is a quarter of what the paper reports
The long-context quickstart sets a cache budget of 128 per layer, and the file then tells you the original paper reports at two budgets: 128 and 2048.
export CUDA_VISIBLE_DEVICES=0

python3 run_longbench.py \
  --method pyramidkv \
  --model_path /path/to/Llama-3-8B-Instruct \
  --max_capacity_prompts 128 \
  --attn_implementation flash_attention_2 \
  --save_dir ./results_long_bench \
  --use_cache True
So the number you will copy is the smaller of the two published figures. Nothing is wrong with that as a smoke test, and it is a sensible default for a first run. But a reader who quotes their 128 result as the headline number is quoting a different experiment from the one in the paper's table.
What the budget means also depends on the layout. The flag is a target per layer, and the pyramidal method redistributes the total across layers, so layers do not each hold the same amount. That is the method's whole idea, and it is why a per-layer number is the right unit to configure rather than a total.
Change the layout and you change what a budget is worth, because a per-query-head budget in a grouped-query model is not the same amount of stored state as a per-key-head one. Which is why the two flags are described together.
The quickstart also pins the dtype to the default of half precision, names the save directory, turns the cache on explicitly, and points at a local model path. The helper script takes the same settings positionally.
Quantization is a second axis with its own residual window
Most of the flag list is about which cache policy to run. A second group is about storing the cache in fewer bits, and it has more knobs than some of the policies do.
A method flag selects one of three quantization approaches. A separate bit width flag sets how many bits. A backend flag picks the quantization library, and the default is not the only option. Then there is a residual length flag: a window of the cache kept at full precision, and it defaults to the maximum number of tokens to be generated.
That default is worth pausing on, because it ties the precision of your cache to your generation length. Ask for a long generation and you silently get a larger full-precision window.
There are three advanced layout controls as well: a group size, and a key axis and a value axis. The file gives the defaults for one of the quantization methods, key axis one and value axis zero, which is the kind of detail you need and would otherwise spend a day discovering.
And one of the three methods accepts two arguments of its own, a rank and an outlier ratio.
So the full configuration surface is policy times layout times quantization, with a merge strategy available as well, chosen between two named strategies. The flags compose, and the file does not attempt to say which combinations have been tested together.
The helper script takes nine positional arguments and two of them are placeholders
There is a shell script that wraps the long-context runner, and its invocation is a single line of positional arguments.
bash scripts/scripts_longBench/eval.sh \
  0 pyramidkv 128 flash_attention_2 ./ /path/to/model none none 8
The example passes a device index, a method, a budget, an attention implementation, a source path, a model path, a merge method, a quantization method and a bit width. The order is documented in a sentence underneath, which is the only place the mapping exists.
Two of those nine values in the example are the word none. So the script's interface in practice is nine positional arguments where you must remember which two can be omitted and what string stands for omitted.
That is a real fragility, and it is worth naming because the failure is quiet. Passing the quantization method where the merge method belongs is not a parse error; it is a merge strategy named the same as a quantization method, or an argument the parser ignores.
The alternative, which the file also gives you, is to call the runner directly with named arguments. That is longer and it is the path that survives a refactor.
Both routes write into a save directory you name, which is the one piece of shared state between them.
The install steps put the repository on your Python path, because the runners are scripts at the root
The installation section is four commands: clone, change directory, install the requirements file, and then export the working directory onto the Python path.
git clone https://github.com/Zefan-Cai/KVCache-Factory.git
cd KVCache-Factory
pip install -r requirements.txt
export PYTHONPATH="$PWD:${PYTHONPATH}"
That last line tells you the shape of the project. This is not a package you install. There is no package entry point and nothing to import by name. The scripts that do the work live at the repository root, five of them: three runners for the long-context, ruler and needle-in-a-haystack evaluations, plus two evaluation modules. The original method's package directory is still there under its own name, which is what the Python path export makes importable.
So this is a bench you clone and run, not a library you depend on. That is entirely reasonable for a research harness, and it does mean your environment picks up whatever happens to be in the working directory.
The visualisation story follows the same pattern. There is a notebook and a utilities directory for reproducing attention maps, and generated maps go to a directory under the repository by default.
The root also carries the assets, figures and documentation directories, a tests directory, a separate file for the optional sparse-prefill integration, and a Chinese translation of the readme. There are no published releases, so a version of this bench is the commit you cloned.
The requirements block and the requirements file disagree, and two model SDKs are in the list
The requirements section prints three lines: an exact pin on the transformers library, torch with no version, and a floor on the FlashAttention package.
The requirements file has seventeen entries. It starts with the same transformers pin, except the previous pin is left there as a comment above it, which is what a version bump looks like when nobody cleaned up.
Then there are the evaluation libraries: a dataframe library, an array library, an evaluation harness, an acceleration library, a tokenizer library, a Chinese word segmenter, and four text similarity or scoring libraries. Two plotting libraries.
And two model provider SDKs, one for each of two providers, as runtime requirements of a harness whose purpose is local evaluation.
The attention library has a paragraph of its own, and it is the part worth reading. It must be installed manually after torch, with build isolation disabled, because it needs torch present at build time. It is optional if you use the dot product or eager path and required for the FlashAttention v2 experiments. And the optional sparse-prefill integration is deliberately kept out of the base file, in its own.
So: a three-line summary in the readme, a seventeen-line file with a stale comment, one package that must be installed in a specific order, and one method that needs a second install step.
Editorial conclusion
KVCache-Factory is worth adopting if you are comparing cache policies rather than shipping one, because the value is that every method meets the same three runners and the same flags. It is not a library to depend on: the install steps put the repository on your Python path rather than installing a package. Three things to check before a long job. Which methods your attention implementation supports, since two of them pin it in opposite directions. Whether the grouped-query cache layout you want is validated on your GPU, since two methods are marked as pending that check. And the cache budget number, because the quickstart value is a quarter of what the original paper reports and the two are not comparable without saying which layout you used.
Frequently asked questions
How many KV cache methods does KVCache-Factory support?
The table lists seventeen rows, spanning eviction and compression, retrieval, cross-layer sharing, merging, key-channel pruning, adaptive allocation, lossless offloading and sparse prefill. One row covers three quantization methods selected by a flag, so the number of rows and the number of selectable methods are not the same, and the file warns that some newer methods have narrower runner and model coverage.
Which attention implementation does KVCache-Factory use?
One of three, selected by a flag: the FlashAttention v2 path, the scaled dot product path, or the eager path. On a GPU without FlashAttention v2 support the file tells you to use the dot product path. The key-channel pruning method requires the eager path, and the lossless offloading method requires the FlashAttention v2 path, so no single setting runs every method.
How do I run the LongBench evaluation with KVCache-Factory?
The runner script at the repository root takes a method, a model path, a cache budget, the attention implementation and an output directory, with the dataset list defaulting to the full sixteen. The quickstart uses a budget of 128, while the original method's paper reports budgets of 128 and 2048.
Do I need to install anything special for KVCache-Factory?
Yes. The attention library must be installed manually after torch with build isolation disabled, and it is optional only if you use the dot product or eager path. The optional sparse-prefill integration lives in a separate requirements file. The install steps also put the repository on your Python path, because the evaluation runners are scripts at the root rather than an installed entry point.
What is the lossless method in KVCache-Factory?
Head-wise offloading of the KV cache to CPU memory with asynchronous prefetch. Because it keeps the full cache rather than approximating it, it ignores the cache budget argument entirely, and it requires the FlashAttention v2 attention implementation. It also needs the FlashAttention package installed, since it is not optional for that path.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/zefan-cai-kvcache-factory)Star history chart for your README
[](https://hysenlabs.com/projects/zefan-cai-kvcache-factory)Was this useful?