ChineseBQB generates its own directory and republishes every ZIP in one release
A museum of sticker packs - GitHub's most addictive repo, a huge collection of Chinese stickers for more joy.
At a glance
- What is it?
- ChineseBQB is a collection of Chinese sticker images rather than a program, and its interesting mechanics are the ones a dataset needs: a category table regenerated from the folders on disk, one rolling release holding a ZIP per category, two JSON files published as an open data source, and a numbering convention that lets new categories be added without renaming anything.
- Who is it for?
- ChineseBQB fits a developer who wants a labelled image set with per-category downloads, or someone who wants stickers for chat without hunting for them one by one. It does not fit a project that needs clear reuse terms: the repository's licence field is not filled in, while the readme describes the images and annotation data as fully open source and invites mini-program, crawler and machine-learning uses.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 10 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
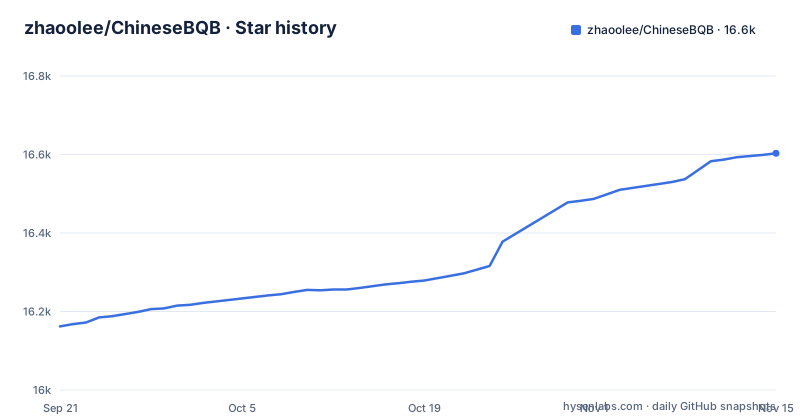
- zhaoolee/ChineseBQB16,603 ★ · +441
| Repository | 2026-09-21 | 2026-11-15 |
|---|---|---|
| zhaoolee/ChineseBQB | 16.2k | 16.6k |
441 Stars in the last 55 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The category table is regenerated from the folders on disk
The long table in the readme is not written by hand. It sits between comment markers that say it is updated automatically from the sticker folders, and the text above it states the totals: 5887 images across 115 categories. Each row has three cells, a preview, a link into the category on the web catalogue, and a direct download link for that category's ZIP archive. The ordering tells you how the collection grows. The rows start at 112 and descend, so categories are prepended rather than appended, and a new theme gets the next free number without disturbing the others. Folder names encode all three parts of the identity at once: a three-digit number, a Latin slug, and a Chinese label, with sizes such as five images in one category and 117 in another.
Every category ZIP lives under one rolling release
The download column is the part with a real consequence, and it is worth reading the shape of a link rather than one example. All of the direct links point at the same release, a single asset release whose name refers to the bundle of ZIPs, and each file name inside it carries the category number followed by a short hash. The release in the recent history is dated 2026-09-10, and the readme states that every release refreshes the catalogue and the indexes as well. Because everything is republished under the same release, the archive for a category can change whenever a new batch of stickers is published. If you are building something that depends on a specific set of images, save what you need at the time you take it rather than fetching the same URL later and expecting the same result.
Two JSON files are the part meant for reuse
The readme has a section that treats the collection as data rather than as a gallery. It names a category catalogue and a complete image index, both published as JSON and both refreshed on every release, and it explains how to resolve them: the image and category paths inside the index are relative, and you resolve them against a base address the readme gives. It then lists three kinds of downstream use, building a WeChat mini program, writing a crawler as a demonstration, and using the set as a machine-learning data source. That invitation is generous, and it is also where you should slow down. The repository's licence field is not filled in, while the text calls the images and annotation data fully open source. Whether that is enough for your use is a question for the person who owns the collection, not one the repository answers.
Contributions arrive through a folder and an email address
The intake process is visible in the layout. The numbered folders start at a folder whose name marks it as the contribution folder, with the Chinese word for contribution in its name, and everything above it is curated material. That gives a first-time contributor an obvious destination without any instructions. The second intake path is in the acknowledgements, where one contributor is thanked by name for a set of stickers sent by email, which tells you that material does arrive outside the repository and that somebody reads it. A third path sits in the social account the project runs, where the invitation is to comment with stickers and good ones get added. Three channels means three curation queues, and only one of them is version controlled, which is the part to keep in mind if you are building an ingestion pipeline.
Three gestures make the collection usable inside a chat app
A sticker collection only matters if you can get a sticker into a conversation, and the readme describes the web tool that exists for that purpose with numbered functions, the fourth being a sticker maker. The first is long-pressing a sticker to send it to a friend. The second is copying the sticker's link and pasting it into a social post, which is how sharing works without any download. The third is batch sharing, a single action that shares a keyword search page rather than one image, so a group of stickers travels as a link. A separate page gives a detailed introduction to the tool. Read together with the category archives, this is the whole consumption story: browse or search on the site, then send a link, and drop to ZIP downloads only when you want the files themselves.
The naming convention is bilingual, and an app grew out of it
Two details show how the project is maintained. The first is that folder names carry both a Latin slug and a Chinese label, sometimes with an emoji as well, so the tree reads as a bilingual glossary of themes rather than as opaque identifiers, and the numbering gives it an order. The second is a separate application built on the same idea: the author wrote an app for learning English through sticker images, distributed through the App Store, with a usage table in the readme. The readme also credits the visual identity to a designer, the founder of 方圆STU, and it states a permanent open-source address for the project on the code host, which is a sensible thing to write down given how often repositories move.
One release, a pushed branch, and a folder per theme
The release history tells you how this repository actually ships. There is a single release, an asset bundle of the sticker archives, rather than a stream of versioned releases, which is consistent with a collection where the interesting unit of change is a new batch of images rather than a new version of anything. The default branch was pushed on 2026-10-31 and the repository is not archived. The language recorded for the repository is Python, which fits the tooling rather than the content: the visible tree is folders of images, with the generation of the directory table and the archives being the part that is written in code. One last structural note for anyone automating against it, because it decides how you fetch things: the newest categories are at the top of the number range, so a crawler that walks the tree in ascending order will see the oldest material first.
Editorial conclusion
ChineseBQB fits a developer who wants a labelled image set with per-category downloads, or someone who wants stickers for chat without hunting for them one by one. It does not fit a project that needs clear reuse terms: the repository's licence field is not filled in, while the readme describes the images and annotation data as fully open source and invites mini-program, crawler and machine-learning uses. Before you build on the indexes, check the licence yourself, and pin your data locally rather than trusting a download link, because every category ZIP lives under one rolling release whose contents change when a new batch of stickers is published. The newest asset release is dated 2026-09-10 and the default branch was pushed on 2026-10-31.
Frequently asked questions
What is ChineseBQB?
It is a large collection of Chinese sticker images, described as a museum of stickers and organised into numbered folders by theme. The readme states that it holds 5887 images across 115 categories, with each category getting its own archive and its own page in the online catalogue.
How do I download a sticker category from ChineseBQB?
Each row of the generated directory table has a direct download link for that category's ZIP archive, and every one of those links points at the same rolling release, with file names carrying the category number and a short hash. Because the release contents change when new stickers are published, save the archive you need instead of re-fetching the same link later.
Can I use ChineseBQB data in my own project?
The readme invites three uses: building a WeChat mini program, writing a crawler as a demonstration, and using the set as a machine-learning data source. It publishes a category catalogue and a complete image index as JSON, refreshed on each release, with paths inside them resolved against a base address. Note that the repository's licence field is not filled in.
How do I contribute stickers to ChineseBQB?
The numbered tree starts with a folder whose name marks it as the contribution folder, which marks where contributed material goes. The readme also thanks a contributor who sent a set of stickers by email, and points at a social account where people are invited to comment with stickers, with good ones collected into the repository.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/zhaoolee-chinesebqb)Star history chart for your README
[](https://hysenlabs.com/projects/zhaoolee-chinesebqb)Was this useful?