FEDOT: evolutionary pipeline design for tabular, time series and hybrid models
Automated modeling and machine learning framework FEDOT
At a glance
- What is it?
- FEDOT is a BSD-3-Clause Python framework that searches for machine learning pipelines as graphs of preprocessing and model blocks using an evolutionary approach. Its fit/predict API is simple, but the timeout and preset settings decide what you actually get.
- Who is it for?
- Adopt FEDOT when you need the pipeline structure itself to be searchable (preprocessing plus model plus connections) and when you can budget wall-clock time for the evolutionary search. Skip it if you only need hyperparameter tuning of one fixed estimator, where Optuna or plain scikit-learn search is cheaper and easier to explain.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 4 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
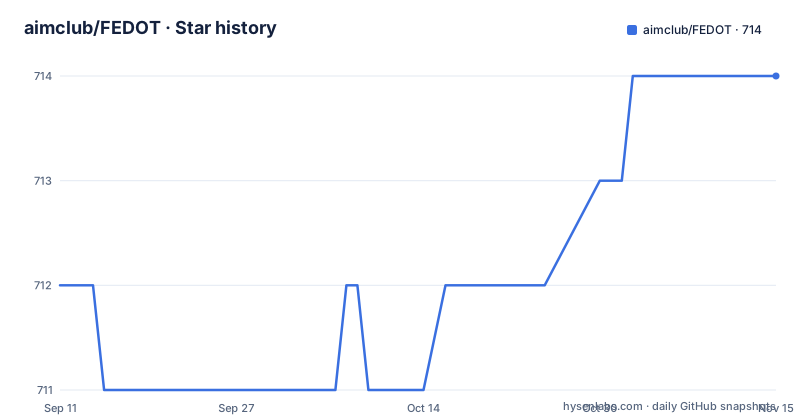
- aimclub/FEDOT714 ★ · +2
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| aimclub/FEDOT | 712 | 714 |
2 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem FEDOT targets: pipeline structure, not just hyperparameters
Most AutoML tooling tunes parameters inside a model you already chose. FEDOT instead treats the pipeline as a graph whose nodes are data preprocessing operations and model blocks, and whose edges define how data flows between them. The README calls this "automatic generative design of machine learning pipelines" and describes the key feature as "complex management of interactions between various blocks of pipelines." That distinction matters. If your problem needs a specific sequence (imputation, then encoding, then a model, then a postprocessing step), a hyperparameter search will never discover it, because the sequence is fixed before the search starts. FEDOT searches over that sequence. The stated task coverage is classification (binary and multiclass), regression, clustering, and time series prediction, which puts it in the same territory as general purpose AutoML rather than a single-task library. The intended user is someone who has data and a metric but not a strong prior about which combination of preprocessing and model will work, and who is willing to spend compute on structural search instead of manual experimentation.
Evolutionary search over graphs: what the repository material shows
The README states that the core is based on an evolutionary approach and that the pipeline is represented as a graph defining connections between data preprocessing and model blocks. The topics list on the repository confirms the vocabulary: evolutionary-algorithms, genetic-programming, structural-learning, hyperparameter-optimization. So there are two search dimensions running together, the structure of the graph and the parameters inside its nodes. The README also mentions "special strategies" for specific tasks or data types (time series forecasting, NLP, tabular data) as a way to improve efficiency, which implies the default search is task-agnostic and the strategies narrow it. The population size, the number of generations, the mutation or crossover operators, and how the timeout interacts with convergence live in the documentation and the source. Treat any claim about how many pipelines FEDOT evaluates in a given timeout as unverified until you read the code or run it yourself.
Installing and running the high-level API
Installation is a single pip command: pip install fedot. For image and text processing and for DNN support, the README gives pip install fedot[extra]. Docker images are also published, with a README under docker/ in the repository. The API is fit/predict. You import Fedot from fedot.api.main, construct it with a problem type and search budget, then call fit, predict and get_metrics. The README's own example is: model = Fedot(problem='classification', timeout=5, preset='best_quality', n_jobs=-1), followed by model.fit(features=x_train, target=y_train), prediction = model.predict(features=x_test) and metrics = model.get_metrics(target=y_test). Inputs can be NumPy arrays, Pandas DataFrames, or a file path. Three config keys are visible in that one line and they carry most of the operational weight: problem selects the task family, timeout is the wall-clock budget for the search, and preset selects a search configuration (best_quality here, with other presets referenced in the docs). n_jobs=-1 spreads work across all cores. The fit call returns the resulting composite pipeline, which the README says can be exported as JSON on its own or as a ZIP archive together with input data.
Where the abstraction leaks: timeouts, presets and unverifiable quality
The most honest limitation is built into the API surface. A timeout-based search returns whatever the best pipeline is when the clock runs out, not a converged optimum. The README's example uses timeout=5, which is a demonstration value, not a recommendation. A second limitation is the preset system. Choosing best_quality versus a cheaper preset changes the search space and the compute cost. Third, the framework's flexibility is also its risk: a graph search can produce pipelines that are hard to explain to a reviewer, and while JSON export makes the structure reproducible, reproducibility of the artifact is not the same as interpretability of the model. Finally, FEDOT is the wrong tool when your pipeline structure is already settled by domain constraints. If regulation or latency budgets fix the preprocessing chain, an evolutionary search over structures wastes compute on candidates you cannot deploy.
FEDOT versus hyperparameter-only tuning with Optuna
The clearest alternative for the tuning-only case is Optuna, a hyperparameter optimization library. The difference is the search space. Optuna searches over parameters you define, typically for one estimator or a small fixed pipeline, using samplers such as TPE and pruners that stop unpromising trials early. FEDOT searches over the pipeline graph itself, with hyperparameter optimization as one of the topics it covers rather than the whole story. If your problem is "which max_depth and learning_rate for this gradient boosting model," Optuna gives you a tighter loop and a clearer trial history. If your problem is "do I need scaling before this model, and does a lag transform before the forecast help," FEDOT's structural search addresses the question Optuna cannot. The trade-off is compute and transparency: graph search evaluates more expensive candidates, and the resulting pipeline needs the JSON export to be audited. The README positions FEDOT as supporting widely used libraries including Scikit-learn, CatBoost and XGBoost, so the two approaches are not mutually exclusive in practice; FEDOT can search structure and then you can tune the chosen model further with a dedicated tuner.
Maintenance, releases and the BSD-3-Clause licence
The repository is not archived and the last push recorded is 2026-09-09. Recent releases are v0.7.5 (2025-03-10), v0.7.4 (2024-08-28) and v0.7.3.2 (2024-05-03). That cadence, roughly one release per several months with a gap between v0.7.4 and v0.7.5, is worth noting if you plan to pin a version for a long-lived service. The project is maintained by the research team of the Natural Systems Simulation Lab at ITMO University's National Center for Cognitive Research, which suggests academic rather than commercial support expectations. The licence is 3-Clause BSD, a permissive licence that generally allows commercial use and modification provided the copyright notice and disclaimer are retained; the exact obligations are in the LICENSE file, and this is not legal advice. For upgrade cost, the practical signal is the release history: minor version bumps in the 0.7.x line have occurred at multi-month intervals, so pinning fedot to a specific version in requirements and testing upgrades deliberately is the lower-risk path than tracking master.
Who should adopt FEDOT, and what to check first
Adopt FEDOT if you have tabular or time series data, a metric, and genuine uncertainty about the right combination of preprocessing and model. The fit/predict API plus JSON pipeline export gives you a reproducible artifact to inspect. Do not adopt it if you already know the pipeline structure, if inference latency is tightly constrained, or if you need a vendor with a support contract. Before committing, verify three things on your own data. First, run the README example with a realistic timeout rather than timeout=5 and compare get_metrics() output against a tuned single-model baseline. Second, read the presets documentation to understand what best_quality actually changes. Third, export a fitted pipeline to JSON and confirm you can read the graph, because a pipeline you cannot explain is a pipeline you cannot defend in review. The BSD-3-Clause licence removes most distribution friction; the open question is whether the evolutionary search earns its compute on your specific dataset.
Editorial conclusion
Adopt FEDOT when you need the pipeline structure itself to be searchable (preprocessing plus model plus connections) and when you can budget wall-clock time for the evolutionary search. Skip it if you only need hyperparameter tuning of one fixed estimator, where Optuna or plain scikit-learn search is cheaper and easier to explain. Before committing, run the README's Fedot(problem='classification', timeout=5, preset='best_quality') example on your own data and check Fedot.get_metrics() against a tuned baseline, then export the resulting pipeline to JSON to confirm the graph is something you can inspect and reproduce.
Frequently asked questions
What problem types does FEDOT support?
The opening paragraph names classification for binary and multiclass, regression, clustering, and time series prediction. The API section names classification, regression and time series forecasting, leaving clustering out of that second list.
Which Python versions does FEDOT run on?
pyproject.toml sets requires-python to >=3.10,<3.15 and lists classifiers for 3.10 through 3.14. numpy, scipy and scikit-learn each switch to different version ranges on Python 3.13.
How do I install FEDOT with image and text support?
The README offers pip install fedot[extra] for the optional dependencies covering image and text processing and for DNNs. The plain install is pip install fedot.
Why does pip give me an older FEDOT than the repository shows?
The packaging metadata pins version 0.7.5, and v0.7.5 was published on 2025-03-10. The default branch carries newer commits, the most recent dated 2026-10-01.
Does FEDOT install test libraries as runtime dependencies?
Yes. pytest and testfixtures appear in the main dependencies list of pyproject.toml rather than in an optional group, so they arrive with a normal install.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/aimclub-fedot)Star history chart for your README
[](https://hysenlabs.com/projects/aimclub-fedot)Was this useful?