Alignment Handbook: Reproducible Post-Training Recipes for Open LLMs
Robust recipes to align language models with human and AI preferences
At a glance
- What is it?
- Hugging Face's Alignment Handbook offers step-by-step YAML-driven recipes for continued pretraining, SFT, DPO, and ORPO. It is a practical toolkit for teams that want to replicate models like Zephyr, not a research framework.
- Who is it for?
- Adopt the Alignment Handbook if you need to reproduce a known post-training pipeline (Zephyr, SmolLM, StarChat) on your own hardware or with your own dataset, and if you are comfortable with Python, PyTorch, DeepSpeed, and Hugging Face tooling. Do not use it if you want a plug-and-play GUI or if you need to train with a non-Hugging Face stack.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 52 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 12, 2026, and from our analysis. They are not legal advice.
Star history
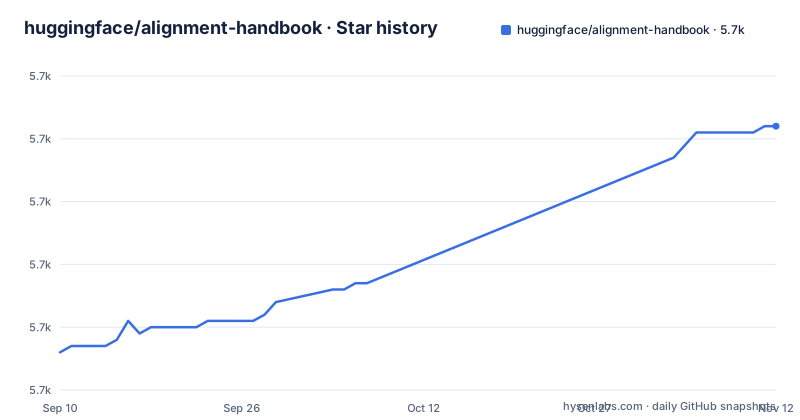
- huggingface/alignment-handbook5,712 ★ · +36
| Repository | 2026-09-10 | 2026-11-12 |
|---|---|---|
| huggingface/alignment-handbook | 5.7k | 5.7k |
36 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What the Handbook Actually Solves
The Alignment Handbook addresses a gap that appeared after ChatGPT and the Llama releases: many open models were fine-tuned only with supervised instruction data, but papers like InstructGPT and Llama 2 showed that adding preference alignment improves helpfulness and safety. Public, reproducible recipes for that alignment were scarce. The handbook fills that gap with a series of training pipelines that cover the full post-training stack, from continued pretraining to preference optimization. It is for engineers and researchers who want to train their own chat models, not for end users of chatbots. The target audience is someone who has a base model, a dataset, and access to GPUs, and who wants a proven path to an aligned model without inventing every hyperparameter from scratch.
The Architecture: Scripts, Recipes, and YAML
The project is intentionally simple. It contains two main directories. The scripts directory holds Python scripts for training and evaluation. Four training steps are supported: continued pretraining (causal language modeling), supervised fine-tuning for chat, preference alignment with DPO, and a combined SFT plus preference alignment with ORPO. Each script supports distributed training of full model weights using DeepSpeed ZeRO-3, or parameter-efficient training with LoRA or QLoRA. The recipes directory contains one subdirectory per reproduced model, such as Zephyr-7b-beta, SmolLM, or StarChat2. Each recipe is a YAML file that captures all parameters for a single training run. This separation means that the code is generic and the specificity lives in the configuration. To train a model, you pick a recipe and run the corresponding script with that YAML. The design is close to a Makefile approach: the logic is fixed, and the recipe is the input.
Getting It Running: Installation and Reproducibility
The README gives a concrete installation path. You start by creating a Python 3.11 virtual environment with uv, then install PyTorch 2.6.0 from the CUDA 12.6 index. The version is pinned for reproducibility, which is a strong point. Next you install the package itself with uv pip install ., then Flash Attention 2.7.4.post1 with --no-build-isolation. You log in to the Hugging Face Hub with huggingface-cli login, and install Git LFS so you can push models. After that, you follow a recipe's README. For example, to replicate Zephyr-7b-beta, you go to recipes/zephyr-7b-beta and follow its instructions. The installation is not trivial; it requires a GPU with supported CUDA, and Flash Attention is a known source of build problems. The README warns that the PyTorch version is hardware-dependent and points you to the official PyTorch installation page if your setup differs.
The Recipes: From Zephyr to SmolLM3
The handbook's value is in its recipes, which are tied to real released models. The news section lists several: Zephyr 7B Beta (November 2023), Zephyr 7B Gemma (March 2024), StarChat2 15B (March 2024), Zephyr 141B (A35B) with ORPO (April 2024), SmolLM-Instruct v0.2 (August 2024), SmolLM2-Instruct (November 2024), and SmolLM3-3B (July 2025). Each recipe takes the form of a YAML file which contains all the parameters associated with a single training run. Alongside the Zephyr-7b-β training code, the team released No Robots, a dataset of 10,000 instructions and demonstrations written by skilled human annotators. The SmolLM3 recipe is described as a full post-training recipe behind a state-of-the-art hybrid reasoning model. These recipes are not abstract examples; they are the exact configurations used to produce the released models. That is the core promise: you can reproduce a known model, not just follow a generic tutorial.
A Real Limitation: It Is Not a Library
The handbook is a collection of scripts and configs, not a framework with a clean API. You will be editing YAML files and reading Python scripts. The README says the project is simple by design, which is a strength for transparency but a weakness for integration. If you want to change a loss function or add a new alignment method, you must modify the scripts. Also, the recipes are tied to Hugging Face ecosystem components: transformers, datasets, and the Hub. If your stack is not Hugging Face-centric, you will fight the tooling. The README points to a separate dataset formatting guide for custom chat datasets, so you must follow the link.
Alternatives: What Else Exists and How It Differs
The most direct alternative is to use the TRL library directly, which provides the underlying training methods (SFT, DPO, ORPO) as Python classes. If you want full control over the training loop, you would use TRL's Trainer classes and write your own configuration. Another alternative is to use Axolotl, a popular open-source fine-tuning framework that also uses YAML configs and supports SFT, DPO, and other methods. The key difference is that Axolotl is a standalone framework, whereas the Alignment Handbook is a set of scripts that you are expected to read and modify. If you want to reproduce a specific Hugging Face model exactly, the handbook is the better choice. If you want a standalone framework rather than scripts to modify, Axolotl may be more suitable.
Maintenance and License Considerations
The repository is actively maintained; the last push was September 2026, and the news items list new recipes through July 2025. The project is not archived. However, there are no formal releases or version tags listed, so you cannot pin to a stable release. You must clone the main branch or use a specific commit. This is a maintenance cost: recipes may change as new models are added, and the installation steps may evolve. The license is Apache-2.0, which is permissive for commercial use, but note that the models and datasets referenced in the recipes have their own licenses. For example, the No Robots dataset has its own terms, and base models like Llama have their own licenses. The handbook's code is Apache-2.0, but you must check the license of any model you fine-tune and any dataset you use. The README does not provide legal advice, and neither does this review. The practical implication is that you can freely use the code, but your trained model may be subject to the base model's license.
Who Should Use It and What to Verify First
The handbook is best for a team that wants to replicate a specific aligned model on its own infrastructure, or that wants a proven starting point for custom post-training. It is less suitable for someone who wants to experiment with a novel alignment objective, because that would require writing new training logic. Before adopting it, verify that your GPU supports Flash Attention and that you can install the pinned versions of PyTorch and Flash Attention. Also, check the dataset licenses for the recipe you plan to use; some datasets are research-only. If you plan to train on your own data, read the dataset formatting guide in scripts/README.md. Finally, note that the handbook assumes a Hugging Face account and Git LFS for pushing models, so your workflow must include those tools.
Editorial conclusion
Adopt the Alignment Handbook if you need to reproduce a known post-training pipeline (Zephyr, SmolLM, StarChat) on your own hardware or with your own dataset, and if you are comfortable with Python, PyTorch, DeepSpeed, and Hugging Face tooling. Do not use it if you want a plug-and-play GUI or if you need to train with a non-Hugging Face stack. Before you start, verify that your GPU driver and CUDA version match the pinned PyTorch 2.6.0 and Flash Attention 2.7.4, and that you have enough VRAM for either full fine-tuning with ZeRO-3 or for LoRA/QLoRA. The handbook is a recipe collection, not a library; you will be editing YAML files and reading scripts, not calling a high-level API. Its value is in the exact, tested configurations, so follow the installation steps as written or expect to debug environment issues.
Frequently asked questions
What is the Alignment Handbook?
A set of training recipes covering the whole post-training pipeline. The scripts directory holds code for four steps, continued pretraining, supervised fine-tuning for chat, preference alignment, and a combined fine-tune-and-align step, each supporting full-weight distributed training or parameter-efficient tuning. The recipes directory holds one configuration file per published model.
Which alignment techniques does the handbook cover?
Six, as listed: continued pretraining, supervised fine-tuning with advice on collecting and curating data, reward modelling, rejection sampling as a way to improve an already fine-tuned model, direct preference optimisation described as an alternative to the earlier policy-gradient approach, and odds-ratio preference optimisation, which combines fine-tuning and preference optimisation in one stage.
What does installing the Alignment Handbook require?
A virtual environment on one specific interpreter version created with a particular Python tool, an exact build of the deep learning framework from an index chosen for a specific accelerator build, the project itself, a pinned build of an attention library installed with build isolation switched off because it compiles, a login to the model hub, and the large-file extension for git installed through the system package manager.
How do I train the Alignment Handbook on my own dataset?
The page points at the dataset formatting instructions in the scripts directory for fine-tuning on your own data. For adaptation rather than chat, it includes a gpt2-nl recipe to illustrate the sequence: continue pretraining on the new language or domain, then fine-tune and align the result.
How is the Alignment Handbook packaged and released?
With no tagged releases. Packaging uses a setup script next to a setup configuration file, and the script removes a stale generated metadata directory before it runs. A make target drives version bumps through a release script, separate targets build and clean the distribution artefacts, and two upload targets exist, one for the main index and one for the test index.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/huggingface-alignment-handbook)Star history chart for your README
[](https://hysenlabs.com/projects/huggingface-alignment-handbook)Was this useful?