rag-all-in-one Is a Curated RAG Directory, Not a RAG Framework
🧠 Guide to Building RAG (Retrieval-Augmented Generation) Applications
At a glance
- What is it?
- lehoanglong95/rag-all-in-one is a component-by-component index of RAG tooling, courses and frameworks maintained by one machine learning engineer. The judgement: useful as a discovery map when you are scoping a pipeline, useless as an installable dependency, and it ships no licence.
- Who is it for?
- Adopt it as a reading list if you are scoping a RAG pipeline and want one page that groups ingestion, chunking, retrieval, query transform, vector databases, embeddings, fine-tuning, observability, prompting, evaluation and UI tools under named headings. Do not adopt it if you need code you can import, a pinned dependency set, or a licence you can point a legal reviewer at: the repository is a markdown directory with no stated licence and no releases.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 179 days ago.
- What is it written in?
- GitHub does not report a main language for this repository.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
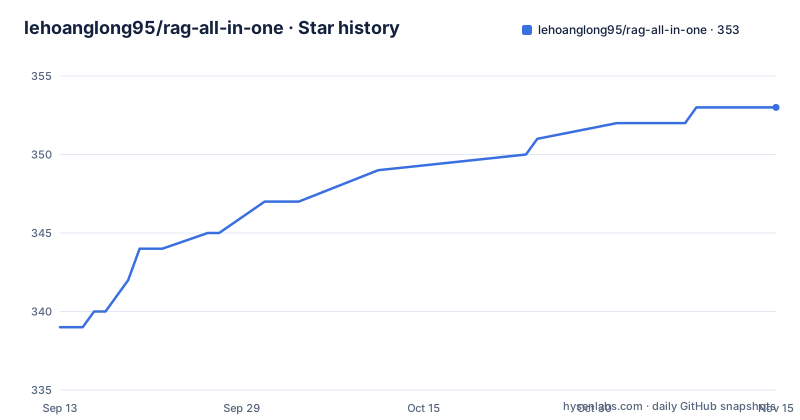
Star history
- lehoanglong95/rag-all-in-one353 ★ · +14
| Repository | 2026-09-13 | 2026-11-15 |
|---|---|---|
| lehoanglong95/rag-all-in-one | 339 | 353 |
14 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem rag-all-in-one addresses is tool sprawl, not retrieval quality
A RAG pipeline is assembled from at least six separate decisions: how documents are parsed, how they are chunked, which embedding model produces vectors, which store holds them, how queries are rewritten, and which model generates the answer. Each decision has a dozen credible options, and the options change every few months. The README frames the repository as "a centralized directory to help you discover the most relevant technologies for each part of your RAG pipeline," which is a narrower ambition than the title suggests. It is a map of the territory, not a vehicle.
The intended reader is someone who already understands what retrieval-augmented generation is and needs to enumerate the choices. The courses table reinforces that: entries are labelled Beginner, Intermediate, Intermediate to Advanced, and they point at DeepLearning.AI, Udemy, Coursera, DataCamp, Pluralsight, edX, Activeloop and Zero to Mastery. If you are trying to pick a first course, the table gives you platform, description and level in one row. If you are trying to ship a service this week, the table gives you nothing you can run.
How the directory is organised, and what that reveals about its scope
The README defines fifteen component categories in a single table, each linking to a section further down: Courses and Learning Materials, Document Ingestor, Chunking Techniques, Retrieval, Query Transform, Agent Framework, Database, LLM, Embedding, Fine-tuning, LLM Observability, Prompt Techniques, Evaluation, User Interface, and Complete RAG Applications. That ordering roughly follows the data path of a RAG system, from raw documents through chunking and retrieval to generation and then to the operational concerns of observability and evaluation.
The Retrieval row is the one place the README names a specific library in the category description itself, stating that the section covers "Advanced techniques and methods for retrieving relevant information in RAG systems using LlamaIndex." Treat that as a signal about the author's familiarity rather than a constraint on the section. The Agent Framework row is described as "End-to-end frameworks for building RAG applications. Unified solutions for RAG implementation," which is where a reader looking for an installable toolkit would be sent.
The repository also ships a RAG Diagram.png referenced from the architecture section. The README embeds it with a relative path containing a space, RAG%20Diagram.png, which works on GitHub but breaks in many static site generators and in plain markdown renderers unless the URL is encoded correctly. That is a small thing.
Getting it running means cloning markdown, not installing a package
There is no package to install. The repository has no package manifest and no release artefacts. The only homepage listed is the author's LinkedIn profile, not a documentation site. So the realistic workflow is a clone and a read:
git clone https://github.com/lehoanglong95/rag-all-in-one.git cd rag-all-in-one
The value then lives entirely in the README and whatever section files sit alongside it. Because the project is organised as a directory of links, the practical way to use it is to fork it and prune: delete the categories your system does not have, replace the entries you have already chosen with your actual selection, and keep the rest as a backlog of alternatives to evaluate later. A fork also solves the broken-image problem above, since you control the asset path.
One caution about link rot. A directory of external links decays as vendors rename products, move documentation and retire courses. The freshness of any given row is something you verify by clicking, not something the repository guarantees. The last push date is 2026-05-20, which tells you the repository was touched recently but says nothing about whether every link in it still resolves.
The licence gap is the first thing a team should resolve
The licence field is unknown. For an individual reading a list of links this is mostly academic. For a company, it is a blocker on any use beyond reading, because the default position under most jurisdictions is that no licence means no granted rights, even for a repository that is publicly visible.
That is not legal advice, and the practical answer is simple: ask the author. The README invites contact through LinkedIn and GitHub, and adding a LICENSE file is a two-minute change. Until that happens, treat the repository as reference material you read in a browser rather than content you vendor into an internal handbook or redistribute.
There is a second, subtler cost. Because the project is a curated list, its maintenance burden is editorial rather than technical. Every new vector database, every embedding model release and every framework rename creates work. That work is invisible in a commit history that mostly adds and removes table rows, and it is the kind of work that stops when the maintainer's attention moves elsewhere. A single-maintainer directory is not a criticism of this particular project; it is the structural risk of the format.
Where a directory stops being the right tool
The failure mode is a reader who wants the directory to be a starting template. It is not. If you clone it expecting a working pipeline, you will find tables of links and a diagram. There is no ingestion script, no chunking implementation, no retrieval code and no evaluation harness in the repository. The Complete RAG Applications category points outward at other projects; it does not contain one.
A second limitation is depth. A row in a table can tell you that a tool exists and roughly what category it belongs to. It cannot tell you how that tool behaves when your documents are scanned PDFs with tables, or what happens to retrieval quality when your chunks are 2,000 tokens instead of 500. Those are the questions that decide whether a RAG system works, and they are answered by running evaluations, not by reading a directory. The repository routes you toward evaluation tooling; it does not evaluate anything for you.
Use it as the wrong tool when you need reproducibility. A directory has no version pinning, so two engineers reading it a month apart may see different links and reach different conclusions about what is current.
LlamaIndex and LangChain solve the adjacent problem, and the difference matters
The obvious comparison is a framework such as LlamaIndex or LangChain, both of which appear in the README as subjects of courses and as the named library behind the Retrieval category. The difference in approach is stark. A framework gives you abstractions you import: document loaders, node parsers, index classes, retrievers and query engines, wired together with code you write and debug. rag-all-in-one gives you names.
That distinction determines which one you reach for. If your question is "how do I chunk these documents and query them by tomorrow," a framework answers it and the directory does not. If your question is "what are the credible options for query transformation, and which of them have courses or documentation I can read before committing," the directory answers it faster than reading framework docs, because the options are laid out side by side rather than embedded in one vendor's API surface.
There is a middle position worth naming. The Agent Framework and Complete RAG Applications categories exist precisely because some readers want an end-to-end solution rather than a component. The directory's contribution there is comparative: it puts end-to-end options in one place so you can see how many exist before picking one. That is a real service, and it is the service a framework cannot provide about itself.
Upgrade cost and the maintenance question
Upgrading rag-all-in-one means pulling the latest commit and re-reading the sections you care about. There is no migration path because there is no API. The cost is your attention, and it scales with how many categories you follow.
The more useful question is what the repository costs you if you adopt it as a team reference. A directory that lives in a wiki goes stale silently. A directory cloned into a repository and pinned to a commit stays accurate to that commit and drifts from reality. Neither is free. The cheapest sustainable pattern is to fork, keep only the categories your system actually has, and treat the rest as an inbox rather than a reference. That way the stale rows are the ones you have not adopted yet, not the ones you depend on.
Because the repository has no published GitHub releases, there are no version tags to pin against. If you fork, record the commit hash you forked from in your own README so future readers can see which snapshot of the directory informed your decisions.
Editorial conclusion
Adopt it as a reading list if you are scoping a RAG pipeline and want one page that groups ingestion, chunking, retrieval, query transform, vector databases, embeddings, fine-tuning, observability, prompting, evaluation and UI tools under named headings. Do not adopt it if you need code you can import, a pinned dependency set, or a licence you can point a legal reviewer at: the repository is a markdown directory with no stated licence and no releases. Before relying on it, check the RAG Diagram.png asset actually renders in your fork and confirm the licence status with the author.
Frequently asked questions
Does rag-all-in-one contain any runnable RAG code?
No. The repository holds README.md and RAG Diagram.png, and the content is a categorised link list of tools, courses and books. There is nothing to install and no command to run.
How does rag-all-in-one organise its tool list?
Into fifteen component rows following a RAG pipeline: document ingestor, chunking techniques, retrieval, query transform, agent framework, database, LLM, embedding, fine-tuning, LLM observability, prompt techniques, evaluation, user interface, complete RAG applications, and courses and learning materials.
Which libraries do the courses in rag-all-in-one actually teach?
The descriptions name LlamaIndex for retrieval, LangChain and Deep Lake for production-oriented work, Pandas, SentenceTransformers and Qdrant for an end-to-end build, LLMWare for a beginner path, and contrastive learning for a multimodal search and RAG course.
Can I reuse the list of links compiled in rag-all-in-one?
Nothing in the repository asserts a licence, so there is no stated permission for redistribution. There are also no releases, so there is no version to pin and no record of when each link was last confirmed.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/lehoanglong95-rag-all-in-one)Star history chart for your README
[](https://hysenlabs.com/projects/lehoanglong95-rag-all-in-one)Was this useful?