llm-datasets: A Field Guide to Post-Training Data, Not a Silver Bullet
Curated list of datasets and tools for post-training.
At a glance
- What is it?
- Maxime Labonne's curated list of datasets and tools for LLM post-training is a useful starting point, but its value depends on how critically you read it.
- Who is it for?
- Adopt llm-datasets if you are building or fine-tuning an LLM and need a quick, human-curated map of recent SFT and reasoning datasets, especially those with permissive licenses. Do not rely on it as a definitive catalog: it flags licence exceptions only inline, and links to datasets that may change or disappear.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Activity is slowing. The repository last received commits 6 months ago.
- What is it written in?
- GitHub does not report a main language for this repository.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
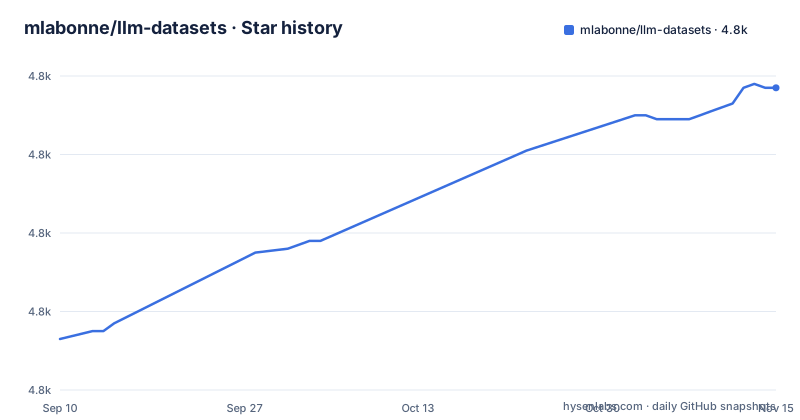
- mlabonne/llm-datasets4,837 ★ · +64
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| mlabonne/llm-datasets | 4.8k | 4.8k |
64 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What This List Actually Solves
The README addresses a real bottleneck in LLM development: finding good data for supervised fine-tuning. After pre-training, a model needs instruction-following data, and the ecosystem on Hugging Face is vast and noisy. This repository curates a subset of datasets and tools, organized by domain. It is aimed at engineers and researchers who are about to fine-tune a model and want to avoid scanning hundreds of dataset cards manually. The list is not exhaustive, and it is not a benchmark. It is a hand-picked index with notes on size, whether the data includes reasoning traces, and the license when known. For someone new to post-training, it offers a structured entry point. For a veteran, it may surface datasets released in the last few months that they had not seen.
The Three Quality Criteria the Author Pushes
The README opens with a clear stance on what makes a good dataset: accuracy, diversity, and complexity. Accuracy means samples are factually correct and relevant, which the author suggests can be enforced with solvers for math and unit tests for code. Diversity is about covering many use cases to avoid being out of distribution. Complexity covers multi-turn dialogue, multilingual text, and step-by-step reasoning. These three criteria are sensible, but they are also a filter for the curator's own taste. The list favors datasets that include reasoning traces, marked as 'Thinking: Yes' in the tables. That is a bias toward the current fashion for reasoning models. If you are fine-tuning a small model for a narrow task, a simple instruction dataset might serve you better.
How the Datasets Are Organized and What the Tables Tell You
The repository is structured as a set of markdown tables, each under a category heading. The categories include General, Math, Science, and Code. Each row gives the dataset name, a link to its Hugging Face page, the number of samples, a 'Thinking' flag, and notes. The notes often mention the model that generated the data, the license, and related resources. For example, the Nemotron-Cascade-2-SFT-Data entry notes that responses were generated from DeepSeek-V3.2, GPT-OSS-120B, and Qwen3. That kind of provenance is useful when you need to match data to your base model. The sample counts are rounded, and the dates in parentheses indicate when the dataset was released or updated. The list appears to be updated frequently; the last push to the repository was in April 2026, and some entries are dated March 2026. That freshness is a strength, but it also means the list is a moving target.
Getting It Running: There Is No Code to Run
This is not a software project in the usual sense. There is no installation, no command-line tool, no configuration file. The repository is a document, so 'getting it running' means opening the README on GitHub and following the links. Each dataset link goes to a Hugging Face page where you can download the data or load it with the datasets library. That is fine for a curated list, but it means the project does not provide any tooling to filter, mix, or deduplicate the datasets it lists. You have to bring your own pipeline. If you were hoping for a ready-made data preparation workflow, this is not it.
Licenses: A Patchwork That Needs Your Attention
The README states that unless specified otherwise, all datasets listed are under permissive licenses like Apache 2.0, MIT, or CC-BY-4.0. But the tables show exceptions. The Dolci-Instruct-SFT entry is marked CC-BY-NC-4.0, which is non-commercial. The MegaScience entry is CC-BY-NC-SA-4.0, which adds share-alike and non-commercial terms. Nemotron-Math-Proofs-v1 is CC-BY-SA-4.0, which is share-alike but allows commercial use if you share derivatives under the same license. Nemotron-Cascade-2-SFT-Data and Nemotron-SFT-Math-v3 use the NVIDIA Open Model License, which is not a standard open-source license and has its own restrictions. The README does not explain these differences. It simply flags them in the notes. That is a responsible approach, but it places the burden on you to read each license carefully. If you are building a commercial product, a dataset marked CC-BY-NC is a dealbreaker unless you pay for a different license. The list does not tell you which datasets are safe for commercial use. You have to check each one.
What Is Missing: Preference Data and RLHF Are Absent
The README's first dataset section, Instruction Datasets, covers supervised fine-tuning, which is one stage of post-training. Within it, the Nemotron-Cascade-2-SFT-Data entry points to a separate Nemotron-Cascade-2-RL-data dataset. Check the README's later sections for other post-training stages, such as preference data, before treating the list as SFT-only.
The Alternative: Going Directly to Hugging Face and Papers
The obvious alternative is to search Hugging Face yourself, using filters for dataset size, license, and task. The difference is that llm-datasets adds a layer of human judgement: the notes tell you which model generated the data, whether it includes verified reasoning traces, and whether it was used to train a known model. For example, the NuminaMath-CoT entry notes that it was used to win the first progress prize of the AI Math Olympiad. That kind of context is hard to get from a raw search. Another alternative is to follow the papers and blog posts that the datasets come from, such as the SYNTHETIC-2 release post or the MathX-5M page. Those sources give you deeper detail on filtering methodology and ablation studies. The trade-off is time. The curated list saves you from scanning dozens of dataset cards, but it gives you less depth than reading the original paper. For a quick survey, the list wins. For a deep dive, go to the source.
Maintenance and Upgrade Cost: It Is a Living Document, Not a Dependency
Because this is a markdown file, the maintenance cost is low for you. There is no code to update, no API to track. The risk is that the list becomes stale or links break. The repository was pushed to in April 2026, and several entries are dated March 2026, so it appears actively maintained. But you cannot rely on that forever. The author may stop updating it, and some Hugging Face datasets get taken down or replaced. The orca-agentinstruct-1M-v1 entry links to a 'cleaned' version, orca-agentinstruct-1M-v1-cleaned. There is no versioning scheme for the list itself. If you use it as a reference, you should check the commit history or the last push date to see how fresh it is. The repository does not state a licence and has no LICENSE file, only README.md and CITATION.cff, so you should assume the text is under the author's copyright. That is a minor point, but it matters if you plan to copy the list into your own documentation.
Who Should Use This and Who Should Not
Use this list if you are fine-tuning a model and need a broad survey of what is available in math, code, science, and general instruction following. It is especially useful if you want datasets with reasoning traces, because the 'Thinking' column lets you filter for that. Do not use it as your only source of data. The list does not evaluate quality beyond the author's own criteria, and it does not compare datasets on downstream performance. Before you commit to any dataset, verify the license, check the actual sample count on the Hugging Face page, and run a small experiment to see if the data matches your model's style. The list is a map, not a destination.
Editorial conclusion
Adopt llm-datasets if you are building or fine-tuning an LLM and need a quick, human-curated map of recent SFT and reasoning datasets, especially those with permissive licenses. Do not rely on it as a definitive catalog: it flags licence exceptions only inline, and links to datasets that may change or disappear. Before using any dataset, verify its license on the Hugging Face page, check the exact sample count and format, and test a small sample against your own quality criteria. The list is a starting point for exploration, not a substitute for your own data diligence.
Frequently asked questions
What datasets does llm-datasets list for supervised fine-tuning?
It groups instruction datasets by domain, with General, Math, Science and Code sections. General entries include Nemotron-Cascade-2-SFT-Data at 15.87M samples, SYNTHETIC-2-SFT-verified at 4M, Dolci-Instruct-SFT at 2.15M and open-perfectblend at 1.42M, each row carrying a sample count, a Thinking flag and license notes.
How do I choose a good dataset for fine-tuning an LLM?
The list targets three characteristics: accuracy, meaning samples are factually correct and relevant, with solvers used for math and unit tests for code; diversity, covering as many use cases as possible to avoid being out of distribution; and complexity, meaning multi-turn, multilingual, well-written samples with step-by-step reasoning when relevant. Quality comes from combining manual reviews, rule-based filtering heuristics, and scoring via judge LLMs or reward models.
What licenses are the datasets in llm-datasets under?
Unless specified otherwise the list says all datasets are under permissive licenses such as Apache 2.0, MIT and CC-BY-4.0. Exceptions are marked inline, including the NVIDIA Open Model License on Nemotron entries, CC-BY-NC-4.0 on Dolci-Instruct-SFT, CC-BY-SA-4.0 on Nemotron-Math-Proofs-v1 and CC-BY-NC-SA-4.0 on MegaScience, so the annotation on each row is what decides.
Does llm-datasets contain code or tools I can install?
No. The repository has only README.md and CITATION.cff, with no code, no releases and no license file of its own. It is a curated document, and the datasets themselves are resolved on the model hub from the links in each row.
What datasets are used for LLMs?
The list names several for the supervised fine-tuning stage, spanning general mixtures such as Nemotron-Cascade-2-SFT-Data, SYNTHETIC-2-SFT-verified and open-perfectblend; math sets such as MathX-5M, Nemotron-SFT-Math-v3, OpenThoughts3-1.2M and NuminaMath-CoT; and science sets such as MegaScience and Nemotron-Science-v1. Each row records the sample count, whether it includes reasoning traces, and its license.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/mlabonne-llm-datasets)Star history chart for your README
[](https://hysenlabs.com/projects/mlabonne-llm-datasets)Was this useful?