TensorRT LLM: What the Repository Actually Commits To
TensorRT LLM provides users with an easy-to-use Python API to define Large Language Models (LLMs) and supports state-of-the-art optimizations to perform inference efficiently on NVIDIA GPUs. TensorRT LLM also contains components to create Python and C++ runtimes that orchestrate the inference execution in a performant way.
At a glance
- What is it?
- TensorRT LLM is NVIDIA's Python-first stack for defining and serving LLMs and visual generation models on its own GPUs, with a C++ runtime underneath. The API surface is approachable, the hardware and version requirements are not.
- Who is it for?
- Adopt it if you are already committed to NVIDIA GPUs and want a Python API over specialized kernels and an efficient runtime, and if you can match the torch>=2.14.0a0,<=2.14.0 pin and cu132 wheel index in requirements.txt. Do not adopt it if you need a multi-vendor serving stack or a stable tagged release today, since the newest tags are release candidates.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
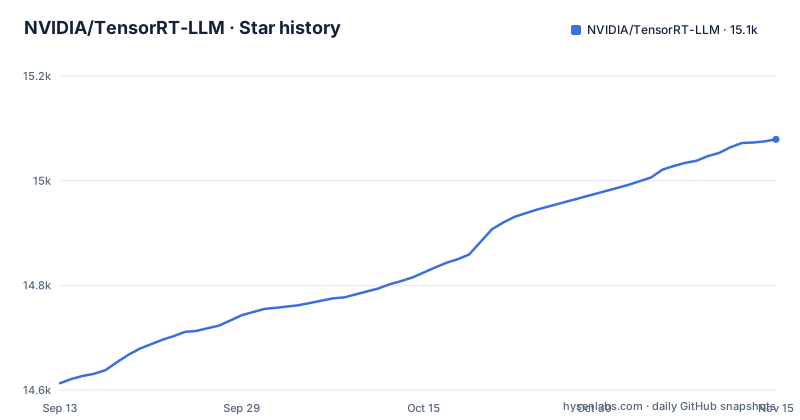
- NVIDIA/TensorRT-LLM15,079 ★ · +466
| Repository | 2026-09-13 | 2026-11-15 |
|---|---|---|
| NVIDIA/TensorRT-LLM | 14.6k | 15.1k |
466 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The gap TensorRT LLM is aimed at
Running a large language model on a GPU and running it well are different problems. A PyTorch model loaded onto a device will produce tokens, but the kernels, the memory movement and the scheduling between requests are generic. TensorRT LLM exists to replace that generic path with specialized kernels for common operations plus a runtime that orchestrates execution. The README states this directly: the project optimizes inference for LLMs and visual generation models with specialized kernels, an efficient runtime, and a pythonic framework you can customize and extend. The intended user is an engineer who has already decided the workload belongs on NVIDIA hardware and now cares about what happens between the request and the token. This is not a library for someone comparing accelerators. It is a library for someone who has picked one and wants the last layer of performance out of it.
Two layers: a Python definition API and a C++ runtime
The architecture visible in the README is a split. On top, a Python API lets you define a large language model. Below it, components create Python and C++ runtimes that orchestrate inference execution. That split matters for how you would adopt it. The Python layer is where model definitions and customization live, which is why the project describes the framework as pythonic and extensible. The runtime layer is where the scheduling and execution decisions happen, and it is available in both Python and C++ so that a serving process does not have to be a Python process. The repository layout reinforces this: the version string lives at tensorrt_llm/version.py, and the README links to a developer-guide overview page for architecture and a separate performance overview page. The README also points to DeepWiki for generated documentation, which is a reasonable signal that the codebase is large enough that the maintainers expect readers to need a map. For kernel-level detail the README points to the tech blog series, which covers topics such as sparse attention, skip softmax attention, expert parallelism, disaggregated serving and speculative decoding.
Version pins you inherit on day one
The badges in the README are not decoration; they are the support matrix. Python 3.12 and Python 3.10 are both listed. The CUDA badge links to the CUDA downloads page, and requirements.txt pulls PyTorch wheels from the cu132 index. requirements.txt pins torch>=2.14.0a0,<=2.14.0. The release badge links to tensorrt_llm/version.py, and the newest release tag is v1.4.0rc2. That is a narrow set of combinations, and it is the first real constraint you meet. If your serving environment runs an older CUDA toolkit, or a PyTorch build outside the 2.14.0 range in requirements.txt, check the documentation for a fallback path. The documentation linked from the README is the place to confirm whether other combinations are supported; the README itself presents these as the versions. Treat the badge list as a compatibility statement rather than a suggestion, and check it against your container base image before you plan anything else. The README blog index, with several Blackwell-specific posts, also tells you where the optimization effort is concentrated.
Getting it running: what the repository gives you
The README provides a quick-start guide link, an examples link and a documentation link, and the installation commands live in that guide. What can be stated is the shape of the setup. The README badges point to Python 3.10 and 3.12, and requirements.txt pins torch>=2.14.0a0,<=2.14.0 with wheels from the PyTorch cu132 index. The version of the library you are targeting is recorded in tensorrt_llm/version.py, and the newest release tag is v1.4.0rc2. The README's own entry points for a first run are the quick-start guide and the examples directory, and the architecture overview is a separate page under the developer guide.
The release cadence is a release candidate cadence
The three most recent releases are v1.4.0rc2, v1.4.0rc1 and v1.4.0rc0, dated 2026-10-28, 2026-10-22 and 2026-10-14. All three carry the rc marker. So the current published state of the project is a release candidate line, not a stable 1.4.0. That is a specific operational fact with a specific consequence: if your policy is to deploy only stable tags, the newest release candidate is not available to you, and the gap between rc0 and rc2 is two weeks. The cadence is fast enough that pinning to a single rc and reading the diff before moving is a reasonable posture. It also means bug reports and behavior changes land against a moving target. None of this is unusual for a project tracking new GPU generations, but it does mean the phrase latest release and the phrase stable release refer to different commits here.
Where this is the wrong tool
The most obvious failure mode is hardware. Every optimization described in the README and the blog index assumes an NVIDIA GPU, and several README blog posts name Blackwell specifically. If your fleet is mixed, or if you need one serving stack across more than one accelerator vendor, this project does not solve that problem and does not claim to. A second limitation is scope: the project targets LLMs and visual generation models, so a conventional encoder-only classification model or a non-generative workload gets nothing from specialized decoding kernels. A third is the release-candidate status described above. A fourth is documentation shape. The README is largely an index of blog posts and links, with the technical detail living in a separate documentation site and in DeepWiki. That is workable when the docs site is current, and the README itself notes in a comment that blog links point at GitHub until the doc build catches up, which tells you the two can drift. If you need a self-contained reference in the repository, you will be following links.
What a different serving stack buys you
The meaningful alternative for most teams is a general-purpose inference server that runs the same model on the same GPUs without a vendor-specific kernel and runtime layer. The difference is not speed on paper; it is what you give up in exchange for portability. A generic server accepts a wider range of model architectures and hardware, and it typically ships as a single artifact you can run anywhere. TensorRT LLM asks you to accept a pinned CUDA and PyTorch combination and an NVIDIA-only target in return for kernels tuned to specific operations and a runtime built for orchestration. If your workload is a well-known dense or mixture-of-experts model on current NVIDIA hardware, and serving cost is the metric you are optimizing, the vendor-specific path is the one with more room to move. If your workload is heterogeneous, or your model list changes weekly, the general-purpose server is the better default and the specialized stack is premature.
Maintenance cost and the licence field that disagrees with itself
Two maintenance facts are visible. First, the project is active: the last push is 2026-11-02 and the releases arrive on a multi-week cadence. Second, the release line is rc, so upgrades are not just version bumps; they are moves along a candidate series where behavior can shift. Budget for reading release notes rather than assuming compatibility. On licensing, the repository metadata reports NOASSERTION, while the README has a licence badge linking to the LICENSE file and setup.py carries an Apache-2.0 SPDX header. Those two signals do not match, and the GitHub licence field is the one automated tooling reads. Before you depend on the project, open the LICENSE file at the path the badge links to and confirm the terms yourself. This is not legal advice; it is a note that the machine-readable and human-readable licence indicators on this repository point in different directions, and only one of them is authoritative.
Editorial conclusion
Adopt it if you are already committed to NVIDIA GPUs and want a Python API over specialized kernels and an efficient runtime, and if you can match the torch>=2.14.0a0,<=2.14.0 pin and cu132 wheel index in requirements.txt. Do not adopt it if you need a multi-vendor serving stack or a stable tagged release today, since the newest tags are release candidates. Before you build anything, read tensorrt_llm/version.py and the LICENSE file, because the GitHub licence field reports NOASSERTION even though setup.py carries an Apache-2.0 SPDX header.
Frequently asked questions
What is TensorRT-LLM?
A toolkit from NVIDIA that optimises inference for large language models and video generation models, providing an easy-to-use Python API to define models plus specialised kernels for common operations, an efficient runtime, and components that create Python and C++ runtimes to orchestrate execution. Its tech blog covers distributed serving work, including disaggregated serving, distributed weight data parallelism and several expert-parallelism scaling techniques.
What is the difference between TensorRT and TensorRT-LLM?
The front page does not draw the comparison. It describes itself as optimising inference for language and video generation models with specialised kernels, an efficient runtime and a framework that lets you customise and extend the system, and it links to architecture, performance, examples and roadmap documentation pages. The relationship to the lower-level toolkit is implied by the name and the kernel-level framing rather than stated.
how to install tensorrt llm
The front page does not give installation commands; it links to a quick-start guide and a documentation site. It does pin the Python versions it links to, at two specific patch releases, and links to the vendor's toolkit downloads and to the framework it builds on. The requirements file at the top of the repository adds an extra index for a hardware-specific wheel channel and constrains several dependencies with comments explaining why.
what does tensorrt llm do
It compiles and runs models for inference on the vendor's hardware using kernels written for the specific operations those models perform. Around that it provides an inference runtime, Python and C++ bindings for orchestrating execution, and a set of serving techniques documented in the front page's engineering posts: disaggregated serving, distributed weight data parallelism, expert parallelism scaling, speculative decoding including an n-gram variant, sparse attention, and a long-context attention technique.
Official sources
Where this project is recommended
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- Jensen is out. CUDA isn't. A Developer's Guide to Everything Nvidia Builtdev.to · Nov 13, 2026 · 7 points · 2 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/nvidia-tensorrt-llm)Star history chart for your README
[](https://hysenlabs.com/projects/nvidia-tensorrt-llm)Was this useful?