nvdiffrec: the news section ends in 2023 and two directories differ by a suffix
Official code for the CVPR 2022 (oral) paper "Extracting Triangular 3D Models, Materials, and Lighting From Images".
At a glance
- What is it?
- NVlabs/nvdiffrec is NVIDIA's research code for jointly recovering geometry, materials and lighting from multi-view images, published with a CVPR 2022 oral. Its installation instructions are from the CUDA 11 era and its metadata does not name the licence its own readme points at.
- Who is it for?
- nvdiffrec is a research codebase rather than a product, and it should be read as one: the four example configs, the two public-domain test models and the two third-party datasets are enough to reproduce the paper's figures on a large GPU, and nothing more is promised. Three things to check before you plan around it.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 94 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
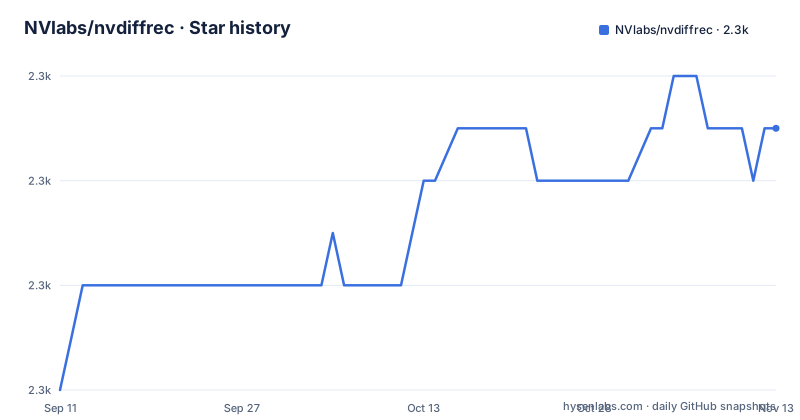
- NVlabs/nvdiffrec2,301 ★ · +5
| Repository | 2026-09-11 | 2026-11-13 |
|---|---|---|
| NVlabs/nvdiffrec | 2.3k | 2.3k |
5 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The licence is named in the readme and absent from the metadata
The licensing section is four lines and none of them is an open-source grant. It carries a copyright notice for 2022 with all rights reserved, states that the work is made available under the NVIDIA Source Code License, points at the licence file at the root of the repository, and then gives a route for business enquiries with a form link. Meanwhile the repository's licence field records nothing. Both statements can be reported and neither settles the other: the file in the repository is named by the document, and the metadata names no licence for that file. For code that is described as official research code and built on another NVIDIA library, a source-available grant with an enquiry path is a normal arrangement. It is also not the same thing as the permissive licences most readers assume when they see a research repository, and anyone planning to reuse it commercially has to go through that enquiry.
The news section stops three years before the last commit
There are two news entries and both are from 2023. The first, in September, added support for a different isosurfacing technique, with a configuration file as the usage example and a link to that technique's own documentation. The second, in October, added a version of the rendering utilities library written against a shading language binding, so that automatic differentiation comes from the language rather than from hand-written forward and backward passes in compiled extensions. The document claims the same runtime performance and puts that version on a separate branch rather than on the main one. The last recorded commit on the main branch is 2026-08-12. So three years of work sit above two news items from 2023, and the most interesting capability the project has, the language-rewritten renderer, is off the default branch.
The toolchain requirements are from the CUDA 11 era
The requirements line asks for Python 3.6 or newer, Visual Studio 2019 or newer, CUDA 11.3 or newer and PyTorch 1.10 or newer, and the next line says it was tested in a conda distribution with Python 3.9 and PyTorch 1.10. Two things stand out. Python 3.6 reached end of life years ago, and a floor that old is a statement about when the project was written rather than a supported range. And the Visual Studio requirement is listed as a general requirement even though the multi-GPU path is Linux-only and the display path is Windows-only, so a Linux user is told to install a Windows compiler. The worked example compounds it: it creates a Python 3.9 environment and installs PyTorch with a conda package named for an old CUDA bundle, which has since been renamed, and it installs one dependency with a pip flag for global options that newer pip versions no longer accept.
Two directories at the root, and the readme uses both paths
The repository root carries a data directory and a dataset directory, and the document refers to both spellings. The automated dataset downloader is run by changing into data and calling the script there. The manual instructions for the second dataset tell you to change into nvdiffrec/data/nerd, which is the same directory written with the repository name in front of it, and the archive for the first dataset is said to be unzipped into a path that again includes the repository name. So one set of instructions assumes you are at the repository root and the other assumes you are somewhere else entirely, and a reader who follows them in order will not find the directory the second block expects. Nothing in the document explains which of the two top-level directories holds the images.
The container commands ship a placeholder directory and a doubled flag
The server section is three steps. Build the image from inside the docker directory with a shell script and a tag you choose. Then start it interactively, or start it detached with a GPU device index, a volume mapping and a training command. The detached form is the one to read twice:
docker run --gpus device=1 -d -v /raid:/raid -w=[path to the code] nvdiffrec:v1 python train.py --config configs/bob.jsonThe working-directory flag is a literal placeholder with square brackets in it, and the volume maps a host path rather than the source tree, so the container starts in its own directory with no code in it. The configuration path in the same command is relative, so it will not resolve until you fix both. The interactive form has the same missing working directory and the same unmapped source, and it passes the interactive flag twice. All three are typos rather than design, but they are the commands a reader copies first.
Multi-GPU is experimental and the display path is Windows-only
The examples section opens with the constraint that decides whether any of this is worth trying: the approach is designed for high-end GPUs with a lot of memory, and to run on mid-range cards you reduce the batch size in the configuration files. Then the three commands. A plain training run. A second run with a display interval that the document marks as supported on Windows only. And a distributed run under a launcher, marked Linux only and marked experimental in the same parenthetical, with the reason given: every result in the paper was produced on a single GPU. So the multi-GPU path is the least proven part of the code, the only visualisation path is Windows-only, and the two documented platforms do not overlap. Results are written to an output folder, which is the one piece of state the document commits to.
Four configs, two public-domain models, two borrowed datasets
The four included examples differ by assumption rather than by size. One reconstructs a teapot-shaped model recovering geometry, materials and lighting together. One is the same but takes the environment lighting as known, which removes one unknown from the problem. One adds high-frequency environment lighting to demonstrate a particular approximation. One is a simple closed-surface model. The two test models were created and released into the public domain by their author, which removes any question about the inputs. The datasets do not: the document is explicit that individual licences apply to each third-party dataset, and it leans on their authors for both. One is the synthetic set from the original radiance-field paper, required for the first family of configs, and one is a photogrammetry set with hand-annotated segmentation masks that the document itself calls inaccurate, required for the second family.
Editorial conclusion
nvdiffrec is a research codebase rather than a product, and it should be read as one: the four example configs, the two public-domain test models and the two third-party datasets are enough to reproduce the paper's figures on a large GPU, and nothing more is promised. Three things to check before you plan around it. The licence is NVIDIA's own source-available licence with an all-rights-reserved notice and a route for commercial enquiries, and the repository's licence field names nothing at all, so read the file. The install steps assume a 2019-era toolchain, including a conda package name that has since been renamed and a pip flag that has since been removed. And the display path is Windows-only while the multi-GPU path is Linux-only, so pick your platform before you start.
Frequently asked questions
What license is NVIDIA nvdiffrec under?
The NVIDIA Source Code License, with a copyright notice for 2022 and all rights reserved, and a link to a business enquiries form for commercial use. The repository's own licence field names nothing, so the file the document points at is the authoritative statement.
What does nvdiffrec need to run?
The document asks for Python 3.6 or newer, Visual Studio 2019 or newer, CUDA 11.3 or newer and PyTorch 1.10 or newer, and says it was tested with Python 3.9 and PyTorch 1.10 in a conda environment. The worked example also installs two dependencies from git and one console script for downloading an image library.
Can nvdiffrec train on more than one GPU?
There is a distributed example under a process launcher, documented as Linux only and as experimental, with the note that every result in the paper was generated on a single GPU. The document also warns that the approach targets high-end GPUs with large memory and that mid-range cards need a smaller batch size in the configuration files.
Which datasets does nvdiffrec need?
Two families of configurations, one requiring a synthetic radiance-field dataset from the original paper and the other a photogrammetry set with hand-annotated segmentation masks. Both come from third-party authors under their own licences, an automated download and preprocessing script is provided, and manual instructions are given as a fallback.
Is the Slang version of nvdiffrec on the main branch?
No. The news section says the rendering utilities rewritten against a shading language binding are available in a separately named branch, with the same runtime performance as the compiled-extension version. That entry is from October 2023, while the last recorded commit on the main branch is 2026-08-12.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/nvlabs-nvdiffrec)Star history chart for your README
[](https://hysenlabs.com/projects/nvlabs-nvdiffrec)Was this useful?