VLM-R1: GRPO training for referring expressions, and the pixel config that broke the SFT comparison
Solve Visual Understanding with Reinforced VLMs
At a glance
- What is it?
- VLM-R1 applies R1 style reinforcement learning to vision language models, training Qwen2.5-VL and InternVL with GRPO for referring expression comprehension and open vocabulary detection. Its most useful contribution is negative: earlier SFT comparisons were re-run after the project found the pixel configuration did not match.
- Who is it for?
- VLM-R1 is worth reading if you are about to apply GRPO to a vision language model and want a script per training mode, a documented way to freeze the vision tower, and an example of a baseline that had to be re-measured. It is not a drop in library: the training entry points are shell scripts over a vendored open-r1-multimodal tree, and the container is pinned to one CUDA 12.4 image with a Python 3.11 flash-attention wheel.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 132 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
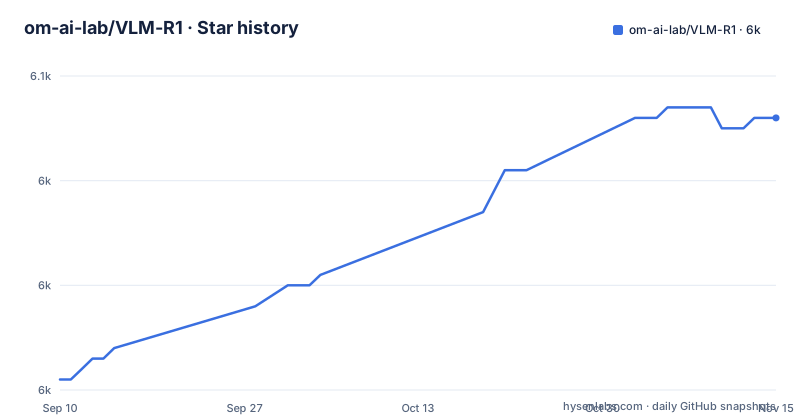
- om-ai-lab/VLM-R16,046 ★ · +25
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| om-ai-lab/VLM-R1 | 6k | 6k |
25 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The earlier SFT comparison was re-run after a pixel config mismatch
The project's most instructive finding is a correction rather than a result. A note attached to the referring expression comprehension experiments states that previous SFT experiments used a mismatch pixel configuration, and that the study was therefore re-run with the correct configuration on more complex out-of-domain data, with the details written up separately on the project's blog.
That single sentence changes how the rest of the claims should be read. When a baseline is trained with one image geometry and evaluated with another, the comparison is measuring preprocessing rather than method. Re-running with matched settings is what makes the in-domain and out-of-domain comparison meaningful at all.
For anyone reproducing this, the implication is concrete: the preprocessing configuration is part of the experiment, not a detail of the harness. A GRPO run and its SFT baseline have to share it, or the learning curve will be an artifact.
In-domain flat, out-of-domain diverging as steps increase
The REC experiments train Qwen2.5-VL twice, once with the R1 approach and once with supervised fine tuning, and the two curves separate in a specific pattern. On in-domain test data, with a relatively small number of training steps, described as 100 to 600, the SFT model changes little compared with the R1 base model, while the R1 model improves steadily.
Out of domain the ordering reverses in effect. The SFT model's performance deteriorates slightly as the number of steps increases, whereas the RL model is reported to generalize its reasoning ability to the out-of-domain data.
So the case for reinforcement learning here rests on two things rather than one. In-domain, it simply keeps learning where SFT has flattened out. Out of domain, supervised fine tuning actively degrades with more steps while the RL run holds up. A team choosing between the two methods should read the second curve, because the first can be produced by almost any method that trains long enough.
One shell script per training mode, and a flag to stop touching vision
The repository exposes training configurations as scripts under run_scripts/ rather than as a config file with switches, which makes the supported matrix readable from the file names. Full fine-tuning with GRPO for REC is run_grpo_rec.sh, LoRA fine-tuning with GRPO is run_grpo_rec_lora.sh, multi-node training is multinode_training_demo.sh, and multi-image input training is run_grpo_gui.sh.
Vision tower freezing is a single variable rather than a separate script: setting freeze_vision_modules to true in the script keeps the vision modules fixed. That is the option that decides how much of the model the policy can move.
InternVL is supported for GRPO through run_grpo_rec_internvl.sh, added on 2025-03-13, so the REC recipe is not bound to the Qwen family. Own data is documented in the README itself rather than in a separate guide, including the expected format for multi-image input, which is what run_grpo_gui.sh consumes.
Adding a model means a module, because rewards live inside it
The extension point is a module, and the instruction is assets/add_new_model.md. Currently the supported families are QwenVL and InternVL. That is a heavier extension than a config entry, and the 2025-04-16 refactor makes the reason clear: a parameter named is_reward_customized_from_vlm_module was introduced so that custom reward functions defined inside the vision language module can be used. When it is set to true, the reward logic is handled in either QwenVL2Module or InternVLModule, depending on which model is selected.
The same refactor consolidated tasks. The REC process was integrated into grpo_jsonl.py for consistency across tasks, meaning the referring expression pipeline and the detection pipeline now share one driver instead of running as separate implementations. The training log was also expanded for monitoring and debugging.
The practical read: porting VLM-R1 to a new vision language model means writing a module that owns its reward functions and registering it, not passing a class name on the command line. Budget review time accordingly.
Bounding boxes get a post-resize step in training and in evaluation
On 2025-06-26 the project added a post-resize operation for the bounding box in QwenVL, applied in both places where a box is produced. Training touches it in the Qwen module, and evaluation touches it in the REC evaluation script, src/eval/test_rec_r1.py. The stated result is that the results improve slightly.
A change applied twice, on both sides of the pipeline, is worth pausing on. If the resize lived only in evaluation, the numbers would move for reasons that have nothing to do with the policy, which is the same class of problem as the earlier pixel configuration mismatch. Putting it in training and evaluation together keeps the coordinates the model learns and the coordinates the evaluator scores in the same space.
That is also the practical takeaway for anyone extending this code: the two file locations are a pair, and a change to one without the other will look like a free improvement.
The container pins CUDA 12.4 and a Python 3.11 flash-attention wheel
The Dockerfile builds on pytorch/pytorch:2.5.1-cuda12.4-cudnn9-devel, installs git and wget, and then handles flash-attention in two steps. It first tries a pre-built wheel by URL, and falls back to a source install with build isolation disabled if that fails:
FROM pytorch/pytorch:2.5.1-cuda12.4-cudnn9-devel
RUN pip install --no-cache-dir \
    "https://github.com/Dao-AILab/flash-attention/releases/download/v2.7.4.post1/flash_attn-2.7.4.post1+cu12torch2.5cxx11abiFALSE-cp311-cp311-linux_x86_64.whl" || \
    pip install flash-attn --no-build-isolation
RUN pip install vllm==0.7.2
The wheel filename is the constraint list. It encodes CUDA 12, torch 2.5, an ABI setting of cxx11abiFALSE, CPython 3.11 and linux_x86_64, so the fast path only applies to that combination and anything else compiles from source.
Two more choices in the same file matter for reproducibility. Transformers is installed from the GitHub repository rather than from a pinned release, so the version inside the image moves with upstream. The image ends with CMD ["/bin/bash"], which means it is a workbench image, not a training entry point, and the training commands still have to come from run_scripts/.
Ascend deployment lives in its own tree with its own numbers
Hardware coverage beyond NVIDIA is handled in a separate top-level directory, ascend_inference/, with three documented paths: 910B/xllm, 910B/vllm_ascend and 300IDuo. On 2025-08-22 the model series was adapted to Huawei Ascend Atlas 800T A2 and Atlas 300I Duo hardware using the vllm-ascend framework.
A week later, on 2025-08-29, came the performance entry. The models were further optimized on the back of JD's open source xllm inference framework, and the reported changes are specific: time to first token reduced by 50 percent compared with vllm-ascend, and overall throughput increased by 127 percent compared with vllm-ascend. Both comparisons are against vllm-ascend, which is the baseline that shipped a week earlier, so the two entries are a sequence rather than two independent results.
The structure says something about the project's shape. Training lives under src/ with run_scripts/ as its interface, while inference hardware support is per-vendor documentation and configuration, which is what lets one set of weights target both an NVIDIA GPU stack and an Ascend stack without a shared serving layer.
Model artifacts sit on two hubs while tags stopped at v0.2.1
The distribution story is a set of hosted artifacts rather than packages: a REC demo space and an OVD demo space, the REC dataset, a checkpoints collection, and a parallel set of checkpoints on ModelScope. The technical report is on arXiv at 2504.07615, and the project's blog carries the dated write-ups behind the reward design and the pixel configuration findings.
What the repository does not have is a matching release cadence. The newest tag is v0.2.1, published on 2025-04-15, after v0.2.0 on 2025-03-24 and v0.1.0 on 2025-03-17. The repository is not archived and its last commit was on 2026-07-07, so work continued well after the last tag, and the update log's own newest entry is 2025-08-29. Any later work is therefore visible in commits rather than in releases.
For an evaluator, that split decides where to look. Version numbers describe a March and April 2025 state of the code, while the deployment and bounding box work is documented only in dated log entries, and the results to trust are the leaderboard claims attached to them: the Math model at the top of the Open-Compass Math leaderboard under 4B parameters, and the OVD model reported as state of the art on OVDEval, which the project says beat SFT baselines and specialized object detection models.
Editorial conclusion
VLM-R1 is worth reading if you are about to apply GRPO to a vision language model and want a script per training mode, a documented way to freeze the vision tower, and an example of a baseline that had to be re-measured. It is not a drop in library: the training entry points are shell scripts over a vendored open-r1-multimodal tree, and the container is pinned to one CUDA 12.4 image with a Python 3.11 flash-attention wheel. Before committing, check the last commit date against the v0.2.1 release, and confirm the pixel configuration your evaluation uses matches your training one, since that mismatch is what invalidated the earlier SFT comparison.
Frequently asked questions
Which vision language models does VLM-R1 support for GRPO training?
QwenVL and InternVL are the supported families, with Qwen2.5-VL used for the referring expression and open vocabulary detection work. Adding another model means following the add-new-model guide and providing a module that owns its reward functions.
How do I freeze the vision modules during VLM-R1 training?
Set freeze_vision_modules to true in the training script. Full fine-tuning, LoRA fine-tuning, multi-node and multi-image training are separate scripts under run_scripts/, and InternVL has its own script for GRPO.
Does VLM-R1 outperform supervised fine tuning on out-of-domain data?
The project reports that the SFT model's performance deteriorates slightly as training steps increase on out-of-domain data, while the RL model generalizes its reasoning ability to it. On in-domain data over roughly 100 to 600 steps, SFT changes little against the base model while the R1 model improves steadily.
What is the fastest way to try VLM-R1 without training?
Hosted demos and weights exist rather than a pip package: a referring expression comprehension demo space, an open vocabulary detection demo space, a dataset, and checkpoint collections on both the Hugging Face hub and ModelScope. The container image is a workbench with a shell as its default command, so training still comes from the shell scripts.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/om-ai-lab-vlm-r1)Star history chart for your README
[](https://hysenlabs.com/projects/om-ai-lab-vlm-r1)Was this useful?