PDF Craft reads scanned books, not born-digital PDFs
PDF craft can convert PDF files into various other formats. This project will focus on processing PDF files of scanned books.
At a glance
- What is it?
- A Python library that turns image based scans into Markdown and EPUB, optionally translated, with a separate OCR path and a separate translation path. Useful when the source is a camera scan of a book and nobody wants to retype it.
- Who is it for?
- PDF Craft fits a pipeline where the inputs are known scanned volumes and somebody on the team can own Poppler plus an OCR endpoint. Run one representative book through your own model before committing a batch, because the project states plainly that output depends on scan quality, page layout, and the OCR model.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
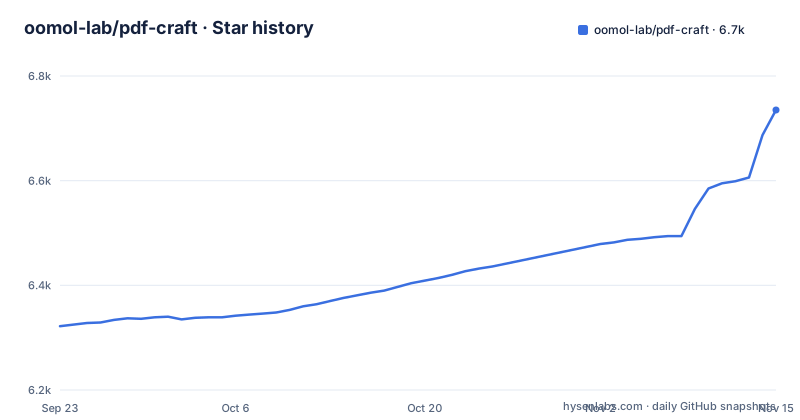
- oomol-lab/pdf-craft6,735 ★ · +413
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| oomol-lab/pdf-craft | 6.3k | 6.7k |
413 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Remote OCR is the default path, local OCR is an extra
The project offers exactly three ways in, and each one hands your pages to a different place. The hosted app at pdfcraft.ai needs only a browser, and the README calls it the official online service for this open-source project. Python plus remote OCR needs Python, Poppler, a compatible OCR service URL and credentials. Python plus local OCR needs Python, Poppler, CUDA, enough VRAM, and model files on disk. The pyproject.toml declares optional dependencies for the local runtime.
Remote OCR sends pages to the configured service and does not need local CUDA. Local OCR runs on your own machine. What neither mode gives you is a fully closed loop: even on the local path, pointing translation or table of contents analysis at a remote LLM still sends that content to the service. Pages that never touch an OCR endpoint can still leave the building once a remote text model is in the pipeline.
OCR and translation carry separate configurations
Conversion and translation are two different calls to two different models, and the library keeps them apart. You can translate during conversion or translate an existing EPUB, with translation-only and bilingual output modes.
The quick start asks for a working DeepSeek OCR compatible service configuration, and the sample endpoint it shows is a placeholder:
from pdf_craft import DeepSeekOCRVendorConfig, PDFCraft, PDFOptions

craft = PDFCraft(
    pdf=PDFOptions(
        ocr=DeepSeekOCRVendorConfig(
            base_url="https://example.com/v1",
            api_key="your-api-key",
            model="deepseek-ocr",
        ),
    ),
)

craft.convert_pdf_to_markdown("input.pdf", "output.md")
That address is not a working endpoint, so the snippet fails until you replace URL, key, and model.
The .pcex file is the only artifact built for another machine
Scanning a book is the slow half of the job, so the extraction step can be saved and reused. The README lists reusable extraction files for later rendering or translation.
There is a catch in what travels with the output: a document containing images also produces asset files, and those files have to be kept next to the Markdown whenever you move or share the result. A Markdown file with missing assets is a broken book, so any archiving plan has to track the pair, not the single file.
EPUB metadata lands only when OCR evidence backs it
EPUB output is aimed at an ebook reader, which means a table of contents and bibliographic fields. Rich metadata is opt in: you enable front page OCR metadata extraction and hand the job to a separate metadata LLM. The verification rule is strict. Every accepted value is checked against OCR evidence, and PDF file properties are used only to fill missing fields, never to override printed book information. In other words the scanned cover page wins over whatever the file claims about itself.
Producing the file itself takes one call on the same configured instance:
craft.convert_pdf_to_epub("input.pdf", "output.epub")Title, author, and rendering options live in `docs/en/PDF_TRANSLATION.md`. What this design gives up is convenience at the front door: rich metadata needs a separate metadata LLM, and turning it on adds another model call per book. It also cannot repair a cover page that printed the wrong year. The model is told to trust the page, and a wrong page produces a confidently wrong record.
The synchronous facade breaks inside a running event loop
There are two classes, and mixing them is the documented mistake. Async applications use the same options object through `AsyncPDFCraft`, callbacks may be written as `async def` functions, and they run on the caller's event loop. Calling the synchronous `PDFCraft` facade from a running event loop is explicitly disallowed; the instruction is to use `AsyncPDFCraft` and await the corresponding method.
import asyncio
from pdf_craft import AsyncPDFCraft, DeepSeekOCRVendorConfig, PDFOptions

async def main():
    craft = AsyncPDFCraft(pdf=PDFOptions(ocr=DeepSeekOCRVendorConfig(
        base_url="https://example.com/v1",
        api_key="your-api-key",
        model="deepseek-ocr",
    )))
    await craft.convert_pdf_to_markdown("input.pdf", "output.md")

asyncio.run(main())
The option shape is identical between the two, which is the convenient half. Both classes emit asset files alongside Markdown, which means the download or response you build has to carry those files too.
The translated PDF is the only route that needs Ghostscript
Writing a PDF back out is a separate workflow with its own system requirements. The steps are: extract the content, translate it, and write the translation back onto the original pages. The translation lands on the book's own pages, so the page geometry belongs to the scan rather than to you, and text is placed into boxes whose size was never chosen with another language in mind.
Python 3.13 is the ceiling and almost every dependency is pinned
The packaging leaves little room. `requires-python` is `>=3.11,<3.14`, and the classifiers stop at 3.13, so a 3.14 interpreter or a 3.10 environment will not install cleanly. The distribution is version 2.6.7, carries the Development Status 4 Beta classifier, names Tao Zeyu as both author and maintainer, and builds through poetry-core. The lock file is committed, so the exact tree is reproducible.
The runtime list is long and each entry is boxed in tightly: pypdf at >=6.21.4,<7.0.0, tiktoken at >=0.12.0,<1.0.0, openai at >=2.14.0,<3.0.0, pydantic at >=2.12.5,<3.0.0, typesafe-sdk at >=0.7.1,<0.8.0, httpx2 at >=2.0.0,<3.0.0, doc-page-extractor at >=1.2.2,<2.0.0, markdownify at >=1.2.2,<2.0.0, reportlab at >=4.4.0,<5.0.0, jinja2 at >=3.1.6,<4.0.0, pylatexenc at >=2.10,<3.0.0, pyahocorasick at >=2.2.0,<3.0.0, resource-segmentation at >=0.0.7,<0.1.0, and mathml2latex at >=0.2.12,<0.3.0. Two entries are exact pins, epub-generator==0.1.7 and pdfminer.six==20260107, which means no patch bump to either reaches you without a release of pdf-craft itself. pyside6 at >=6.8.0,<7.0.0 also lands in the base install, so a headless server gets Qt pulled in even if you never open the tool package.
Failures get routed to a troubleshooting page and stop there
Setup problems have a named destination: Poppler setup goes to `docs/en/INSTALLATION.md`, and installation or runtime trouble goes to `docs/en/TROUBLESHOOTING.md`. Engine choice lives in `docs/en/OCR_BACKENDS.md`. The top level of the repository matches that layout with `docs/`, `pdf_craft/` for the library, `pdf_craft_tool/`, `references/`, `scripts/`, `tests/` plus `test.py`, `format.template.json`, `.env.template`, and a `poetry.lock`. Nine translated readmes sit under `docs/readmes/`, covering Simplified and Traditional Chinese, Japanese, Korean, Russian, French, Spanish, German, and Italian.
The recent releases are close together: v2.6.5 on 2026-10-26, v2.6.6 on 2026-10-28, and v2.6.7 on 2026-10-28, with the last push on 2026-11-02. Three releases inside three days means you should pin the version you validated rather than float on the newest one.
Editorial conclusion
PDF Craft fits a pipeline where the inputs are known scanned volumes and somebody on the team can own Poppler plus an OCR endpoint. Run one representative book through your own model before committing a batch, because the project states plainly that output depends on scan quality, page layout, and the OCR model. If you need authored PDFs, a page editor, or guaranteed layout on translated output, this library does not promise those things and its own pages do not.
Frequently asked questions
What is the best program to create PDFs?
PDF Craft runs the other direction. It takes scanned PDFs and produces Markdown, EPUB, or a translated PDF. The only PDF it writes is the translation path, where translated text is written back onto the original source pages.
What does PDF stand for in the files PDF Craft accepts?
What the project fixes is the shape of the input: scanned books, research papers, and technical documents whose page content is extracted into body text, chapters, a table of contents, footnotes, tables, formulas, and images, which is why an OCR engine is mandatory rather than optional.
Is PDF Craft online free?
The library is MIT licensed and installs from PyPI, so the code carries no license fee. The hosted converter linked from the project sits at pdfcraft.ai, which the README describes as the project's official online service: upload a PDF in a browser and download the result, with no Python, CUDA, OCR provider or API key to set up.
How can I make my own PDF with PDF Craft?
It does not author new PDFs from a blank page. Its one PDF output is the translated workflow: extract the content, translate it, write the translation back onto the source pages.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/oomol-lab-pdf-craft)Star history chart for your README
[](https://hysenlabs.com/projects/oomol-lab-pdf-craft)Was this useful?