VLMEvalKit scores vision-language models, not chatbots, and the config file is the whole interface
Open-source evaluation toolkit of large multi-modality models (LMMs), support 220+ LMMs, 80+ benchmarks
At a glance
- What is it?
- VLMEvalKit evaluates 220+ large multimodal models across 80+ benchmarks by forcing every model through the same generation-then-extract path. The design is deliberate and the cost is that accuracy quietly depends on two environment variables you have to know about.
- Who is it for?
- Adopt VLMEvalKit if you are comparing several multimodal checkpoints on shared benchmarks and want the OpenVLM leaderboard numbers to be comparable with your own. Skip it if you need a single model scored on one private dataset, or if you need distributed inference for a model outside the InternVL, QwenVL and LLaMA4 series the distributed path covers.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
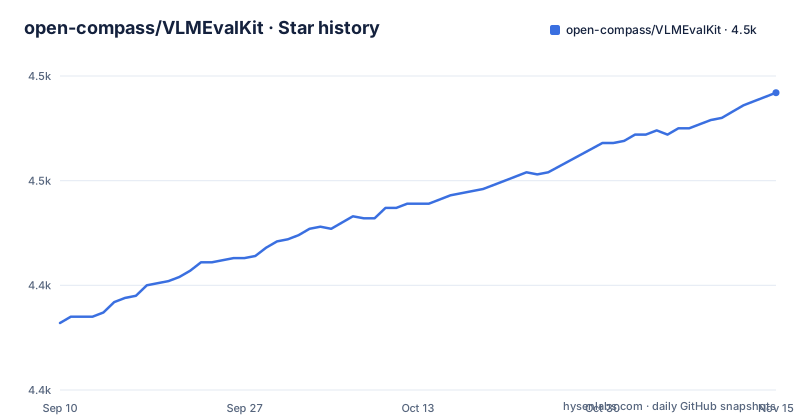
Star history
- open-compass/VLMEvalKit4,492 ★ · +110
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| open-compass/VLMEvalKit | 4.4k | 4.5k |
110 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Why VLMEvalKit exists: data preparation scattered across benchmark repos
The problem VLMEvalKit names is concrete: every benchmark repository wants its own copy of the test data, its own prompt template and its own answer-checking code, so a researcher comparing models ends up maintaining the plumbing instead of the comparison. The project pushes all of that into one place and calls the result one-command evaluation, claiming coverage of 220+ large multimodal models on 80+ benchmarks.
The audience is narrow and well served. If you are picking between InternVL3, Qwen2.5-VL and Gemini-2.5-Pro on MMMU-Pro, you want identical prompts and identical scoring across all three, and you want to compare your numbers against the OpenVLM leaderboard rather than against your own last week. If you are scoring one model on one dataset you wrote yourself, this harness is a poor fit and the dependency list will tell you why.
That dependency list is the first honest signal about the cost. `requirements.txt` pins things like `antlr4-python3-runtime==4.11.1` and `pylatexenc==2.10`, pulls in `rdkit`, `lpips`, `cd-fvd` and `latex2sympy2-extended`, and caps `litellm` at `>=1.55,<1.85`. One install of a vision-language evaluator drags in chemistry, video and TeX tooling because the benchmark set spans all three.
Generation-based evaluation forces every model through one answer path
VLMEvalKit adopts generation-based evaluation for all supported models. Instead of comparing log-likelihoods or logits, it asks the model to generate a full response and then scores the text. That single choice is what lets a 7B open-weight model and a hosted API model be measured on the same multiple-choice benchmark, and it is the mechanism behind the one-command claim.
Scoring runs two ways: exact matching, and LLM-based answer extraction. The second exists because a reasoning model rarely emits a bare option letter. Answer extraction hands the verbose response to a judge model, which is where comparability quietly depends on your setup rather than the model's.
A later change pushed this further. In PR 1175 the maintainers refined `can_infer_option` and `can_infer_text` so that evaluation routes increasingly to the LLM choice extractors, which they report leads to slight performance improvement on multiple-choice benchmarks. That is a small win on paper and a real one in practice, because the routing rules decide which extractor touches a given answer.
The surface you touch is run.py plus one config file
Most of the complexity sits below a thin entry point. The repository root holds `run.py`, `setup.py`, `requirements.txt`, `scripts/`, `tests/` and the `vlmeval/` package, and model backends are declared as Python objects inside `vlmeval/config.py` rather than in a separate config format.
Two integration points deserve your attention because they are flags on that same config object. For large-scale or thinking models, distributed inference runs through LMDeploy (InternVL, QwenVL and LLaMA4 series) or through VLLM (QwenVL and LLaMA4 series), and you opt in by adding a `use_lmdeploy` or `use_vllm` flag to your custom model configuration in `vlmeval/config.py`.
The coverage is not open-ended: LMDeploy reaches three model families and VLLM reaches two. A checkpoint outside those series does not get the distributed path.
A second switch governs where benchmark assets come from. Setting the `VLMEVALKIT_USE_MODELSCOPE` environment variable routes video benchmark downloads through modelscope instead of the default path, which matters for networks where the primary host is slow.
Getting vlmeval installed and running your first benchmark
The README's QuickStart section carries no install command. It points to `docs/en/Quickstart.md` in the repository for the quick start guide, so that file and not the README is where you read the install steps. One name matters before you start: the Python package is `vlmeval`, not `vlmevalkit`.
Before your first run, decide two environment variables. Neither is on by default, and both change your scores.
SPLIT_THINK=True
PRED_FORMAT=tsv
`SPLIT_THINK=True` enables support for models with thinking mode. By default the parser reads content inside `<think>...</think>` tags and stores it in the `thinking` key of the output, leaving the answer field clean. The README is explicit that this is recommended for thinking-mode models to keep evaluation accurate, and you can go further by defining your own `split_think` function for a model, following the InternVL implementation as the example.
`PRED_FORMAT=tsv` switches prediction files from xlsx to TSV. Individual cells in an `.xlsx` file are limited to 32,767 characters, so a model producing responses longer than 16k or 32k tokens gets its predictions truncated at the cell boundary unless you set this.
The xlsx cell ceiling and the silent thinking tag are the two failure modes
The first failure mode is data loss with no error message. Run a model with very long responses on xlsx output and the predictions can be truncated at 32,767 characters per cell; if the answer sat in the tail, the score drops. The README treats this as important enough to lead with the spreadsheet limit, and the fix is the one environment variable above.
The second failure mode is quieter still. Leave `SPLIT_THINK` unset with a thinking-mode model and the reasoning text is scored as part of the answer. Exact matching then fails on a response the model actually got right, and because the two scoring paths are both available, the failure looks like a model regression rather than a parsing configuration error.
The third is throughput. Distributed inference exists because single-node evaluation of large or thinking models is slow, but the two engines the README lists cover a limited set of series. Below that line, a sweep over 80+ benchmarks is not a laptop job.
Where VLMEvalKit differs from an independently maintained harness
The comparison worth making is architectural. VLMEvalKit couples evaluation to publishing: the repository ships prediction records on Hugging Face, a video leaderboard Space, and an OpenVLM Leaderboard Space that publishes downloadable detailed results. Its score is not only the number on your machine; it can be compared against a published record set.
VLMEvalKit's model configuration in `vlmeval/config.py`, its LLM answer extractors and its leaderboard pipeline are moving parts you inherit. Choose it if your comparison has to be defensible against published numbers.
One pull request number is cited twice and links somewhere else
Pinning a version for a paper or a CI gate means reading the source rather than trusting the tag list. The project sits under Apache-2.0, which lets you modify and ship it commercially without a copyleft obligation on your own code. The README's codebase changelog carries two entries both dated 2025-09-12, for improved thinking-mode handling and for long response output, and both cite the same pull request number, PR 1229. Both entries link to a different address, the `pull/1175` path, which is the same pull request cited by the earlier 2025-08-04 entry about `can_infer_option`.
So the two most consequential changes for score integrity are filed under one number and attributed to two, and a skim reader would never notice, since the numbers sit in the prose rather than the heading of either entry. Find the commit that actually carries the `SPLIT_THINK` and `PRED_FORMAT` handling before you record a score anywhere outside your own notes.
Editorial conclusion
Adopt VLMEvalKit if you are comparing several multimodal checkpoints on shared benchmarks and want the OpenVLM leaderboard numbers to be comparable with your own. Skip it if you need a single model scored on one private dataset, or if you need distributed inference for a model outside the InternVL, QwenVL and LLaMA4 series the distributed path covers. Verify first that the model answers are parsed as you expect: set SPLIT_THINK=True for thinking-mode models and PRED_FORMAT=tsv before running anything longer than 16k tokens, then diff one benchmark against the published leaderboard rows.
Frequently asked questions
What is the Python package name for VLMEvalKit and how do I install it?
The Python package name is `vlmeval`, not `vlmevalkit`. The README's QuickStart section carries no install command and instead points to `docs/en/Quickstart.md` in the repository for the quick start guide.
Why should I set SPLIT_THINK when evaluating a thinking-mode model?
With `SPLIT_THINK` set, the parser reads content inside `<think>...</think>` tags and stores it in the `thinking` key of the output, keeping the scored answer field clean. The README recommends this for models with thinking mode to keep evaluation accurate, and you can define your own `split_think` function for a model, using the InternVL implementation as the example.
How does VLMEvalKit avoid truncating predictions from models with very long responses?
Individual cells in an `.xlsx` file are limited to 32,767 characters, so predictions from models exceeding 16k or 32k tokens can be cut off. Setting `PRED_FORMAT=tsv` makes the toolkit save prediction files in TSV format instead, which the README recommends for long responses.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/open-compass-vlmevalkit)Star history chart for your README
[](https://hysenlabs.com/projects/open-compass-vlmevalkit)Was this useful?