Open-LLM-VTuber: v1 is feature frozen, and the tagged release is nine months behind main
Talk to any LLM with hands-free voice interaction, voice interruption, and Live2D taking face running locally across platforms
At a glance
- What is it?
- Open-LLM-VTuber is a Python voice and Live2D companion that runs against local or cloud models. Its own banner says the project has moved to planning a v2.0 rewrite and asks for no new v1 features, while the newest tag is v1.2.1 from August 2025 and main kept moving until May 2026.
- Who is it for?
- Open-LLM-VTuber suits someone who wants a voice companion with a Live2D face running against models they control, and who is willing to configure TLS and a reverse proxy before pointing a phone at it. It suits badly anyone planning a long feature-driven contribution, since the project asks that v1 feature requests be withheld while a rewrite is discussed, or anyone assuming a recent commit is in the released package.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Activity is slowing. The repository last received commits 6 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
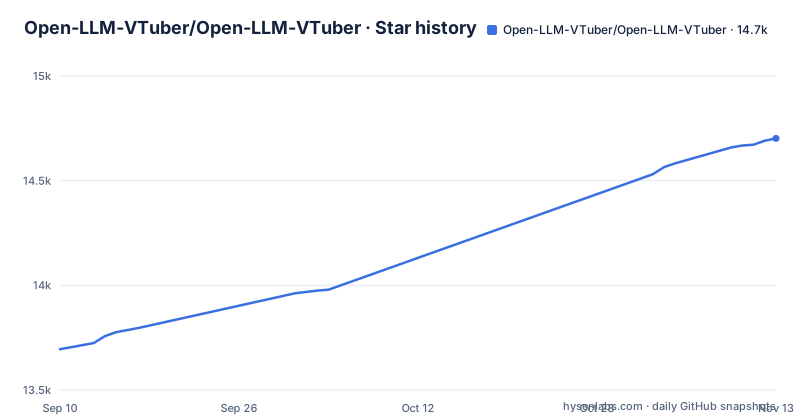
- Open-LLM-VTuber/Open-LLM-VTuber14,702 ★ · +1,007
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| Open-LLM-VTuber/Open-LLM-VTuber | 13.7k | 14.7k |
1,007 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The banner asks you to stop filing v1 features while the rewrite is still in planning
The first thing the README does is redirect contributors. It says the project is focusing on v2.0, a complete rewrite of the codebase, that v2.0 is in its early discussion and planning phase, and that v1 feature requests should not be filed as issues or pull requests. Participation in the v2 discussion happens on Zulip with weekly meeting schedules announced there, and the stated commitment for v1 is limited to fixing bugs and working through existing pull requests. That is a narrower promise than the feature list further down the page, which reads like an active roadmap. The announcement limits the project's stated commitment for v1 to bug fixes and existing pull requests. It does not promise a backport for features discussed for v2. It also means the repository you are reading is a maintenance branch, so an issue you file asking for a capability may simply be closed with a pointer to a rewrite that has no date. The banner governs what is still open; the feature list below it only describes what the code can do today.
main moved until May 2026 while the newest tag is v1.2.1 from August 2025
The tags and the branch have drifted apart. The newest release is v1.2.1, published 2025-08-26, preceded by 1.2.0 on 2025-08-03 and 1.1.0 on 2025-02-19. The last push to the default main branch is dated 2026-05-15, and pyproject.toml still declares version 1.2.1. So there is roughly nine months of commits on main that sit under a version string identical to the last tag, with no 1.2.2 to mark them. This changes what a version number means to you. Install from the tag and you get the August 2025 state. Clone the branch and you get nine months of later work that no release artifact names. Name the line you cloned when you report a defect, because the same symptom can exist in the tagged state and already be fixed on main, and a report carrying nothing but a version number cannot be acted on until someone asks which one you mean.
Python 3.12 is the ceiling, and an Intel Mac is pinned to a torch three versions back
pyproject.toml sets requires-python to >=3.10,<3.13, so 3.13 and anything newer are outside the declared range while 3.10 and 3.11 are inside it. The torch dependency is the more interesting part because it is split three ways by platform rather than given one floor. On Darwin with an x86_64 machine the pin is an exact `torch==2.2.2`. On Darwin with arm64 the floor is `torch>=2.6.0`. On every other system the floor is also `torch>=2.6.0`. An Intel Mac therefore gets one exact old build while Apple silicon and Linux and Windows users get anything from 2.6.0 upward, a gap of four minor releases on the oldest supported platform. Python 3.13 is outside the range outright and has to be waited for or overridden. The Intel Mac user is running an older torch than every other platform. Two people comparing experiences on this project may be comparing different numerical stacks, which is worth establishing before either of you concludes the other is wrong.
The pixi environment targets win-64 and linux-64 only, and caps CUDA below 12
Two dependency managers are configured in the same file, and they do not describe the same world. The uv side exports requirements.txt, a file whose own header says it was autogenerated by uv through `uv export --no-hashes --frozen`, and that export resolves CUDA 12 packages: cuda-bindings 12.9.4 and cuda-pathfinder 1.3.3, both marked as coming from torch on linux with an x86_64 machine. The pixi side declares channels of conda-forge, platforms of `win-64` and `linux-64`, and dependencies of cudnn >=8.0,<9 with cudatoolkit >=11.0,<12. macOS is absent from the pixi platform list, so the conda route has no macOS target even though the README claims macOS support, which leaves uv as the workable path there. The two declarations also disagree about the CUDA generation on linux: the conda pin refuses anything at or above 12 while the uv export resolves 12.x bindings. A pixi environment built on linux-64 may end up holding both. Find out which manager produced the artifacts in your environment before concluding that GPU support is broken.
Two lockfiles and development tools in runtime dependencies
The repository carries two lockfiles, uv.lock and pixi.lock, along with .pre-commit-config.yaml, and pyproject.toml adds ruff>=0.8.6 and pre-commit>=4.1.0 to the main dependency list rather than to an optional or development group. So a plain install of the project pulls in a linter and formatter and a commit hook runner along with the application. The ruff configuration sets target-version to py310 and carries a per-file ignore for the E402 rule scoped to run_bilibili_live.py, the one script whose imports are allowed to sit below code. That py310 lint target matters for contributors: rules and syntax newer than it are not what the project checks against, even on an interpreter far ahead of it. A .python-version file sits at the top level, and the declared range allows two minor versions below the ceiling, so a contributor and a user can legitimately sit on different interpreters while both satisfy the project. Mixing the conda and uv pins inside one environment is the mistake worth avoiding here.
The microphone only starts in a secure context, so remote access needs your own proxy
The README warns about a browser rule that shapes the whole remote-use story. It says that if you run the server remotely and access it on a different machine, for example serving from your computer and opening it on your phone, you need to configure https, because the microphone on the front end only launches in a secure context, meaning https or localhost. The suggested remedy is to configure https with a reverse proxy. So the web client does not terminate TLS and does not obtain a certificate for you. The feature set changes with the address you browse from. On localhost the microphone works with no ceremony, which is why a local trial looks fine. From any other address it does not. A companion meant to follow you around the house or run on a second machine needs that reverse proxy and its certificate in place first, and the microphone needs testing from the non-localhost address rather than from the local one that already worked.
Offline mode still ships a dozen cloud SDKs and an MCP server config
The offline claim is about runtime behaviour, not about the install. The project dependency list includes anthropic, openai, groq, azure-cognitiveservices-speech, cartesia, elevenlabs and edge-tts, every one of them an SDK for a hosted service. Alongside those sit mcp[cli], duckduckgo-mcp-server, a top level mcp_servers.json, and a web_tool/ directory, which together mean the application can be pointed at tools that reach outside the machine. Both halves of that matter. On a genuinely air-gapped host you have to stage wheels for that whole list or take a different route, and a requirements set full of cloud clients is a heavier offline install than the description suggests. Meanwhile the privacy framing that conversations stay on your device depends on which backend you selected, not on the package set, because the code that can talk to a hosted API is installed either way. Visual perception adds a second axis: camera, screen recording and screenshots are local capabilities, and the browser permissions for them are granted separately from anything about the network.
Two license files, and the asset folders are not covered by the code license
The license field in the repository metadata reads NOASSERTION rather than naming a standard identifier, and the tree carries two license files side by side: LICENSE and LICENSE-Live2D.md. There are also asset directories at the top level, live2d-models/, avatars/, characters/ and backgrounds/, plus config_templates/, prompts/ and scripts/. Reading both files matters because they are not obviously the same grant. The separate LICENSE-Live2D.md file suggests the Live2D material may carry its own terms, so do not assume the code licence covers it. Redistribution is where this bites. A desktop client that bundles a companion, or a tutorial that includes an avatar, is shipping material from the asset folders under whatever LICENSE-Live2D.md permits, which may not be the permission the code carries. Copying one file and assuming it covers the repository is the mistake to avoid. Purely personal local use rarely surfaces any of this; packaging Open-LLM-VTuber into something you distribute means reading both files before you build.
Editorial conclusion
Open-LLM-VTuber suits someone who wants a voice companion with a Live2D face running against models they control, and who is willing to configure TLS and a reverse proxy before pointing a phone at it. It suits badly anyone planning a long feature-driven contribution, since the project asks that v1 feature requests be withheld while a rewrite is discussed, or anyone assuming a recent commit is in the released package. Before you start, decide whether you want the v1.2.1 tag or the current main branch, check that your Python is at least 3.10 and below 3.13, confirm your torch build matches your architecture, and read both LICENSE and LICENSE-Live2D.md before redistributing anything from the asset folders.
Frequently asked questions
what is open llm vtuber
Open-LLM-VTuber is a voice interactive AI companion with a Live2D avatar that runs locally on Windows, macOS and Linux. It supports real-time voice conversation and visual perception, works with a web version or a desktop client, and can run fully offline using local models.
how to install open llm vtuber
The README's Quick Start section points readers to the project's hosted documentation rather than carrying the steps inline, and the tree ships a top level dockerfile plus a run_server.py entry point. The declared interpreter range is >=3.10,<3.13, and dependencies are pinned through uv and pixi lockfiles.
how to set up open llm vtuber
The project uses simple module configuration, where functional modules are switched through configuration file changes rather than code edits, and it ships a config_templates/ directory plus a model_dict.json. Characters are customised by importing Live2D models, editing the Prompt for persona, and optionally voice cloning.
how to use open llm vtuber
It exposes a web version and a desktop client that can switch between a window and a transparent background pet mode. Beyond talking, it supports visual perception through camera, screen recording and screenshots, touch feedback by clicking or dragging, Live2D expression mapping driven by the backend, AI proactive speaking, chat log persistence, and showing the AI's inner thoughts without speaking them.
is open llm vtuber safe
Offline mode is available by running fully with local models so no internet is required and conversations stay on the device. The default dependency set still installs hosted service SDKs including anthropic, openai, groq, azure-cognitiveservices-speech, cartesia, elevenlabs and edge-tts, so which provider receives your audio depends on the backend you configure.
airi vs open llm vtuber
What Open-LLM-VTuber states about itself is that it is a voice interactive companion with a Live2D avatar, a named list of supported LLM, ASR and TTS backends, and both a web and a desktop client with pet mode.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/open-llm-vtuber-open-llm-vtuber)Star history chart for your README
[](https://hysenlabs.com/projects/open-llm-vtuber-open-llm-vtuber)Was this useful?