the pinned requirements contradict the stated maintenance goal
Hands-on Deep Reinforcement Learning, published by Packt
At a glance
- What is it?
- The code that accompanies a reinforcement learning book, kept in step with a moving pair of frameworks by a named maintainer, carrying a printed-book erratum in its own readme. The requirements file and the branch list tell you exactly how far that maintenance actually got: thirteen exact pins from 2018, a chapter that depends on an environment its provider withdrew, and a porting branch still described as unreleased.
- Who is it for?
- Read this as a fixed historical artefact rather than as a maintained example set, because that is what the pins make it. The stated intent is to keep the examples working against current frameworks, and the evidence in the repository is the opposite: exact pins from 2018 including two major deep learning frameworks, an interpreter floor of three point six, and a chapter whose environment no longer exists.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 8 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
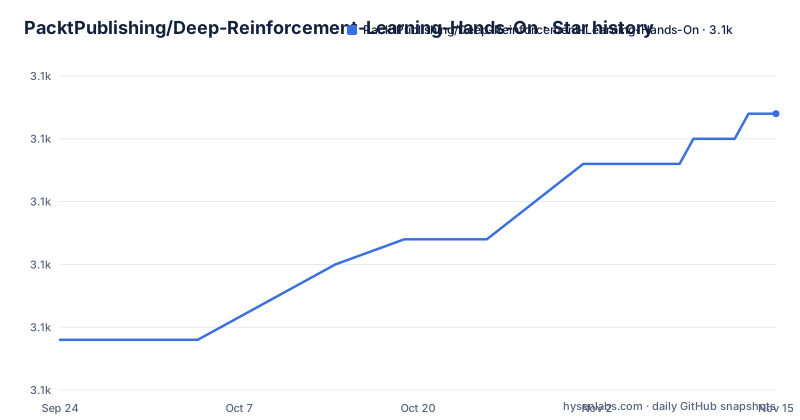
- PacktPublishing/Deep-Reinforcement-Learning-Hands-On3,116 ★ · +9
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| PacktPublishing/Deep-Reinforcement-Learning-Hands-On | 3.1k | 3.1k |
9 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The pinned requirements contradict the stated maintenance goal
The maintenance note in the file is specific about intent: the repository is kept by the book's author, who is trying to keep all the examples working under the latest versions of the two main frameworks, and says that this is not always simple as software evolves. Then the requirements file, thirteen lines long, pins every single package with an exact version and no ranges. Among them the deep learning framework is pinned to a 0.4.1 release and the other one to a 1.12 release, which is the generation before the current one renamed its execution model and dropped its compatibility promises entirely. The numerical stack is pinned the same way, including a scientific library at 1.1.0 and an array library at 1.15.4. So the two statements sit side by side: the goal is currency, the mechanism is total immobility. Nothing in the file explains why, and the obvious reason is that these pins are mutually dependent, since a framework that old will only install against an array library that old. The practical consequence is that this is not a set of examples you can run against what you have.
One chapter depends on an environment that was withdrawn
The file names its own broken chapter, which is more useful than a general warning would have been. It says that a universe environment, which is used extensively in chapter 13, was discontinued by its provider. Chapter 13 is the web navigation chapter, and the dependency it was built on is gone from the ecosystem, so the chapter cannot run as written on a current install. The repository root carries the answer in the form of two shell scripts, one that installs a successor environment and one that downloads it, which is what you would expect from a package the index no longer serves. So the breakage is real, acknowledged, attributed to the upstream decision rather than to the example, and has a workaround that has to fetch software from somewhere outside the normal install path. That is a complete and honest account of a dead chapter, and it is the single most useful sentence in the file for anyone deciding which chapters are still worth reading.
A porting branch is described as unreleased, eight years on
The file explains how it tracks major code changes, and the explanation is a list of three things with dates attached to two of them. A tag marks the code state immediately after publication in June 2018, so you can read the code as printed rather than as amended. The default branch is described as holding the latest version of the code, updated for the latest stable release of the framework, and the version it names is 0.4.1. And then a third entry, a branch for keeping the activity of porting the examples to version 1.0 of the framework, annotated with the words not yet released, whose link target is spelled as a placeholder rather than a path. So the file, in the present, still describes a porting effort as pending a release that shipped years ago, and points the default branch at a framework version from 2018 while describing it as current. That is consistent with the branch's last commit, dated in March 2026, which is the kind of gap where a status line written in 2018 simply stops being true and nobody notices.
Seventeen chapters, an interpreter floor of three point six, and a stray directory
The chapter list runs from chapter 2 to chapter 18, which is seventeen directories named with two digits each and sitting at the repository root. There is no chapter 1, which is normal for a book whose first chapter is theory. The contents span the usual arc for the field at the time: an introduction to the toolkit, deep learning with the framework, the cross entropy method, tabular learning and the Bellman equation, deep Q networks and their extensions, stock trading, policy gradients, actor critic and its asynchronous variant, chatbots trained with reinforcement learning, web navigation, continuous action spaces, trust region methods, black box optimisation, model-based imagination, and a chapter on the game of Go. The interpreter floor is one sentence in the requirements area, and it is three point six. One directory at the root is not in the list at all: a folder of formulas, undiscussed, which is the sort of thing that ends up in a book and gets left behind in the repository.
Two newsletters sit above the book title
The first third of the file is not about the book. It opens with two newsletter subscriptions, each with a campaign parameter on the link, each with a subscriber count in the text: one for data professionals and one for business intelligence practitioners, the second covering dashboards and reporting tools. Both are weekly, both are free, and the second is in a repository about reinforcement learning. That is a publisher's standard readme preamble rather than something specific to this project, and it is not hidden, but it does mean the file opens with two calls to action before a single sentence about the code. After them comes the title, one sentence identifying what the repository is, then the maintainer's note, then the version and compatibility section, which is where the actually useful material starts. If you are here for the examples, the first thing worth knowing is that everything you need is below the second horizontal rule.
The same book has two different addresses in one file
The title appears twice and so does the link to the book. The first mention, in the line identifying the repository as the code samples for the book, points at a store path ending in a practical-prefixed slug. The second, in the section written from the publisher's side with the campaign parameters attached, points at a different path with the full title spelled out. Both are the same book and both are in the readme, nine lines apart in the source. It is a small thing and it is the kind that survives because nobody clicks both. It matters a little more than usual here, because the search footprint around this repository is full of people looking for a specific edition of this specific book, and a repository that cannot agree on its own canonical address is not much help to anyone arriving from a search result looking for the third edition. The code is organised per chapter, so the directory names are the reliable index; the store link is the unreliable part.
A printed-book erratum lives in the code repository
The most careful thing in this file is an errata section, and it is formatted like one because it is one. It gives a page, a paragraph and a line, then states what the book says and what it should say. The error is a type claim about one of the grid world environments: both its observation space and its action space are said to be of a continuous class, and they should be discrete. That is a real and consequential mistake in a reinforcement learning book, because the space type determines which algorithms apply and how an agent encodes state, and getting it wrong sends a reader down the wrong path for a chapter. Keeping the correction in the repository rather than in a wiki or an issue is the right call, because the book cannot be reprinted and anyone working from a printed copy has no other way to find out. The rest of the file acknowledges the adjacent problem plainly: bugs in examples are inevitable, so the exact code might differ from the code printed in the text.
Editorial conclusion
Read this as a fixed historical artefact rather than as a maintained example set, because that is what the pins make it. The stated intent is to keep the examples working against current frameworks, and the evidence in the repository is the opposite: exact pins from 2018 including two major deep learning frameworks, an interpreter floor of three point six, and a chapter whose environment no longer exists. That is not a criticism of the maintainer, who says in the file that keeping examples current as software evolves is not always simple, and who names exactly which chapter broke and why. Two things to do before you use any of it. Check the requirements file rather than the prose, because the prose describes a goal and the file describes the state. And skip the web navigation chapter unless you already have a way to run its environment, since the two scripts at the repository root exist to fetch something the package index no longer serves.
Frequently asked questions
What is this repository for?
It holds the supporting project files for a published book on deep reinforcement learning, arranged as one directory per chapter from chapter 2 to chapter 18, and it is maintained by the book's author, who states the goal of keeping the examples working against the latest framework versions. It ships code only; the book itself is not part of the repository.
Which Python and framework versions do the examples need?
The file says the examples require Python 3.6, and the requirements file pins every package with an exact version and no ranges, including the deep learning framework at a 0.4.1 release, the other one at a 1.12 release, and the numerical stack at 2018 versions. That pins set is the authority; the prose about keeping things current describes the goal rather than the state.
Do all the chapters still run?
Not one of them, as written. The file states that the universe environment used extensively in chapter 13 was discontinued by its provider, and the repository root carries an install script and a download script for a successor environment. The reason for the scripts being shell scripts rather than a dependency line is that the package is no longer served in the usual way.
Is there a way to read the code as printed?
Yes. A tag marks the code state immediately after publication in June 2018, so you can check out the version that matches the printed book rather than the amended default branch. The file also notes that bugs in the examples are inevitable, so the exact code might differ from the text, and it carries an errata section with a page, paragraph and line reference for a correction to one environment's space types.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/packtpublishing-deep-reinforcement-learning-hands-on)Star history chart for your README
[](https://hysenlabs.com/projects/packtpublishing-deep-reinforcement-learning-hands-on)Was this useful?