FastDeploy's installer fetches a binary from a develop/latest path
High-performance Inference and Deployment Toolkit for LLMs and VLMs based on PaddlePaddle
At a glance
- What is it?
- FastDeploy is a PaddlePaddle-based serving toolkit for large language and vision language models with an OpenAI-compatible API. Its packaging pulls a router binary from a bucket path that ends in develop/latest, while its README declares Linux as the only supported operating system.
- Who is it for?
- FastDeploy fits a team already on PaddlePaddle that wants an OpenAI-shaped endpoint plus prefill and decode split across instances, and the feature list is unusually specific about formats rather than adjectives. Four things to settle before installing it.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 51 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
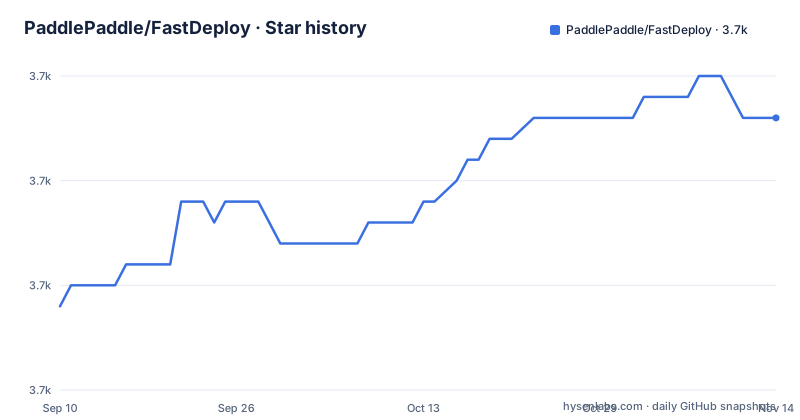
Star history
- PaddlePaddle/FastDeploy3,723 ★ · +9
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| PaddlePaddle/FastDeploy | 3.7k | 3.7k |
9 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three README files and a default branch called develop
The repository carries three readme files, README.md, README_CN.md and README_EN.md, and the one the page shows is the Chinese text, opening with a language switch that offers English as a link to README_EN.md and marks 简体中文 as the current page. The default branch is develop rather than main, which matters for anyone pinning a branch or reading a link that assumes main. The document itself is a release diary before it is a description: five dated entries run from v2.1 in 2025-08 through v2.5, each naming new models and features. Those entries carry their own dates, and they do not always agree with the tags. The v2.5 item is dated 2026-03 while the v2.5.0 tag is dated 2026-04-09, so the README announces a release a month before it was cut.
setup.py downloads a router from a develop/latest path
The packaging story is the most surprising part of this repository. setup.py carries a constant named FD_ROUTER_BASE_URL whose value is a URL under a paddle-pipeline/FastDeploy_ActionCE directory, ending in develop/latest, and a function called download_fd_router that fetches from it. There is no version, no checksum and no tag in that path: develop names a branch and latest names whatever that branch currently holds. The file then maps host architecture to a binary name and to a pattern it expects the file command to report, x86_64 to fd-router with an x86-64 pattern and aarch64 to fd-router-aarch64 with a pattern of aarch64 or ARM aarch64. So an install step performs a network fetch of a prebuilt binary and validates it by inspecting the output of file, which means the artefact you run is not pinned by anything in the package metadata.
The platform map knows four Windows architectures
The README states two requirements and they are short: the operating system is Linux, and Python is 3.10 to 3.12. The packaging file disagrees at the edges. setup.py defines a mapping from platform names to CMake build types, and the keys are win32 to Win32, win-amd64 to x64, win-arm32 to ARM and win-arm64 to ARM64. None of those appear in the requirements, the documentation links, or the hardware list. Whether the Windows branches still work is not something the repository answers, since the file only shows the mapping and not the code path that consumes it. It is a leftover of a portability effort that the visible documentation has stopped claiming, and it is the kind of thing worth checking before you assume a platform is unsupported because the README says so.
Development tools sit in the same requirements file
requirements.txt is not separated by purpose. Its first four entries are setuptools, pre-commit, yapf and flake8, which are contributor tools, and everything after them is runtime: openai>=1.93.0, uvicorn, fastapi, paddleformers>=1.1.1, redis, etcd3, httpx, gunicorn, triton, modelscope, safetensors>=0.7.0 and transformers>=4.55.1 with an upper bound below 5. Three entries carry consequences beyond ordinary dependencies. cupy-cuda12x is named for one specific CUDA major version, so the file as written assumes CUDA 12 regardless of the hardware you picked. flashinfer-python-paddle is not a version specifier but a direct wheel URL on a bucket, pinned to release 0.4.1.3. And OpenTelemetry arrives as eight separate packages, from the api and sdk through the distro, the OTLP exporter and instrumentation for redis, mysql, fastapi and logging, which is an unusually large surface for one optional feature.
Seven hardware guides, and a sentence that names five
The installation section lists seven links, one per accelerator: NVIDIA GPU, Kunlunxin XPU, Iluvatar CoreX, Enflame S60 GCU, Hygon DCU, Metax GPU and Intel Gaudi. The sentence immediately above them says FastDeploy supports installation on NVIDIA, Kunlunxin, Iluvatar, Enflame and Hygon plus other hardware, and Metax and Intel Gaudi are not in that sentence even though both have a guide linked below it. The feature list at the top of the same document does name all seven. So a reader scanning the prose gets five vendors and a reader following the links gets seven, and the header links above the fold point at the Chinese installation page for NVIDIA specifically, which is a third answer to the same question depending on which part of the page you read.
pyproject.toml configures tools and nothing else
There is no packaging metadata in pyproject.toml. The file contains tool sections only: isort with the black profile and paddle marked as third party, black with a line length of 119 and py310 through py312 as targets, and ruff with the same 119 character line length but target-version py310 only, excluding ./build and custom_ops/third_party. The ruff formatter is told quote-style = preserve, with a comment explaining that it stops some users from being converted to double quotes. The lint section ignores eleven codes, and the comments are the interesting part: UP038 is off because it causes a performance regression on Python 3.10, PYI056 is off because appending to __all__ is a common pattern in Paddle, and E501 is off because line length is handled by black instead. Packaging itself lives in the older setup.py, so a build here means two files agreeing with each other.
A news entry names one model and links to another
The v2.2 entry, dated 2025-09, is short: HuggingFace ecosystem compatibility, further optimisation, and new support for a model. The link text names it ERNIE-21B-A3B-Thinking. The URL it points at is a HuggingFace path under baidu that reads ERNIE-4.5-21B-A3B-Thinking, with the 4.5 inserted. So the visible name and the destination disagree about which model is meant, and the two spellings differ by more than formatting: one reads as a 21B model with 3B active parameters, the other as the 4.5 generation of the same shape. For anyone pinning a model in a deployment recipe, that is the line in the README to check against the model list rather than copy.
Four hardware-specific requirements files and a submodule
The tree shows how wide the support matrix has become. There are four requirements files beyond the main one, requirements_dcu.txt, requirements_iluvatar.txt, requirements_metaxgpu.txt and requirements_guided_decoding.txt, so Hygon, Iluvatar, Metax and guided decoding each pin their own dependency set rather than living behind optional extras. custom_ops/ holds the native side, and ruff is configured to skip custom_ops/third_party, a directory that arrives through .gitmodules rather than as tracked source. There are dockerfiles/, benchmarks/, tools/, scripts/ and a build.sh at the root, plus examples/ with five directories named cache_storage, intel_hpu, observability, router and splitwise, which between them cover the routing and disaggregation features the README advertises. A .claude/ directory and mkdocs.yml are also committed, so the documentation build and the assistant configuration both live in the same tree as the C++ and Python.
Editorial conclusion
FastDeploy fits a team already on PaddlePaddle that wants an OpenAI-shaped endpoint plus prefill and decode split across instances, and the feature list is unusually specific about formats rather than adjectives. Four things to settle before installing it. What your install actually downloads, since setup.py pulls a router binary from an unpinned path on a bucket whose name contains develop. Whether CUDA 12 is acceptable, because the requirements file names cupy-cuda12x unconditionally. Whether Linux is the only target, since the platform map in setup.py still knows about four Windows architectures. And which release line you want, since the default branch is develop while the newest tag is v2.5.0.
Frequently asked questions
What is PaddlePaddle FastDeploy?
An Apache-2.0 licensed inference and deployment toolkit for large language models and vision language models, built on PaddlePaddle. It offers an OpenAI API service that is also compatible with the vLLM interface, deployable with a single command, and it states that it referenced and borrowed some vLLM code to keep interface compatibility.
What are the system requirements for FastDeploy?
The README states two: Linux as the operating system, and Python 3.10 to 3.12. Hardware guides are provided for NVIDIA GPU, Kunlunxin XPU, Iluvatar CoreX, Enflame S60 GCU, Hygon DCU, Metax GPU and Intel Gaudi.
Which quantization formats does FastDeploy support?
The feature list names W8A16, W8A8, W4A16, W4A8, W2A16 and FP8. The v2.5 news entry adds a W4AFP8 quantization method, and the tree carries a separate requirements_guided_decoding.txt for guided decoding.
What does PD disaggregation mean in FastDeploy?
Prefill and decode are split across separate instances with load balancing, context caching and dynamic instance role switching. Version 2.4 added it for DeepSeek V3 and Qwen3-MoE, and the documentation includes a load-balancing router page plus a splitwise example directory.
Does installing FastDeploy download a binary at install time?
setup.py contains a constant FD_ROUTER_BASE_URL pointing at a paddle-pipeline/FastDeploy_ActionCE/develop/latest path and a download_fd_router function, with an architecture map expecting fd-router for x86_64 and fd-router-aarch64 for aarch64, checked against an expected file output pattern.
What is the default branch of the FastDeploy repository?
develop, not main. The newest release is v2.5.0, tagged 2026-04-09, while the README's own news entry for v2.5 is dated 2026-03. The repository also carries three readme files: README.md, README_CN.md and README_EN.md.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/paddlepaddle-fastdeploy)Star history chart for your README
[](https://hysenlabs.com/projects/paddlepaddle-fastdeploy)Was this useful?