lorax: adapters that come and go, and a Rust router in front of them
Multi-LoRA inference server that scales to 1000s of fine-tuned LLMs
At a glance
- What is it?
- Predibase's inference server for hosting thousands of LoRA adapters over one base model, with just-in-time adapter loading and a batching layer that mixes adapters in the same batch. The tag naming changed in 2025 and the Rust workspace carries its own version number.
- Who is it for?
- Take lorax if you have many fine-tuned adapters over a shared base model and one GPU, and if per-request adapter selection plus an OpenAI-compatible endpoint is the shape you need. Check three things first.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- No. The owners have archived the repository on GitHub, so it is read-only and no longer receives changes.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
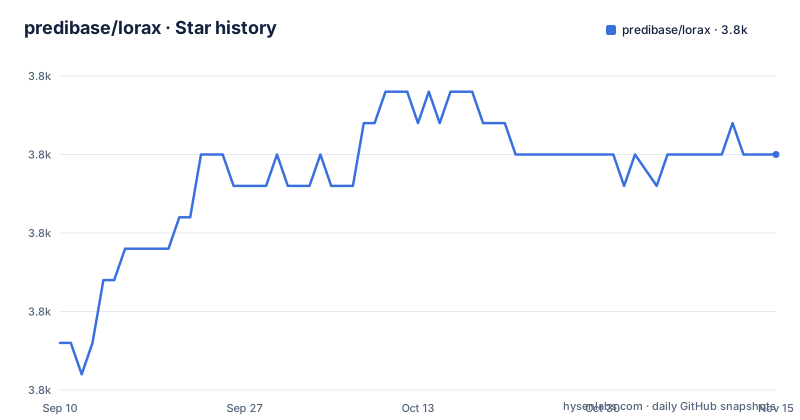
Star history
- predibase/lorax3,835 ★ · +6
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| predibase/lorax | 3.8k | 3.8k |
6 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Adapters load per request and merges are an explicit cost
The core mechanism is that the adapter is an argument to the request rather than a property of the server. Any fine-tuned LoRA adapter from HuggingFace, from Predibase, or from any filesystem on disk can be named in the request, and it is loaded just-in-time without blocking concurrent requests. That last clause is the load-bearing one: a request arriving for an adapter nobody has asked for in a while does not stall the batch behind a disk read or a host-to-device copy. The same flexibility extends to combining adapters: you can merge adapters per request to create an ensemble on the fly. The README presents this as a feature, and it is, but it is worth reading as a cost decision too, since merging weights is work that happens inside the latency budget of that particular request rather than once at startup. If your use is one adapter at a time, you pay nothing for the capability; if it is ensembles, you are trading latency for flexibility deliberately.
Heterogeneous batching is what makes many adapters affordable
Serving one adapter per GPU is easy. Serving a thousand is a scheduling problem, and the two features that address it are named separately because they solve different halves. Heterogeneous continuous batching packs requests for different adapters together into the same batch, which keeps latency and throughput nearly constant as the number of concurrent adapters grows, rather than degrading with it. That claim is the load-bearing one for the whole project, because the alternative, batching only same-adapter requests, means throughput scales with the number of adapters rather than with the hardware. Adapter exchange scheduling is the other half and it is explicitly asynchronous: adapters are prefetched and offloaded between GPU and CPU memory, and request batching is scheduled to optimise the aggregate throughput of the system. So the design is that the resident set is whatever fits, and the churn between GPU and CPU is hidden behind the scheduler rather than paid per request.
A Rust router and launcher sit in front of the Python server
The repository is not a Python project with a Rust helper. The Cargo workspace declares four members: `router`, `router/client`, `router/grpc-metadata`, and `launcher`, which is the routing layer and process launcher for the Python inference server. The Dockerfile builds them with a Rust 1.83 base image and cargo-chef for dependency caching, and it fetches protoc as a versioned release archive rather than from a package index, unpacking the compiler into the image before the build. There is a `proto/` directory at the root and a `grpc-metadata` crate, so the router talks to the server over a protocol rather than by reading its memory. The Makefile separates the two halves cleanly: `install-server` builds the Python side, `install-router` and `install-launcher` build the Rust binaries with `RUSTFLAGS="-D warnings"`, and `install` chains the server, router, launcher, and custom kernels together. The workspace version is 0.1.0, which is a detail worth knowing if you read version numbers out of the source.
Custom kernels are opt-in and the project warns about them
The inference optimizations are described as pre-compiled CUDA kernels, with three named: flash-attention, paged attention, and SGMV, alongside tensor parallelism, quantization, and token streaming. The build gate on those is a separate make target rather than part of the normal install, and the reason it exists is printed in the target itself: if the `BUILD_EXTENSIONS` environment variable is not set to `True`, the target does nothing and prints a message saying custom kernels are disabled and that you need to set it, with a parenthetical pointing at the documentation and warning that kernels might not work on all hardware. That is a blunt and honest gate. The practical consequence is that the documented getting-started path is the prebuilt Docker image, which the README recommends precisely so you avoid compiling custom CUDA kernels and other dependencies, and the minimum system requirements for that path are an Nvidia GPU of Ampere generation or above, CUDA 11.8 compatible drivers or newer, Linux, and Docker.
Two release names and a Rust workspace version, none of them aligned
Version identification in this repository is genuinely confusing and worth sorting out before you pin anything. The recent releases are `lorax-0.4.0` from 2025-01-13, then `v0.12.1` from 2024-11-25, then `v0.12.0` from 2024-11-06. So the naming scheme changed between the 0.12 series and the 0.4 series, and it went backwards in number, which means neither line can be sorted by version string alone. Separately, the Rust workspace declares its own version as 0.1.0 with edition 2021, and it is not the project's version at all, only the crate set's. The infrastructure reinforces the point: the tree carries a `sagemaker-entrypoint.sh` and a separate `container-entrypoint.sh`, Helm charts under `charts/`, a `Dockerfile.dev` alongside the production one, a `.devcontainer/`, plus `integration-tests/` with pytest snapshot updates and a `load_tests/` directory. Anything that pins this project by tag needs to handle both naming schemes.
Base model and adapter are configured separately
Serving a fine-tuned model here is a two-part configuration, and separating them is what allows one GPU to hold many models. The base model is the pretrained large model shared across all adapters, and the adapter is the task-specific weights loaded per request. The server is started with a base model at launch time, through the `--model-id` argument in the documented Docker run, while the adapter is named inside the request payload as `adapter_id`. Supported base models are named as Llama including CodeLlama, Mistral including Zephyr, and Qwen, with the documentation carrying the complete list of supported architectures. Base models load in fp16 or quantized with bitsandbytes, GPT-Q, or AWQ. Supported adapters are those trained with the PEFT and Ludwig libraries, and any linear layer in the model can be adapted via LoRA. That last point is the practical one for anyone with a custom fine-tune: the constraint is the adapter format, not a fixed list of layers.
Three documented ways to reach the same server
The request surface is deliberately conventional. The REST route is a POST to `/generate` with a JSON body carrying `inputs` as the prompt string and a `parameters` object holding `max_new_tokens` and, when you want one, `adapter_id`. That means the difference between prompting the base model and prompting an adapter is one extra key in the same body, which is why an existing integration against a text generation endpoint can usually be pointed at it with a field added. Above that sits an OpenAI-compatible API supporting multi-turn chat conversations, plus structured output in JSON mode. A Python client is a separate package:
pip install lorax-clientIt is used through a `Client` object bound to a base URL, whose `generate` call takes the prompt, `max_new_tokens`, and an optional `adapter_id`. Deployment is not Docker-only either: besides the container route, the documentation links Kubernetes, SkyPilot, and local runs, and the repository carries both Helm charts and a SageMaker entrypoint.
Editorial conclusion
Take lorax if you have many fine-tuned adapters over a shared base model and one GPU, and if per-request adapter selection plus an OpenAI-compatible endpoint is the shape you need. Check three things first. Adapters are merged per request if you ask for an ensemble, so a merge costs you time on that request rather than being free, and the feature exists because throughput is a budget. The custom CUDA kernels are opt-in behind a `BUILD_EXTENSIONS` environment variable and the project's own make target warns they might not work on all hardware, so the prebuilt image is the safer starting point. And the tag naming changed from `v0.12.x` in late 2024 to `lorax-0.4.0` in January 2025, so a version-based pin in a script or a Helm chart needs checking rather than assuming continuity.
Frequently asked questions
What is lorax used for?
It is a multi-LoRA inference server that scales to thousands of fine-tuned models on a single GPU, reducing serving cost without giving up throughput or latency. Adapters load just in time per request and requests for different adapters are batched together.
Which base models does lorax support?
Llama including CodeLlama, Mistral including Zephyr, and Qwen, with the full list on the supported architectures page. Base models load in fp16 or quantized with bitsandbytes, GPT-Q, or AWQ, and adapters trained with PEFT and Ludwig are supported.
What does lorax need to run?
The documented minimum is an Nvidia GPU of Ampere generation or above, CUDA 11.8 compatible device drivers or newer, Linux, and Docker. Using the prebuilt image also requires the nvidia-container-toolkit, followed by a daemon reload and a Docker restart.
What licence is lorax under?
Apache 2.0, and the feature list states this plainly as free for commercial use. The LICENSE file is at the repository root.
Why did my lorax build skip the custom kernels?
The make target only builds them when the BUILD_EXTENSIONS environment variable is set to True, and otherwise prints that custom kernels are disabled and that kernels might not work on all hardware. The recommended starting point is the prebuilt Docker image to avoid compiling them.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/predibase-lorax)Star history chart for your README
[](https://hysenlabs.com/projects/predibase-lorax)Was this useful?