RAG-Fusion ships an honest negative result, and a headline it does not support
RAG-Fusion: multi-query generation + Reciprocal Rank Fusion for better retrieval-augmented generation. Includes evaluation harness with NFCorpus/BEIR.
At a glance
- What is it?
- Multi-query generation plus reciprocal rank fusion, with an evaluation harness and write-ups that report confidence intervals, a replicated paper, a parser bug and a router that saved money on the wrong queries. The measured configuration and the configuration the code demonstrates are not the same one.
- Who is it for?
- Read this one for its evaluation discipline rather than for the technique, because the technique is not the interesting part: multi-query rewriting and rank fusion are a paragraph long.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 36 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
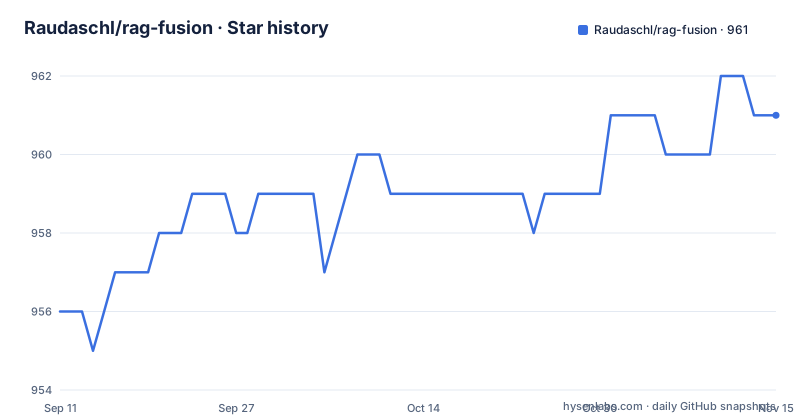
- Raudaschl/rag-fusion961 ★ · +5
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| Raudaschl/rag-fusion | 956 | 961 |
5 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The headline says next frontier, the write-up says the original form is a wash
The file opens with a title calling this the next frontier of search technology.
Then, in the blockquote that answers what the technique is worth, the same file says the vector-only fusion variant is roughly a wash once a reranker is added, and ends with a deployment instruction: deploy the hybrid variant and put your strongest reranker behind it.
Those two statements are about different configurations, which is fair, but they are separated by two lines in the same document. A reader who skims the title and one paragraph concludes the technique is an improvement; a reader who reads the boxquote concludes the technique only pays once a cross-encoder is doing the reading.
There is a second, sharper version of the same gap in the code. The file says the original version of the technique used vector search only and no reranker, and that this is what the top-level pipeline script still demonstrates, while the configuration the experiments found to work has its code in the evaluation directory.
So the first thing a new user runs is the superseded version. That is a defensible choice for keeping the original article's code intact and reproducible, and an unfortunate one for anyone who starts by running the thing at the top of the repository.
The lift is 0.025 with a cross-encoder and 0.050 with a decision model
The retrieval numbers are given precisely enough to be checked.
The configuration named is hybrid with diversity plus reranking: BM25 and vector search for the original query and for the LLM's rewrites, merged with reciprocal rank fusion, then reranked. On that setup, NDCG@10 improves by 0.025 with a large cross-encoder and by 0.050 with the decision model, on two hundred queries, with confidence intervals that exclude zero.
That last clause is the one that makes the claim worth reading. A measurement with a stated sample size and an interval that excludes zero is a claim you can weigh. The same paragraph is equally clear that the effect on the generated answer is different in kind: fusion won more comparisons than it lost in all three judge runs, and significantly in two of them. Three runs, one not significant, described as positive but noisy.
Four rerankers were tried, and the write-up says the improvement held on every one, with the largest effect behind the strongest. That pattern matters more than any single number, because it says the gain comes from having a reranker at all rather than from a particular reranker.
The measurements are per configuration and the file says so, listing cost and latency for each. There is also a narrated video explaining one specific finding, and the write-up behind it lives in the experiments directory.
The model that writes the rewrites also writes the answer and judges it
One detail in the setup section sits underneath the retrieval results and deserves more attention than it gets.
The same language model does three jobs: it writes the query rewrites, it writes the answer, and it acts as the judge in the answer comparisons. The default is named in the setup instructions, at low reasoning effort, and can be overridden with a model variable and a reasoning-effort variable.
That means the answer-level evidence has no independent judge. The comparisons that produced the three judge runs were made by a model that also produced the material being judged, which means a shared bias in that model flatters the technique on both sides of the comparison at once.
The retrieval numbers do not have this problem, because NDCG@10 is computed against relevance labels and needs no judge at all. So the repository's two headline claims have different epistemic weight: the retrieval improvement is measured against ground truth, the answer improvement is measured against a model that is also a participant.
That is not a criticism of the work so much as a description of what it can support. Anyone deciding whether to deploy fusion should weigh the retrieval number and treat the answer number as suggestive.
The replication found a parser bug and published a correction for it
Two experiment write-ups exist, and their dates and titles say more about the project than a changelog would.
The September one covers four rerankers including the decision model, the cost and latency of each configuration, three different ways of placing that model inside the fusion step, and a rewrite-parser bug that was found and fixed along the way.
The April one is a replication of a specific arXiv paper, and it carries a correction note about that same parser bug.
That is an unusual combination. Replicating another paper is a commitment of hours, and finding a bug in the tooling that affects the replication is the kind of thing that usually stays in a local commit message. Publishing a correction note means anyone who reads the replication learns what was wrong before they draw a conclusion from it.
The same attitude shows up in the router result. One routing approach was tested, using the decision model to classify each query's type. It fused seventy-eight percent of queries and saved about a fifth of the rewrite calls at no measurable cost, and the write-up says in plain terms that it did not target the queries where fusion helps.
A saving with no loss is the best kind of result, and reporting it as the wrong saving is the part that makes the rest of the numbers credible.
Fusion costs 1.5 seconds, not money, and the file says so first
The cost section is short and specific, and its conclusion is that the price is latency.
With a small rewrite model, the rewrite call is given as about six cents per thousand queries, and about 1.5 seconds of added latency before the extra searches can run. The recommendation that follows is the useful one: adding keyword search to vector search, without any rewrites, is close to free and worth doing everywhere.
That separates two things people usually bundle together. Hybrid search is nearly free and helps. Rewriting is what costs the second. The measurement per configuration is in the write-up, so the arithmetic is available rather than asserted.
The fit criteria are three conditions: a vocabulary mismatch between queries and indexed text, a situation where missing a relevant document costs more than including a marginal one, and a downstream consumer that can handle broad context, whether that is a strong synthesis model or a user interface showing several candidates.
The poor-fit list is equally concrete. Curated support knowledge bases and FAQ bots, latency-critical retrieval such as autocomplete and sub-second chat, high-volume consumer search, code and identifier search where precision dominates, and anything structured: knowledge graphs, SQL-backed retrieval. The long-tail shopping example is the clearest illustration of when rewrites earn their cost, turning a vague description into a product term.
Four rewrites times two searches gives ten lists and a pool of fifty
The mechanism is short enough to hold in your head, which is part of why the technique spread.
An LLM writes several rewrites of the user's query, approaching it from different angles: synonyms, narrower and broader framings, and related sub-topics. Then the original query and every rewrite are searched twice, once with keyword search and once with vector search. Four rewrites plus the original is five queries, and two methods on each is ten ranked lists.
The lists are merged by reciprocal rank fusion. Each document scores the reciprocal of sixty plus its rank, summed across every list it appears in. The constant is what stops a top result from running away with the score, and the effect of the sum is that a document which keeps turning up across differently-phrased queries rises above one that dominated a single phrasing.
That last property is the actual argument for the technique. A document that matches five different phrasings of the same need is more likely to be the document you wanted than one that won one phrasing decisively.
The fused pool is fifty candidates. A reranker re-scores it, either a cross-encoder or the decision model, and only the top five to ten reach the model that writes the answer. So the answer model never sees the fused noise, only what survived a model built for ranking.
The evaluation directory is where this lives: separate modules for dataset loading, metrics, retrieval methods, the reranking stage, a disk-persisted cache for the rewrites, and a sweep runner.
A rewrite cache is committed at the repository root
Two small things in the file listing are worth a note, because neither is a defect and both are surprising.
The first is a cache file. The query cache is described as disk-persisted and its purpose is to hold LLM query rewrites, and a file with that name sits at the top level of the repository alongside the pipeline script and the evaluation entry point. A cache is a build artifact by nature, and committing one means the committed contents are the rewrites someone happened to generate while running the evaluation. Nothing in the file describes what it contains beyond the rewrites.
The second is the dataset coverage. The repository description names two retrieval benchmarks, one of which is a specific corpus, and the project structure describes the dataset module as download and load for that one corpus. The other named benchmark does not appear in the visible file listing, so either it is handled inside the same module or the description is ahead of the code.
Setup is deliberately small. Six packages cover the base pipeline, and three more are needed only for the reranking experiments:
pip install openai chromadb python-dotenv tqdm tabulate rank_bm25pip install sentence-transformers flashrank typesafe-sdkThe key you need is one:
cp .env.example .envNeither point undermines the results. They do mean that the reproducibility story rests on the write-ups in the experiments directory rather than on what a fresh clone gives you, which is the right place for it to rest anyway.
There are no published releases, so nothing here is versioned for citation. The licence is MIT and the last commit on record is 27 September 2026.
Editorial conclusion
Read this one for its evaluation discipline rather than for the technique, because the technique is not the interesting part: multi-query rewriting and rank fusion are a paragraph long. What is worth your time is a repository that reports a wash for its own original form, gives confidence intervals, states that its judge model also wrote the rewrites and the answers, replicates someone else's paper and publishes a correction when it finds a bug in the replication, and admits that its one router saved calls on the wrong queries. Before you deploy it, three things to settle. Which configuration you are actually running, since the headline file still demonstrates the vector-only version the experiments rejected. Whether your workload can absorb 1.5 seconds and whether recall matters more than precision in your case, because the poor-fit list is long and specific. And whether you have an independent way to judge answers, because the answer-level claim in the write-up has no judge that did not also write the query rewrites.
Frequently asked questions
What is RAG-Fusion in this repository?
A search methodology where an LLM writes several rewrites of the user's query, the original query and every rewrite are searched with both BM25 and vector search, the resulting ten ranked lists are merged with reciprocal rank fusion, and a reranker re-scores a pool of fifty candidates before an answer model sees the top five to ten.
Does RAG-Fusion always improve retrieval?
Not in its original form. The repository's own measurements say the vector-only variant without a reranker is roughly a wash once a reranker is added, and that the hybrid variant with a reranker is the one to deploy. On that setup it reports +0.025 NDCG@10 with a large cross-encoder and +0.050 with a decision model, at n=200 with confidence intervals excluding zero.
What does RAG-Fusion cost to run?
Mostly latency rather than money. With a small rewrite model the rewrite call is about six cents per thousand queries and adds about 1.5 seconds before the extra searches can run. Adding BM25 to vector search with no rewrites is described as close to free and worth doing everywhere.
When is RAG-Fusion the wrong choice?
The README lists FAQ and customer-support knowledge bases, latency-critical retrieval such as autocomplete or sub-second chat, high-volume consumer search, code and identifier search where precision dominates, and structured retrieval over knowledge graphs or SQL. It also needs a downstream consumer that can handle topically broad context.
How does reciprocal rank fusion score a document here?
Each document scores the reciprocal of 60 plus its rank in a list, summed over every ranked list it appears in, so a document that keeps appearing across differently phrased queries rises above one that won a single phrasing. Four rewrites plus the original query, searched two ways, produce ten lists and a fused pool of fifty candidates.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/raudaschl-rag-fusion)Star history chart for your README
[](https://hysenlabs.com/projects/raudaschl-rag-fusion)Was this useful?