Mini-SGLang: reading a 5,000 line LLM server, and its platform ceiling
A compact implementation of SGLang, designed to demystify the complexities of modern LLM serving systems.
At a glance
- What is it?
- Mini-SGLang is a compact reimplementation of SGLang meant to be read, but its real constraints are not the ones the feature list advertises: it is Linux only, its dependency list has ceilings as well as floors, and the package lives one directory below the repository root.
- Who is it for?
- Mini-SGLang fits an engineer who wants to understand how a serving stack is put together and is willing to run it on Linux with a matching CUDA toolkit, and it fits a reader who will never run it at all, because about 5,000 lines of Python with type annotations is a short enough path to the radix cache and the chunked prefill logic.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 6 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
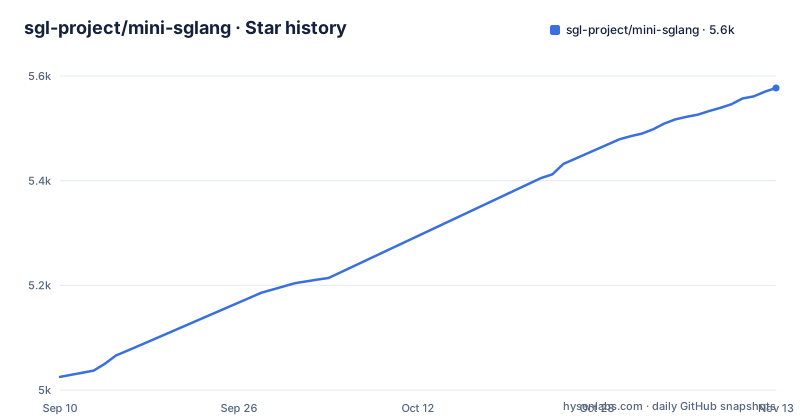
- sgl-project/mini-sglang5,577 ★ · +552
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| sgl-project/mini-sglang | 5k | 5.6k |
552 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Linux only, and two compiled kernels decide that
Platform support is the first constraint the project states. Mini-SGLang runs on Linux, x86_64 and aarch64, and Windows and macOS are excluded because of dependencies on Linux specific CUDA kernels, named as sgl-kernel and flashinfer. Both names reappear in the dependency list as sgl_kernel>=0.3.17.post1 and flashinfer-python>=0.5.3, so this is a hard boundary rather than a preference. The project points Windows users at WSL2 and suggests Docker for cross platform work. If you are on a Mac, nothing here runs natively: reading the code still works, and the Docker route assumes a `--gpus all` flag, which needs the NVIDIA Container Toolkit. One more prerequisite matters before any of that: the kernels are JIT compiled, so the NVIDIA CUDA Toolkit has to be installed, its version has to match the driver, and nvidia-smi is the check the project points you at.
uv venv first, then an editable install from a clone
The install path the project recommends starts with uv, and it notes that uv does not conflict with conda:
uv venv --python=3.12
source .venv/bin/activate
The source install is three commands, and the second one chains the environment setup onto the clone:
git clone https://github.com/sgl-project/mini-sglang.git
cd mini-sglang && uv venv --python=3.12 && source .venv/bin/activate
uv pip install -e .
Python 3.12 is what every example uses, while pyproject.toml declares requires-python >=3.10 and carries classifiers for 3.10, 3.11 and 3.12. The top level entries put the package under python/, the benchmark scripts under benchmark/ and the tests under tests/.
package-dir points setuptools one directory down
The packaging configuration is what makes the layout unusual:
[tool.setuptools]
include-package-data = true
package-dir = {"" = "python"}

[tool.setuptools.packages.find]
where = ["python"]
include-package-data is on and the package-data pattern ships csrc/**/*, so extension sources travel with the distribution instead of existing only in the checkout. Everything else at the top level sits outside the package: docs/, benchmark/, tests/, assets/ and the Dockerfile. The recommended install is `uv pip install -e .` from a clone, and the server is started as a module, `python -m minisgl`. The distribution is named minisgl at version 0.1.0, and its classifiers say Development Status :: 3 - Alpha, which tells you more about intended use than the feature list does.
Dependency ceilings can force an existing environment to change
The dependency list is where a shared environment tends to break:
requires-python = ">=3.10"
torch<2.10.0
transformers>=4.56.0,<=4.57.3
flashinfer-python>=0.5.3
sgl_kernel>=0.3.17.post1
There are ceilings as well as floors, and transformers is held between 4.56.0 and 4.57.3. Alongside them sit accelerate, msgpack, modelscope, pyzmq, uvicorn, fastapi, prompt_toolkit, openai, apache-tvm-ffi>=0.1.4 and quack-kernels, which is the serving stack rather than the model stack. The consequence is concrete: an environment already carrying a newer torch or a newer transformers has to move to install this, and the closed window means an upstream fix cannot reach you until a release here widens it. Development tooling lives in a separate extra, with pytest, pytest-cov, black, flake8, mypy, pre-commit, ruff, matplotlib and pyarrow, and both black and ruff target py310 with a line length of 100.
The WSL2 note says port 8000 while every Docker example maps 1919
The two platform walkthroughs disagree about where the server listens. The WSL2 section says the server will be reachable at http://localhost:8000 from Windows, while the Docker examples map 1919 to 1919:
docker run --gpus all -p 1919:1919 \
    minisgl --model Qwen/Qwen3-0.6B --host 0.0.0.0
The serving examples show that the port is a flag rather than a constant:
python -m minisgl --model "Qwen/Qwen3-0.6B"
python -m minisgl --model "meta-llama/Llama-3.1-70B-Instruct" --tp 4 --port 30000
That first command sets no port at all, so the documented 8000 is not a number you can rely on for either the default or the container. Pass --port yourself. The --host 0.0.0.0 in the container example is a separate decision from the port mapping: it is what makes the mapped port reachable from outside the container, and it is the setting to drop when you do not want the server bound to every interface.
The image runs as uid 1001 and splits build from runtime
The container is a two stage build on a CUDA devel base, with the versions exposed as build arguments: CUDA 12.8.1, Ubuntu 24.04 and Python 3.12. The runtime stage creates an unprivileged user instead of staying root:
ARG CUDA_VERSION=12.8.1
FROM nvidia/cuda:${CUDA_VERSION}-devel-ubuntu${UBUNTU_VERSION} AS builder
RUN useradd --create-home --shell /bin/bash --uid 1001 minisgl
Three cache directories are created and chowned to that user, and the run the project recommends mounts them as named volumes:
docker run --gpus all -p 1919:1919 \
    -v huggingface_cache:/app/.cache/huggingface \
    -v tvm_cache:/app/.cache/tvm-ffi \
    -v flashinfer_cache:/app/.cache/flashinfer \
    minisgl --model Qwen/Qwen3-0.6B --host 0.0.0.0
Those three hold the model download, the FFI layer and the attention backend, and the volumes are recommended for faster subsequent startups. Skip them and the JIT compiled pieces are rebuilt on every launch. An interactive session in the same image is one flag away, --shell, and that terminal chat accepts /reset to clear the history.
The online benchmark compares with prefix caching switched off
The offline measurements come from benchmark/offline/bench.py on a single H200, with 256 sequences over Qwen3-0.6B and Qwen3-14B and input and output lengths sampled between 100 and 1024 tokens. Setting MINISGL_DISABLE_OVERLAP_SCHEDULING=1 gives an ablation of the overlap scheduler. The online side uses benchmark/online/bench_qwen.py on four H200s joined by NVLink with Qwen3-32B, replaying the first 1000 requests of a published Qwen trace. Read the two launch commands before reading any result from them:
python -m minisgl --model "Qwen/Qwen3-32B" --tp 4 --cache naive
python3 -m sglang.launch_server --model "Qwen/Qwen3-32B" --tp 4 \
    --disable-radix --port 1919 --decode-attention flashinfer
SGLang runs here with its radix cache disabled and Mini-SGLang with a cache set to naive, so the published comparison measures both systems with prefix caching removed. The radix cache is the feature the overview leads with, and it is exactly what this setup does not exercise. Method details are left to the benchmark README, and the argument list and data flow to docs/features.md and docs/structures.md.
Editorial conclusion
Mini-SGLang fits an engineer who wants to understand how a serving stack is put together and is willing to run it on Linux with a matching CUDA toolkit, and it fits a reader who will never run it at all, because about 5,000 lines of Python with type annotations is a short enough path to the radix cache and the chunked prefill logic. Pass on it as a production server, since the distribution is version 0.1.0 and its own classifiers call it Alpha, and pass if your environment already carries a newer torch or transformers. Before you start, check your platform, count the version ceilings you would have to satisfy, and read the benchmark launch commands, because the published comparison disables prefix caching on both sides.
Frequently asked questions
Can mini-sglang run on Windows or macOS?
No. The project states Linux only, x86_64 and aarch64, because Mini-SGLang depends on Linux specific CUDA kernels named sgl-kernel and flashinfer. Windows users are pointed at WSL2, and Docker is offered for cross platform work.
How do I install mini-sglang?
Create the environment with `uv venv --python=3.12`, activate it, clone the repository and run `uv pip install -e .`. The NVIDIA CUDA Toolkit must be installed with its version matching the driver, and pyproject.toml requires Python 3.10 or newer.
Which flags does the mini-sglang server take?
The examples use --model, --tp for tensor parallelism, --port, --host, and --shell for the terminal chat, plus --model-source modelscope as a fallback when HuggingFace downloads fail. The full list of features and command line arguments is kept in docs/features.md.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/sgl-project-mini-sglang)Star history chart for your README
[](https://hysenlabs.com/projects/sgl-project-mini-sglang)Was this useful?