The full model's Stage 1 needs column examples the public data does not contain
Implementation and resources for Sheet as Token, a graph-enhanced framework for multi-sheet spreadsheet understanding and retrieval.
At a glance
- What is it?
- A two-stage retrieval pipeline for spreadsheets, where sheets are matched by their headers and never by their contents. The released data is metadata only, the default corpus in the repository differs from the one in the paper's name, and no checkpoints or licence ship with it.
- Who is it for?
- Read it as a paper artefact rather than a drop-in component, since reproducing it means retraining both stages and the numbers in the paper were produced on a different query workload than the one in the public corpus. Three things to establish before you start.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 40 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
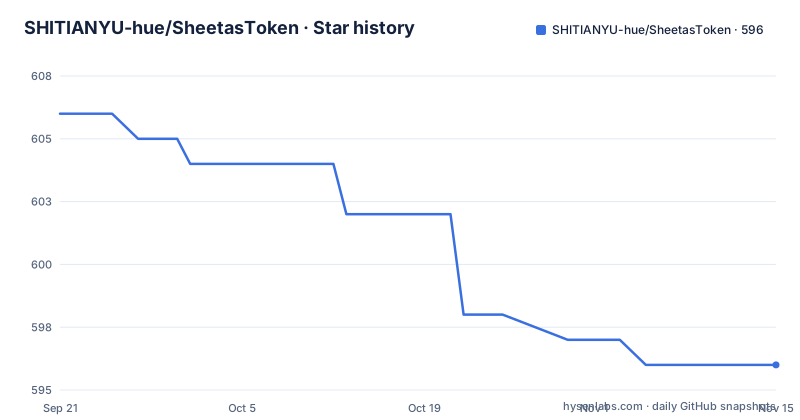
- SHITIANYU-hue/SheetasToken596 ★ · -10
| Repository | 2026-09-21 | 2026-11-15 |
|---|---|---|
| SHITIANYU-hue/SheetasToken | 606 | 596 |
-10 Stars in the last 55 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The full model's Stage 1 needs examples the release omits
The repository structure makes the ablation design visible. Stage 1 has three files. One is described as a legacy or early baseline kept for reference only. The other two are the real pair: an encoder using example-enhanced sheet serialization, and an encoder without column examples.
The paper experiment mapping then says the full model is the example-enhanced variant at Stage 1 with the enhanced graph retriever at Stage 2, and that the architecture ablation keeps example-enhanced Stage 1 and swaps in the baseline Stage 2.
So the axis the paper varies is not whether examples are used. It is which Stage 2 sits on top, and the example-enhanced encoder is fixed as the better one.
Now put that next to the data policy. Every checked-in sheet file is described as metadata only, containing sheet IDs, names, dimensions and column names, with no cell or example values. Stage 1 itself is said to serialize only the sheet name, dimensions and column headers.
The two statements cannot both be complete. The configuration the paper calls its full model serializes column examples, and the public data contains none. Anyone reproducing from this release has to supply those examples from somewhere else, or train the variant the paper did not use as its best. The repository does not say where they come from.
It is the single most consequential gap in an otherwise unusually careful release, and it is a gap created by two individually reasonable decisions: publish no cell data for privacy, and keep the ablation axis the paper used.
Sheets are matched by their headers, never by their contents
The core modelling decision is stated once and not argued anywhere: Stage 1 serializes only the sheet name, its dimensions and its column headers.
That makes the retrieval task a schema-matching problem. Given a natural-language query, the system finds the spreadsheet whose column names describe the query, without ever reading a value. Everything downstream inherits that constraint.
The corpus reflects it. The checked-in files carry sheet identifiers, names, dimensions and column names, and the release states plainly that no cell or example values are included. A separate data readme is referenced for exact counts, the public schema and validation commands, which is the right place for the contract.
The upside is that the dataset can be published at all. Cell values are the part of a spreadsheet that leaks, and a benchmark that ships only structure is a benchmark anyone can download and check. The downside is that two sheets with identical headers are indistinguishable, and that a query which depends on what is in a column rather than what it is called cannot be answered by Stage 1 at all.
So the reported retrieval figures describe schema retrieval, and a reader comparing them against a content-based retriever is comparing different tasks.
The scripts default to BERT while the paper's Stage 1 is BGE
The environment section says the scripts default to a Hugging Face model name, and names it: a base uncased BERT. Overriding it means setting a model-name variable when running a script.
The overview says Stage 1 fine-tunes BGE for query-to-sheet retrieval, and the current pipeline is described as a fine-tuned BGE retriever over the complete sheet corpus. The zero-shot baselines name a specific BGE variant as the frozen embedding retriever.
So the shipped default and the described model are different encoders. The default is the general-purpose base BERT checkpoint; the paper's Stage 1 is a fine-tuned BGE.
This is the kind of default that produces a confusing first run rather than an obvious failure. Nothing errors, the pipeline trains, the numbers come out lower than the paper, and the cause is a model name in a shell script. The override is documented and there is a worked example, but the documentation does not say that the default is not the paper's encoder.
The requirement list reinforces how little is pinned. Six packages are named with no version constraint at all, including the tensor library, the transformer library and the experiment tracker, and five carry a lower bound only. A test runner is in the same list as the runtime dependencies, and the repository does have a tests directory.
The install step itself is one line, with the file that holds those unpinned packages:
pip install -r requirements.txtSo there is no environment to reproduce against, only an environment to start from.
Running without an override gives you a different corpus
Two dataset variants ship, and they are not disjoint. The larger one is described as expanding the original corpus rather than defining a separate collection.
The small variant is the original, named in the title, with 614 sheets and a current workload of 1,453 queries. The large variant has 1,002 sheets and 1,797 queries.
The older workload is retained for provenance: an obsolete 134-query snapshot from the arXiv version is kept under its own filename.
So there are three query counts in play. The paper's own snapshot had 134 queries. The corpus named after the paper now has 1,453. The expanded corpus has 1,797.
The trap is the default. The top-level data files, covering sheets, queries, training pairs and dependency edges, are compatibility copies of the larger corpus. So a script run with no data-directory variable resolves to 1,002 sheets and 1,797 queries, not the 614-sheet set the project is named for.
The documented way to avoid that is a flag or an environment variable pointing at either variant explicitly, and the data section does say to point it at one of the two directories. It does not warn that the default is the other one.
A reproduction that forgets the variable does not crash. It trains on a bigger corpus with eleven times the queries of the paper's snapshot and reports numbers that cannot be compared with the published ones.
No checkpoints, no results, and no licence file
Three things a reproduction needs are absent, and one of them is the kind of absence that matters beyond this project.
The release states that checkpoints and result JSON files are not included. So the model has to be retrained from scratch, both stages, and the reported metrics cannot be checked against anything the repository ships. A separate reproduction guide is referenced for the full sequence, from release validation through both datasets, every comparison method, aggregation across three seeds, sensitivity plots and latency on one accelerator.
The absence of a licence file is the other one. The repository root contains a gitignore, the readme, a requirements file and seven directories, and no licence document. No licence value is declared in the repository metadata either, and nothing here is a guess.
That means there is no stated permission to use, modify or redistribute this code, and the page does not direct you to a licence text anywhere else. For academic reading that is a small problem. For anything else it is a blocker, and it is the kind that is easy to miss because nothing on the page mentions licensing.
The third absence is smaller and expected: cell values, which the release explains rather than apologises for.
Stage 2 only ever sees fifty candidates
The pipeline is described as a fine-tuned retriever over the complete sheet corpus, followed by a gated relational graph network over the retrieved top fifty candidates.
So the second stage is not a second pass over the corpus. It is a reranker over a fixed-width shortlist produced by the first stage, and the graph it operates over is a graph of fifty nodes rather than a thousand.
That has a consequence worth stating plainly: Stage 2's ceiling is Stage 1's recall at fifty. If the correct sheet is not in the shortlist, no amount of relational composition recovers it, and the graph's ability to reason about cross-sheet dependencies cannot help with a sheet it never saw.
It also explains the design of the corpus. The released data includes a dependency-edge file, which is the cross-sheet relationship structure the second stage consumes, and the graph retriever has two variants, a shallower one used as the architecture ablation and a shadow model, and an enhanced one with stronger relational composition used as the full model.
The zero-shot comparison systems make the same shortlist assumption in a different way. One retrieves by cosine similarity over frozen embeddings of every sheet with no training. One asks an OpenAI model to pick sheet identifiers directly from the full catalogue. One runs a local model through Ollama over a controlled candidate set, with an explicit quantised 1.5B model as the default, which is a small model and the release says so rather than implying parity with the hosted one.
All of them report the same metric set: precision, recall, hit rate, mean reciprocal rank and normalised discounted cumulative gain at several cutoffs.
Editorial conclusion
Read it as a paper artefact rather than a drop-in component, since reproducing it means retraining both stages and the numbers in the paper were produced on a different query workload than the one in the public corpus. Three things to establish before you start. The full model trains Stage 1 with column examples that the metadata-only release does not include. The scripts default to a base BERT model while the paper's Stage 1 is a fine-tuned BGE, so an unconfigured run trains something else. And there is no licence file, so the terms are unstated.
Frequently asked questions
What is the Sheet as Token pipeline?
A two-stage retrieval system for multi-sheet spreadsheets. Stage 1 fine-tunes BGE for query-to-sheet retrieval, serializing only the sheet name, dimensions and column headers. Stage 2 is a gated relational graph network that reranks the top 50 candidates Stage 1 returned.
What data does SheetasToken include?
Two metadata-only variants: the original 614-sheet corpus with a 1,453-query workload, and an expanded 1,002-sheet corpus with 1,797 queries. Checked-in sheet files hold identifiers, names, dimensions and column names only, with no cell or example values. An obsolete 134-query snapshot from the arXiv version is retained for provenance.
Which dataset does SheetasToken use by default?
The larger one. The top-level sheets, query, train and dependency-edge files are compatibility copies of the 1,002-sheet corpus, so a script run without a data-directory override resolves to IndustryTab-1K rather than the 614-sheet corpus the project is named for.
Are model checkpoints or result files included in SheetasToken?
No. Checkpoints and result JSON files are not part of the public code release, so reproducing the paper means retraining both stages. A separate reproduction guide covers release validation, both datasets, all comparison methods, three-seed aggregation, sensitivity plots and latency on one accelerator.
What license does SheetasToken use?
None is stated. The repository root has no licence file and no licence value appears in the repository metadata, so there is no stated permission to use, modify or redistribute the code. Check before doing anything beyond reading it.
What are the zero-shot baselines in SheetasToken?
Three no-training systems: cosine retrieval with frozen bge-base embeddings over all sheets, an OpenAI model selecting sheet identifiers directly from the full catalogue, and a local Ollama run over a controlled candidate set with an explicit Q4_K_M 1.5B model as the default. All report precision, recall, hit rate, MRR and nDCG at several cutoffs.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/shitianyu-hue-sheetastoken)Star history chart for your README
[](https://hysenlabs.com/projects/shitianyu-hue-sheetastoken)Was this useful?