EmoLLM's dependency file starts with a git URL, and its setup.py says version 1.0
A mental-health LLM (LLM x Mental Health) covering pre- and post-training, dataset, evaluation, deployment and RAG, with InternLM, Qwen, Baichuan, DeepSeek, Mixtral, LLaMA and GLM series models.
At a glance
- What is it?
- EmoLLM is a family of mental health language models fine-tuned from a dozen base models, published as weights and training configs rather than as an installable library. Its dependency file opens with an unpinned clone of someone else's repository, and its package metadata claims a version the releases have never reached.
- Who is it for?
- EmoLLM is worth a look for a researcher who wants published fine-tuning configs for a mental health dataset across many base models, since that table is the part of the repository with real content in it. It is not a library to depend on: the package metadata has no declared dependencies, the requirements file leads with an unpinned clone, and the demo entry points are a dozen scripts at the root with no documented default.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 150 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
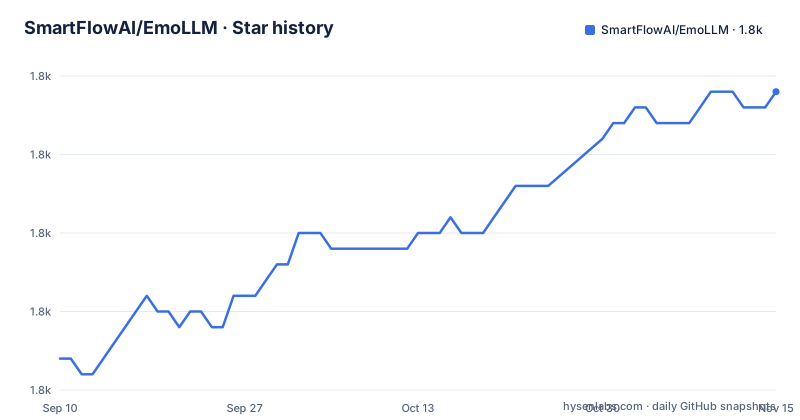
- SmartFlowAI/EmoLLM1,799 ★ · +17
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| SmartFlowAI/EmoLLM | 1.8k | 1.8k |
17 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The dependency file leads with a clone of an unrelated repository
The first line of the dependency list is not a package. It is a clone instruction:
git+https://gitee.com/jujimeizuo/meta-gpt-tianji.git

transformers==4.36.2
streamlit==1.24.0
sentencepiece==0.1.99
accelerate==0.24.1
So any install from this file begins by pulling a third-party project from a code hosting site, at whatever version that repository's default branch is at the time, with no tag or commit pinned. The pinned entries that follow are ordinary, and the unpinned ones include a model hosting client, a tokenizer library, an object storage SDK for a Chinese cloud provider, and a plain HTTP library.
What is missing matters as much as what is there. Neither training framework named in the project's own table appears in the file, so the fine-tuning configs the project is built around cannot be installed from it.
A fixed transformers release sits under a table that spans Mixtral and DeepSeek
The dependency file pins one exact release of the transformers library. The training table, on the other hand, spans base models from InternLM2 and Qwen1.5 through ChatGLM3, Qwen2, LLaMA3, a DeepSeek mixture of experts model and Mixtral 8x7B, and it also includes quantized tuning for a DeepSeek distilled model.
Those are architectures that arrived over a wide span of time, and the pinned release is a single fixed point from earlier in that span. Nothing in the repository records which library version was used to produce the published weights, so a reader has two numbers that do not obviously belong to the same experiment.
There is a second oddity in the same file. A streaming helper for text generation is pinned to a four-patch release, and the same file also names a model hosting client and a cloud storage SDK. Those are deployment and distribution dependencies, sitting in a list that otherwise describes a training and demo stack.
Row one names a DeepSeek model, links an artifact called qwen, and cites a different framework
The first row of the fine-tuning table is for a quantized distilled DeepSeek model, and it differs from every other row in three separate ways.
The framework column reads unsloth, while every other row links a training config file under a configuration directory in the repository. The artifact link points at a model whose published name contains qwen and a quantization marker rather than the DeepSeek name in the row. And no DeepSeek entry elsewhere in the table carries a framework name instead of a config file.
A reader trying to reproduce that particular checkpoint cannot tell from the table which framework was used, and the artifact name suggests a different base model family than the row label. The same repository lists a separate project as the source of a deep thinking assistant, and the artifact name in this row matches that project's naming style, so the row may be pointing at a derivative rather than at a config the project ships.
One InternLM2 7B row links a config file named for a different model
The table covers roughly seventeen rows, and several base models appear twice because both full fine-tuning and quantized tuning are provided for them. A 7B InternLM2 chat model appears as a quantized row and as a full row. The same base model at 5B appears as both. LLaMA3 at 8B appears twice as well, with two different quantized config files.
The full fine-tuning row for the 7B chat model links a file whose name drops a digit from the model it labels, reading as a 7B config without the version marker used everywhere else in the table. Next to it, the quantized row for the same model links a file that keeps the naming consistent. So one row points at a file that does not match its own label, and the error is only visible by reading the file name.
Five rows carry no artifact link at all, including the 20B chat model, a 7B Qwen chat model, a 13B Baichuan model, a 6B ChatGLM model and a DeepSeek mixture of experts model. The table closes with an ellipsis row, so it is explicitly open-ended rather than complete.
Config file names encode datasets and hyper-parameters with no legend
The config file names are where the actual experimental choices live, and they follow a convention nobody wrote down. Suffixes appear to carry a dataset name, with names corresponding to an assistant dialogue corpus and to a self-instruct style corpus, followed by tokens that look like epoch counts, a letter that could be a weight or merge setting, a word that could be a sampling variant, and in one case a triple that reads like a learning rate with two more numbers attached.
The 7B base model's quantized config ends in a run of numbers that reads like a learning rate of one times ten to the minus four followed by two batch-like values. Nobody reading the table can tell whether the epoch token means three epochs or version three of the data, and nothing in the repository resolves it.
This is the single most useful thing in the repository and also the least documented. A config file is reproducible once you have it; the naming that would let someone choose the right one is not. The names also show the same base model tuned on different corpora, which is the closest thing to an ablation study the project publishes.
Twelve runnable scripts at the root, and no named entry point
The root of the repository is a list of launchers. There is a plain application script, two Gradio scripts for one model where the second is a numbered variant, a web demo for a Llama3 model, two more Llama3 demos with different prefixes, a demo attributed to a contributor, and two web demos for two different generations of the InternLM2 model. Eight in total, at the root, with no index and no default.
Underneath them the layout is organised by pipeline stage rather than by feature: separate directories for data generation, evaluation, retrieval augmentation, deployment, quick start, a front end, a back end, a scripts directory, a datasets directory, an assets directory, a documentation directory, and two separate directories for training configurations from two different frameworks. A model download script sits at the root too, and a second dependency list file sits beside the main one.
The demonstration subdirectory is better organised than the root, with its own README in two languages, four command line scripts, a web script, and a separate dependency file for one model. That directory is the only place in the repository where a newcomer is told what to run.
The package claims version 1.0 and declares no dependencies at all
The setup script is six lines long:
setup(
    name="emollm",
    version="1.0",
    packages=find_packages(exclude=["build", "dist"]),
)
The version is 1.0. The tagged releases are 0.6, 0.5 and 0.4, and the 0.6 tag is dated May 2025 while the last push to the branch is dated 2026-06-18. So the package metadata is a version ahead of every published tag, and the code has been moving for more than a year since the last release.
There is also no install_requires line, no Python version requirement, and no long description, so an install from the package index would fetch a set of discovered packages and nothing else. The project is distributed as weights and configuration files on model hosting platforms rather than as a library, which is the right call for this kind of work, but the version string is then doing no useful job.
The documentation's own update list stops at May 2025, and one of those entries notes that instructions for using a quantized format would be added later.
Editorial conclusion
EmoLLM is worth a look for a researcher who wants published fine-tuning configs for a mental health dataset across many base models, since that table is the part of the repository with real content in it. It is not a library to depend on: the package metadata has no declared dependencies, the requirements file leads with an unpinned clone, and the demo entry points are a dozen scripts at the root with no documented default. Before using anything here, check four things. Read the training config whose filename matches your base model, because one row's file name does not match its own label. Reproduce the environment yourself, because neither training framework named in the table is installable from the dependency file. Confirm which release you are working from, because the package version and the tag history disagree. And treat the recent updates list as history rather than as current state, because its newest entry predates the last push by about a year.
Frequently asked questions
What is EmoLLM?
EmoLLM is a series of mental health language models, fine-tuned from existing base models to follow a chain of understanding a user, supporting them and helping them. The repository ships fine-tuning configurations and model artifacts rather than a library, and the setup script declares no dependencies.
Which base models has EmoLLM been fine-tuned from?
The table covers InternLM2 at 1.8B, 7B, 7B base and 20B, Qwen1.5 at 0.5B, a Qwen chat model at 7B, Qwen2 at 7B, Baichuan2 at 13B, ChatGLM3 at 6B, a DeepSeek mixture of experts model at 16B, Mixtral 8x7B, LLaMA3 at 8B and a quantized distilled DeepSeek model. Some rows provide both full and quantized tuning.
How do I install the dependencies for EmoLLM?
The dependency file is short and its first line is a clone instruction for a third-party repository rather than a package. It pins a specific transformers release, a Streamlit release, sentencepiece and accelerate, and leaves the model hosting client, tokenizer, object storage SDK and HTTP client unpinned. Neither training framework named in the table is listed.
Which version of EmoLLM is the current one?
The package setup script declares version 1.0, while the tagged releases are 0.6, 0.5 and 0.4, the newest dated May 2025. The last push to the default branch is dated 2026-06-18, so the branch has moved well past the newest tag.
Does EmoLLM include retrieval augmentation and web search?
The repository has a retrieval augmentation directory and a separate project for a deep thinking psychological assistant that is described as having completed deep thinking, retrieval, web search and text to speech, and as having been merged into EmoLLM. The update list's newest entry is dated May 2025.
Where do I run an EmoLLM demo?
The root carries about eight launch scripts, including Gradio scripts and web demos for two generations of one base model, with no documented default. The demonstration subdirectory is the organised one, with its own README in two languages, four command line scripts, a web script and a separate dependency file for one model.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/smartflowai-emollm)Star history chart for your README
[](https://hysenlabs.com/projects/smartflowai-emollm)Was this useful?