datalinkx ships with no access control, and the enterprise edition sells you that first
DatalinkX is a data-synchronization system between heterogeneous data sources, supporting incremental or full sync at scale. It moves data between HTTP, Oracle, MySQL, Elasticsearch, and other sources, with built-in transform operators such as SQL and LLM operators, running on the Flink and SeaTunnel engines. Includes sync-task management, cascading task configuration, and task log collection.
At a glance
- What is it?
- A Java data synchronisation service built on two vendored sync frameworks and three engines, with batch, Kafka-only streaming and canvas compute task types, task cascading and data lineage. The usage notes say the default login is admin over admin with no permission checks at all.
- Who is it for?
- Use datalinkx if you need to move data between heterogeneous stores across departmental boundaries, want one place to manage the sync jobs and read their logs, and can live with Kafka being the only streaming source. Do not expose it to anyone but yourself until you have added access control, because the documentation is explicit that the default installation has none.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 139 days ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
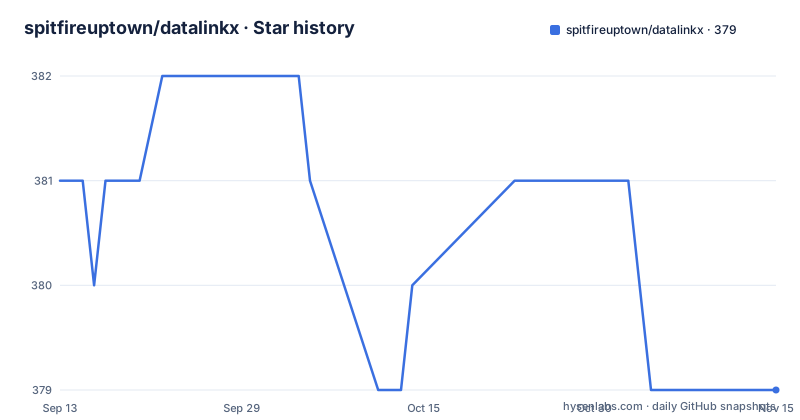
- spitfireuptown/datalinkx379 ★ · -2
| Repository | 2026-09-13 | 2026-11-15 |
|---|---|---|
| spitfireuptown/datalinkx | 381 | 379 |
-2 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The default installation has no access control, and it says so
The first item in the usage notes is the one to read twice.
Log in with the default password, which is admin, and there is no permission related control.
That is not an oversight in the documentation, it is the first thing the documentation tells you. And the reason becomes obvious one paragraph further up, where the enterprise edition's feature list leads with a more complete user and permission system.
So the open edition is positioned as the edition without authorisation, and the commercial edition's first listed feature is the thing the open one lacks. That is an unusually honest commercial framing and also a serious operational one, because the default credentials are published in the project readme.
The rest of the usage flow follows a normal order: configure the data sources, then manage tasks, then set up cascading between them, then look at lineage, then scheduling, then execution.
Two details in that flow are worth noting. Task cascading means one task triggering another, which is what turns a list of jobs into a pipeline. And lineage is listed as a feature, which is the capability that tells you where a piece of data came from and what depends on it. Both are features you would normally expect from a scheduler rather than from a sync service, which tells you where this project's ambition sits.
Two entire sync frameworks are vendored into the repository
The top level of the repository contains two directories that are not modules of this project at all: one holding an Apache data synchronisation framework at a specific version, and one holding the earlier framework it was renamed from.
That is the single most consequential structural fact here. This is not a sync service that depends on two sync engines through a package manager. It carries the source of both.
The version table explains why. It lists the renamed framework at a 1.10 release line, described as an open source sync framework from a Chinese cloud vendor, and the Apache one at 2.3.8. So the project uses both, and both are present in the tree rather than resolved from a registry.
Vendoring two data engines has consequences that are easy to state and hard to avoid. You can patch either without forking anything, which is the reason people do it. You also inherit both codebases' maintenance burden, their build requirements, and their licence obligations. And the repository gets large enough that a reader has to work out which directories are the project and which are dependencies.
The module list around them is a normal Java multi-module layout: a common module, a connector module, a server module, a job module, a message hub module, an interface client module, a server-sent-events module, and one named for a copilot. That last one is not in the version table at all, and it is the module that backs the large model operators.
Real time tasks support exactly one source, and it is Kafka
The task types are described as three, and the limitation on the second one is stated without hedging.
Batch tasks: configure the source and target databases and the system constructs the execution graph.
Real time tasks: configure the source and target databases and the system constructs the execution graph, and this only supports Kafka.
Compute tasks: configure a canvas and operate transform operators on it.
So streaming is supported, but it is supported in exactly one direction of implementation. That is a much narrower claim than a feature list saying real time synchronisation, and it is the kind of limitation you want to read before designing around it rather than after.
The compute task type is the most interesting of the three and the least described. A canvas with transform operators means the transformation is a thing you draw rather than a query you write, and the operator list includes both a SQL operator and a large model operator.
A large model operator on a sync canvas is a real design decision rather than a feature to be proud of. It means a model can sit in the middle of a data flow, which is a different architecture from calling a model at the edge. It also means the pipeline's cost and latency depend on a model call, and its output is non-deterministic, which is a new category of problem for something that otherwise looks like an ETL scheduler.
The version table is a document about what you are inheriting
The stack table is unusually explicit, with a version and a role for every component, and reading it as a whole tells you what kind of deployment this is.
The application layer is a Spring Boot line from 2022 with Spring Data JPA at a matching version, MySQL 8 as the database, and Redis 5 or newer doing double duty as a cache and as the message middleware through its stream feature. An Elasticsearch 7.9 release is listed as the vector store and as a supported flow target.
Then the engines: the renamed framework at a 1.10 line, the Apache one at 2.3.8, and a streaming compute engine pinned to 1.10.3.
That last number is the one to look at. A streaming engine at 1.10 predates most of the ecosystem's current work, and pairing it with a Spring Boot line from 2022 and an Elasticsearch 7 series tells you this is a codebase assembled over a period of years and still running.
The rest of the table is the usual mixture. A distributed scheduler at 2.3.0 for cron triggers, an interface client library for service to service calls, a JSON library, Maven, a second-generation Vue with a matching component library, and Docker.
Two entries are worth calling out because they map to features rather than infrastructure. A local model runtime framework, which is how the large model operators execute without a hosted service. And a framework labelled as being for the model context protocol, which suggests the copilot module speaks to tools rather than only to a chat endpoint.
Extending the source list means writing a driver into a distribution directory
The plugin model is described in one line and it tells you exactly where the extension boundary sits.
Custom data sources are supported. Develop a driver following fixed rules and put it into the driver distribution directory, and it can be used.
So the extension mechanism is a directory convention rather than a registry, an interface discovery mechanism, or a marketplace. The driver is loaded from a distribution folder at runtime, which means adding a data source is a deployment action rather than a configuration action.
That has a real operational consequence: adding an Oracle source, which the project description mentions among its supported sources, is a build or deploy step rather than something a user can do from the web interface. In a team where the person who can write a driver is not the person who needs the source, that is a ticket, not a click.
The other features in the list describe the opposite end of the spectrum, where the common path is deliberately simple. Data sources and sync tasks are created through a web page with a stated time to first task. Database information and task detail are configured through the interface rather than in files. Scheduling is a cron expression against a distributed scheduler. And deployment is containerised.
So the project is opinionated in one direction: nothing a normal operator does should require a terminal.
Ninety two documents live on a note service, not in the repository
The documentation situation is unusual enough to be worth describing precisely.
The repository readme links to a document set described as over one hundred thousand characters across ninety two documents, hosted on a shared note page. The enterprise edition link at the top of the readme is also a note page on the same service.
So neither the documentation nor the commercial offering is hosted where a repository visitor would look, and both are on a service that is not version controlled, not searchable by the project's own tooling, and not preserved if the author decides to move it.
That matters more for this project than for most, because the project has a large surface. Three task types, two vendored engines, a scheduled execution model, a canvas editor, a plugin driver contract, a permission model that the open edition lacks, and data lineage. Ninety two documents is a proportionate response to that surface, and having them somewhere reachable is the right call.
There is a mirror situation too, which cuts the other way. The project is mirrored on three separate code hosting services, which is genuinely good for reach in a region where the primary host is slow. The cost is that the three mirrors can drift, and nothing in the readme says which one is authoritative.
The usage steps are numbered 3, 5, 6, 6, 7
The step list has a small error that is worth noting only because it is the kind of thing that tells you how the document is maintained.
The numbering goes one, two, three, then three sub steps, then five, then six, then six again, then seven. The four is missing and the six is duplicated.
The content under those numbers is coherent and the sequence makes sense: log in, configure sources, manage tasks with their three types, then cascading, lineage, scheduling and execution. So this is a formatting artefact rather than a missing feature.
What it does tell you is that the readme is assembled rather than generated, and that the feature list above it is maintained separately from the walkthrough below it. The two lists also do not match exactly: the feature list leads with ease of use, scheduling, configuration, performance, plugins and containers, while the walkthrough leads with permissions, sources, tasks, cascading, lineage, scheduling and execution.
Lineage appears only in the walkthrough. Containerised deployment appears only in the feature list. That asymmetry is the more useful observation than the numbering, because it tells you the two sections were written for different audiences.
Editorial conclusion
Use datalinkx if you need to move data between heterogeneous stores across departmental boundaries, want one place to manage the sync jobs and read their logs, and can live with Kafka being the only streaming source. Do not expose it to anyone but yourself until you have added access control, because the documentation is explicit that the default installation has none. Four things to check before you deploy it. That you are running a version stack where several components are several years old, including a 2020 era streaming engine and a Spring Boot line from 2022, and decide whether that is acceptable in your environment. Where the documentation actually lives, since ninety two documents are hosted on a note service rather than in the repository. Which streaming source you need, because real time tasks only support Kafka. And how you will extend the source list, since the documented route is writing a driver and dropping it into a distribution directory. Licence reads as unasserted in the repository metadata, there are no GitHub releases, and the last push to main is dated 29 June 2026.
Frequently asked questions
What is spitfireuptown/datalinkx?
It is a Java data synchronisation service for heterogeneous data sources, supporting incremental or full synchronisation of large volumes between sources such as HTTP, Oracle, MySQL and Elasticsearch. It provides central management of sync tasks, task cascading configuration, task lineage and log collection, built on Flink and SeaTunnel style sync engines.
Does datalinkx have user authentication and permissions?
The usage notes state that you log in with the default password admin and that there is no permission related control. A more complete user and permission system is the first feature listed for the separate commercial edition. The readme publishes the default credentials, so any deployment should be treated as single user until access control is added.
What kinds of sync task does datalinkx support?
Three. Batch tasks, where you configure a source and target database and a job graph is constructed. Real time tasks, configured the same way, which only support Kafka. And compute tasks, where you configure a canvas and operate transform operators, which include a SQL operator and a large model operator.
How do I add a new data source to datalinkx?
By writing a driver that follows the project's fixed rules and placing it into the driver distribution directory, where it will be loaded. The documented mechanism is a directory convention rather than a registry, so adding a source is a build or deployment step rather than something done from the web interface.
What versions does the datalinkx stack use?
Spring Boot 2.7.15 with Spring Data JPA at the same version, MySQL 8, Elasticsearch 7.9.3, Redis 5 or newer for both caching and its stream message feature, a sync framework at a 1.10 release line alongside Apache SeaTunnel 2.3.8, Flink 1.10.3, a distributed scheduler at 2.3.0, Vue 2 with a matching component library, and a second-generation Vue-based interface.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/spitfireuptown-datalinkx)Star history chart for your README
[](https://hysenlabs.com/projects/spitfireuptown-datalinkx)Was this useful?