ml-engineering is a book built from chapters-md.txt, and make spell edits your files
Machine Learning Engineering Open Book
At a glance
- What is it?
- The Machine Learning Engineering Open Book collects one engineer's notes from training BLOOM-176B, IDEFICS-80B and production RAG models, and it is published as a seven part book with PDF and EPUB downloads. The mechanics of the repository are as instructive as the content: the chapter order comes from a text file, the default HTML build repoints your links upstream, the spell target rewrites your working tree, and the licence is CC-BY-SA over a repository of copy-paste commands.
- Who is it for?
- ml-engineering fits an engineer who already trains large models and wants the operational layer: how to pick a cluster, how to decide on a GPU generation, how to test inter-node connectivity, and what to do when a PyTorch job hangs. It does not fit a reader looking for a curriculum, since the author describes it as an ongoing brain dump compiled mostly for himself, nor a team that wants to lift its scripts into a closed-source repository without reading the licence.
- Can I use it commercially?
- Yes, with credit. CC-BY-SA-4.0 allows commercial use as long as you credit the authors and indicate what you changed. It is written for creative content, so check how it applies to any code.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
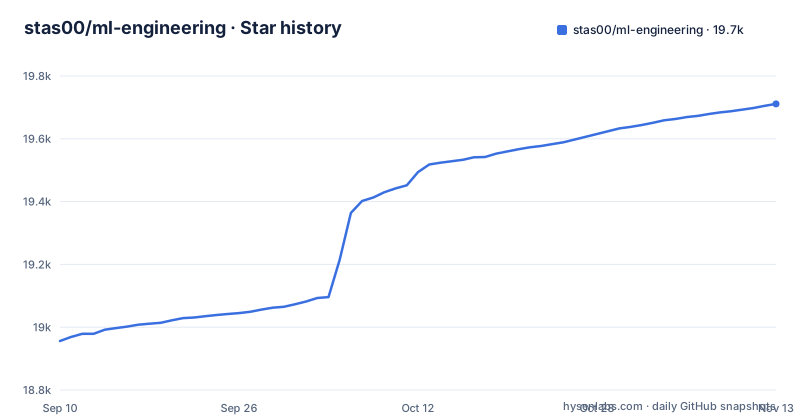
- stas00/ml-engineering19,711 ★ · +755
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| stas00/ml-engineering | 19k | 19.7k |
755 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The book's order is chapters-md.txt, and two directories are not in it
The order of the built book comes from a plain text file at the repository root called `chapters-md.txt`. The build target that consumes it is `prep-html-files`, and the whole of it is two lines:
echo book-front.html > chapters-html.txt
perl -ne 's|\.md|.html|; print' chapters-md.txt >> chapters-html.txt
That reads the file in order, swaps each `.md` for `.html`, and writes the resulting list. The PDF target then concatenates exactly that list, `$(cat chapters-html.txt | tr "\n" " ")`, passed to the HTML to PDF engine. So a chapter's position in the book, and whether it appears at all, is decided by one line of text in one file.
The consequence is worth internalising before you read the book: a directory can exist, hold good markdown, and still be absent from every built format. Two top level directories, `model-parallelism/` and `stabs/`, are not mentioned in the README table of contents.
There is also a `todo.md` at the root, which is the author's own task list, and `contributors.md`. The repository is a working notebook with a build system attached, not a curated volume.
make html repoints your links upstream, so a fork needs html-local
There are two HTML targets and the difference is one flag. The comments on the targets say it plainly: `html` is the make html version with scripts linking to their url at the author's GitHub repo, and `html-local` is the make html version with scripts remaining local.
Both run the same script:
python build/mdbook/md-to-html.py --localThe transformation is not cosmetic. The book's chapters link to the scripts they describe, and the default target rewrites those links to point at the upstream repository, which is correct for the canonical copy and wrong for everyone else. In a fork, or in a mirror, running `make html` gives you a book whose download links point at somebody else's copy, and the failure is invisible because the build succeeds and the pages render.
The default goal is `help`, not `html`, and the help target is a small awk script that lists every target whose line ends in `##` with its comment text. That is a deliberate choice for a repository with this many build paths: the entry point prints the menu rather than starting a build, so the first thing a contributor does is read the list of what is available.
The PDF needs Prince and pdftk, and the pipeline reorders pages twice
The `pdf` target depends on `html` and then runs a commercial HTML to PDF engine with a style sheet:
prince --no-author-style -s build/prince_style.css --pdf-title="Stas Bekman - Machine Learning Engineering ($$(date))" -o out1.pdf $$(cat chapters-html.txt | tr "\n" " ")Two things to note in that line. The PDF title embeds `$(date)`, so two builds on different days are not byte-identical, and the list of input files is the generated chapter order, not a glob. And the tool is Prince, which is a separate commercial install, not a Python package.
The rest of the target is four pdftk invocations. The first dumps the data to a bookmarks file. The second is `pdftk out1.pdf cat 2-end 1 output out2.pdf`, which reorders the pages by taking page one to the end. The third prepends the cover, `images/Machine-Learning-Engineering-book-cover.pdf`. The fourth writes the final file with the bookmarks applied.
So the PDF is not a single conversion. It is a page-reordering and cover-assembly pipeline built on two binaries that a Python developer may not have, which is why the README says the ebook files are rebuilt occasionally and points you at the `build` directory for the current instructions.
make spell rewrites your working tree instead of reporting
This is the target most likely to surprise someone. It is called `spell`, described in its comment as spellcheck, and it is:
codespell --write-changes --skip "*.pdf" --skip "*.json"`--write-changes` is the whole issue. A target named spellcheck, which most people would expect to be read-only, edits every file it scans. Run it on a branch with work in progress and your diff is now a mix of your change and a repository-wide spelling correction, and the two are indistinguishable in a review.
The skips are also worth reading. PDFs and JSON files are excluded, which in a book repository means the generated artefacts are left alone, and everything else is fair game.
The rest of the target list describes the maintenance side of a large document: `check-links-local`, `check-links-all`, `check-links-local-fast`, `check-redirects` and `check-programs`, plus `fix-tables`. Four separate link checking targets is what a repository with hundreds of cross-references and a generated site needs, and `fix-tables` is the acknowledgement that markdown tables do not survive the HTML conversion without help.
Three runnable scripts, each positioned against something heavier
The most immediately useful part of the repository is three Python files, and the README describes each one by the thing it replaces. `network/benchmarks/torch-dist-bench.py` (formerly `all_reduce_bench.py`) is called a much easier way to benchmark network throughput than nccl-tests. `debug/torch-distributed-gpu-test.py` is a tool to quickly test your inter-node connectivity. `compute/accelerator/benchmarks/mamf-finder.py` answers a narrower question: what is the actual TFLOPS measurement you can get from your accelerator.
That framing is the point. Two of the three are positioned against a specific incumbent, nccl-tests for collective throughput and a manual connectivity check for multi-node setups, and the third is positioned against the vendor number. A book that only restated specifications would be useless; a script that prints what your cluster actually does is not.
The guide side has the same character. `debug/pytorch.md` is described as quick copy-n-paste solutions to resolve hanging or breaking PyTorch applications, and it includes an anchor for faster debug and development with tiny models, datasets and tokenizers. `orchestration/slurm/users.md` is a SLURM cheatsheet and tricks, and `resources/README.md` holds a collection of publicly available training LLM and VLM logbooks.
The repository's primary language is Python because these are the parts that run, not because the prose is code.
The tables are theoretical, and the scripts exist to contradict them
Four comparison tables are promoted under Key comparison tables, and they are split across two README files. In `compute/accelerator/README.md` there is a theoretical accelerator TFLOPS table and an accelerator memory size and speed table. In `network/README.md` there are theoretical inter-node speed and theoretical intra-node speed tables.
The word theoretical is doing the work in all four. A TFLOPS figure is a datasheet number, a memory speed is a chip characteristic, and a network speed is a link rate. None of them tell you what a job achieves.
That is why `mamf-finder.py` and `torch-dist-bench.py` sit in the same repository. The accelerator table gives you the ceiling and the script tells you the fraction of it you get, and the network table gives you the link rate while the benchmark tells you the collective throughput. A reader who stops at the tables will overestimate their cluster by exactly the amount the scripts are there to measure.
Part 1 of the book frames the rest around decisions rather than specifications. It opens with the AI Battlefield Engineering, described as what you need to know in order to succeed, adds a piece on how to choose a cloud provider, and then a framework for deciding whether a GPU generation upgrade is worth its cost, worked through on a real H200 to B200 benchmark.
The GPU upgrade case is one H200 to B200 benchmark
The When Is It Worth Upgrading GPUs? page is the most concrete decision document in the repository, and its evidence base is a single worked example. The README describes it as a practical framework for deciding whether a GPU generation upgrade is worth its cost, worked through on a real H200 to B200 benchmark.
One benchmark is not a survey, and the author is explicit about why the material exists. The gratitude section says none of this would have been possible without being entrusted with doing the specific LLM and VLM trainings the initial know-how came from, and calls it a privilege only a few enjoy because of the prohibitively expensive cost of renting huge ML compute clusters. The intended reader is therefore someone who has the same access problem, not someone shopping for a laptop.
The provenance is listed too: the know-how comes from training BLOOM-176B in 2022, IDEFICS-80B in 2023, and RAG models at Contextual.AI in 2024, with special thanks to Thom Wolf for proposing that the author lead the BLOOM-176B training when they did not know anything about large scale training.
So the correct way to read the book is as one engineer's operational record. The author describes it as an ongoing brain dump compiled mostly so he could find solutions he had already researched, which is both its strength and its limit.
CC-BY-SA over a repository of copy-paste commands, plus two agent skills
The licence file at the root is named `LICENSE-CC-BY-SA`, and the identifier is CC-BY-SA-4.0. The content the licence covers is a book whose stated purpose includes lots of scripts and copy-n-paste commands to enable you to quickly address your needs.
That combination is worth pausing on. A share-alike licence is a natural fit for prose, and an author asking readers to copy commands out of a book is being generous rather than restrictive. But the scripts are the artefacts you are most likely to paste into a codebase you own, and they arrive under the same share-alike terms as the text around them. Before lifting one of these scripts into a repository with a different licence, read the licence file and check with whoever owns that decision; do not infer the terms from the fact that the code is freely published.
Two other things in the repository are newer than a book. There is a `SKILL.md` at the root and a `skills/` directory holding two of them, one for training and operating large-scale ML models and one for evaluating a GPU cluster through a trial-node and acceptance loop covering compute, network and storage, ending in a markdown report, with companion skills in the author's other repositories. And the ebook PDFs and EPUBs are hosted on the HuggingFace hub, rebuilt on an ad hoc schedule, with the build instructions in the `build` directory for anyone who needs the current version.
Editorial conclusion
ml-engineering fits an engineer who already trains large models and wants the operational layer: how to pick a cluster, how to decide on a GPU generation, how to test inter-node connectivity, and what to do when a PyTorch job hangs. It does not fit a reader looking for a curriculum, since the author describes it as an ongoing brain dump compiled mostly for himself, nor a team that wants to lift its scripts into a closed-source repository without reading the licence. Before adopting, check three things: whether the chapter you need is listed in `chapters-md.txt`, since that file drives the HTML, PDF and EPUB builds, that you use `make html-local` rather than `make html` in a fork, because the default target rewrites script links to the author's repository, and whether `make spell` is safe to run, because `codespell` is invoked with `--write-changes` and edits the files it checks.
Frequently asked questions
What is the Machine Learning Engineering Open Book?
It is an open collection of methodologies, tools and step by step instructions for training and fine-tuning large language models and multi-modal models and running their inference, written by one engineer from training BLOOM-176B in 2022, IDEFICS-80B in 2023, and RAG models at Contextual.AI in 2024. The README calls it an ongoing brain dump compiled mostly for the author himself.
What licence is the ml-engineering repository under?
CC-BY-SA-4.0, with the licence file at the root named LICENSE-CC-BY-SA. The content includes scripts and copy-n-paste commands, so anyone lifting a script into a differently licensed codebase should read the licence file rather than assume the code carries separate terms.
Does ml-engineering come as a PDF or EPUB?
Yes, both are hosted on the HuggingFace hub, with direct download links given in the README for PDF and EPUB. The author says they will try to rebuild them once in a few weeks, and points to the build directory for the current instructions if you want the latest versions.
Can I use ml-engineering to benchmark my own GPU cluster?
The repository ships three runnable scripts for measurement. torch-dist-bench.py (formerly all_reduce_bench.py) benchmarks network throughput, described as an easier alternative to nccl-tests, torch-distributed-gpu-test.py tests inter-node connectivity, and mamf-finder.py reports the actual TFLOPS your accelerator achieves. The comparison tables the README highlights are theoretical.
How do I build the ml-engineering book locally?
Use `make help` to list the targets, since the default goal is help rather than a build. The HTML step runs python build/mdbook/md-to-html.py, and the --local flag keeps script links pointing at your copy instead of the author's repository, which matters in a fork. The PDF and EPUB steps additionally need Prince, pdftk and pandoc.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/stas00-ml-engineering)Star history chart for your README
[](https://hysenlabs.com/projects/stas00-ml-engineering)Was this useful?