ColorFlow colourises a sequence by retrieving, not by finetuning
Official implementation of the paper "ColorFlow: Retrieval-Augmented Image Sequence Colorization."
At a glance
- What is it?
- The official inference code for a three-stage diffusion pipeline built for colouring comic and cartoon sequences while keeping character identity. Weights are on Hugging Face, training code is not released, and the Python environment is pinned to torch 2.0.0 on Python 3.8.5.
- Who is it for?
- Adopt ColorFlow if you are colouring a black-and-white sequence where the same character must keep the same colours across panels, and you have a GPU and patience for a Gradio interface. Do not adopt it expecting to retrain it, since the repository's own checklist still has training code unreleased and there are no tagged releases.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 92 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
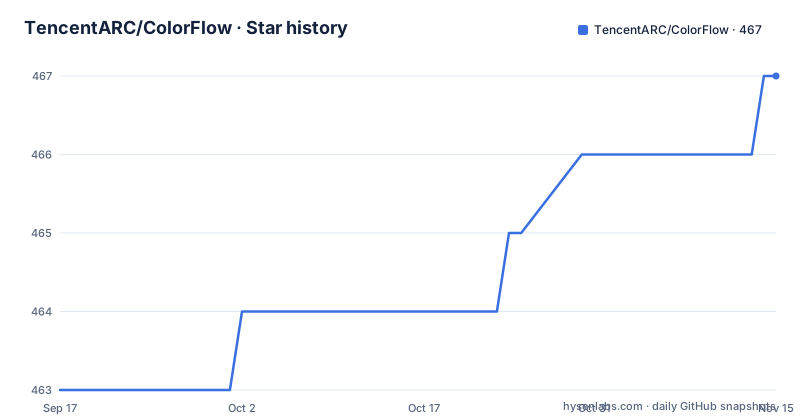
- TencentARC/ColorFlow467 ★ · +4
| Repository | 2026-09-17 | 2026-11-15 |
|---|---|---|
| TencentARC/ColorFlow | 463 | 467 |
4 Stars in the last 59 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The TODO list still has training code unchecked
The repository is an inference release, and it says so in two places.
The news section records that the inference code and model weights were released on 17 December 2024, followed on 23 December by the weights for a separate Sketch_Shading model along with code and demo updates. The TODO list underneath has two items: releasing the inference code and weights, marked done, and releasing the training code, still unchecked.
So what is available is a way to run the model, not a way to reproduce or adapt it. The weights themselves live in a Hugging Face model repository, and an interactive demo is published as a Hugging Face Space.
There are no GitHub releases either, so nothing is distributed as a versioned artefact. The last push to the default branch was on 2026-08-15, well after the 2024 release, which means the branch has moved without any tag telling you which state you have.
For a research implementation that is normal. For anything you plan to run in a pipeline, it means you are tracking a branch, and the differences between commits are yours to discover.
Three pipelines, not one model
The method section names three components, and each is a stage rather than a module inside a single network: a Retrieval-Augmented Pipeline, an In-context Colorization Pipeline, and a Guided Super-Resolution Pipeline.
The stated purpose of the three together is maintaining the colour identity of instances across black-and-white image sequences while producing a high-quality result. That decomposition is the practical answer to the problem the paper describes, where controllability and identity consistency remain unsolved for generative colourisation even with large diffusion models.
The architecture adds a second idea on top of the three stages. The pipeline is dual-branch: one branch extracts colour identity, the other performs the colourisation, and both are diffusion models doing what diffusion models are good at.
What joins them is self-attention. The paper credits the self-attention mechanism in diffusion models with providing in-context learning and colour identity matching, which is the mechanism by which a panel can find its own reference rather than relying on an externally supplied identifier for every object.
That last point is what makes the retrieval framing a method rather than a lookup table: the colour reference has to be located in the image context itself, and attention is doing the locating.
Retrieval replaces per-ID finetuning
The problem framing is about industrial use rather than benchmark scores. Automatic black-and-white image sequence colourisation while preserving character and object identity is described as complex with real market demand, with comic and cartoon series colourisation given as the example.
The criticism of existing work is specific about what breaks. Controllability and identity consistency remain unsolved problems with large generative models such as diffusion models, which makes current solutions unsuitable for industrial application.
The approach taken against that is a contrast with how prior methods handle identity. Existing methods require per-ID finetuning, or they require explicit ID embedding extraction. Both impose a cost: the first means a training run per character, the second means a preprocessing stage that has to know which object is which in every panel.
The retrieval-augmented pipeline is offered instead. Colour the image with relevant colour references rather than with a learned per-object parameter or an extracted embedding. For a long sequence that is a large difference in operational terms, because the references can be picked from panels already coloured rather than produced by a separate stage.
A benchmark, ColorFlow-Bench, was introduced for reference-based colourisation to evaluate it.
A vendored diffusers on a torch 2.0.0 pin
The requirements file is short and completely pinned, and the first line is the one that changes how you install this.
The first entry is an editable install of a local directory, `./diffusers`. That is not a PyPI package reference; it means the repository carries its own checkout of the diffusers library and installs it in place. Anyone who has tried to use a newer diffusers with an older model implementation knows why a project does that.
Everything else is pinned to exact versions, and they are old ones: torch 2.0.0 with torchvision 0.15.1, transformers 4.46.3, accelerate 1.0.1, and datasets 3.1.0. The rest is the usual inference stack, including gradio 4.44.1 for the interface, opencv-python 4.9.0.80, Pillow 9.5.0, peft 0.13.2, safetensors, sentencepiece, webdataset and huggingface-hub.
The environment instructions match. You are asked to create a conda environment named `colorflow` with Python 3.8.5 specifically, activate it, and install from that file.
A vendored dependency plus a two-year-old torch plus a Python version below 3.10 is a stack you install as given. Upgrading any single piece is research work, not maintenance.
One small sign of how the repository is curated: a `.DS_Store` file is committed at the root.
The application is one Gradio file on port 7860
Running it locally is four steps. Clone the repository and change into the directory, create and activate the conda environment, install the requirements, then launch:
python app.pyThat last command starts a Gradio interface, and the README names the default address as `http://localhost:7860`, the standard Gradio port. The remote case is handled in one sentence: if the app is on a server, replace `localhost` with the server's IP address or domain name.
Customisation is one parameter. To use a different port you change the `server_port` argument in the `demo.launch()` call inside `app.py`.
That is the whole interface, and it tells you what kind of project this is. There is no batch script, no command line for a folder of images, and no documented way to run it headless. The supported path is a browser talking to a local Gradio server.
The code itself sits in three directories beyond the application file: `colorflow_utils/` for the helpers, `assets/` for the bundled material, and `BidirectionalTranslation/`, which is a separate included project rather than part of the colourisation path.
The licence is a file reference, not a name
The README does not name a licence. The licence section consists of a pointer to the licence file in the repository root, and GitHub records no licence identifier for the project.
That matters more than usual here, because the repository ships model weights separately on Hugging Face under the same organisation. Anyone planning to use this in a commercial colourisation workflow needs to read both the repository licence file and the weight repository's terms rather than assume they match.
The acknowledgment section credits two open source projects instead: ScreenStyle and MangaLineExtraction_PyTorch, described as having inspired and contributed to the development of ColorFlow. The second is a line extraction project, which fits a comic colourisation pipeline where separating line art from tone is a real step.
The citation block is a BibTeX entry for the paper, listing the seven authors and the arXiv identifier, so anyone writing about the method has a reference to follow.
For contact, the README gives one name, Junhao Zhuang, and a Tsinghua email address. A single named contact on a research release is normal, and it is also the only route to asking about the training code that has not been released.
Editorial conclusion
Adopt ColorFlow if you are colouring a black-and-white sequence where the same character must keep the same colours across panels, and you have a GPU and patience for a Gradio interface. Do not adopt it expecting to retrain it, since the repository's own checklist still has training code unreleased and there are no tagged releases. Verify two things first. Read the licence file yourself, because the repository records no licence identifier and the README only points at a file. Then check your PyTorch version, since the environment is pinned to torch 2.0.0 on Python 3.8.5 with a vendored copy of diffusers that will fight a newer stack.
Frequently asked questions
What is ColorFlow?
The official implementation of the paper ColorFlow: Retrieval-Augmented Image Sequence Colorization, from TencentARC. It colourises black-and-white image sequences with a three-stage diffusion pipeline, built for cases such as comic series where character identity must be preserved across panels.
Is ColorFlow's training code available?
No. The repository's own checklist marks the release of inference code and model weights as done and the release of training code as still outstanding. Inference code and weights were released in December 2024, and there are no tagged GitHub releases.
What are the three pipelines in ColorFlow?
The Retrieval-Augmented Pipeline, the In-context Colorization Pipeline and the Guided Super-Resolution Pipeline. The architecture is dual-branch, with one branch extracting colour identity and the other performing colourisation, using self-attention in the diffusion models for in-context learning and colour identity matching.
How do I run ColorFlow locally?
Clone the repository, create a conda environment with Python 3.8.5, install requirements.txt, then run python app.py. That launches a Gradio interface on localhost at port 7860, and a different port means changing the server_port argument in demo.launch() inside app.py.
What licence does ColorFlow use?
The README does not name one. It links to the licence file in the repository root, and GitHub records no licence identifier for the project, so anyone using the code or the separately published model weights needs to read those terms directly.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tencentarc-colorflow)Star history chart for your README
[](https://hysenlabs.com/projects/tencentarc-colorflow)Was this useful?