tfjs-models ships two pose packages and two hand packages, and its only tagged releases are pre-releases from 2021
Pretrained models for TensorFlow.js
At a glance
- What is it?
- This repository holds a set of pre-trained models ported to run in the browser, each published as its own package under one scope. It is Apache-2.0 licensed, and its default branch was pushed to on 2026-06-23. Two things in its configuration are worth knowing. Its top level contains two packages for body pose detection and two for hand pose detection, and its development dependencies include the fs package at version ~0.0.1-security.
- Who is it for?
- This is still where you go if you want a working vision or text model in a browser tab without wiring a runtime yourself, because each model is a separate package with its own documentation and a demo page, and the front page states the design intent plainly, which is to hide tensors so the API is usable by people who do not work in machine learning. Two things to check before you start.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 145 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
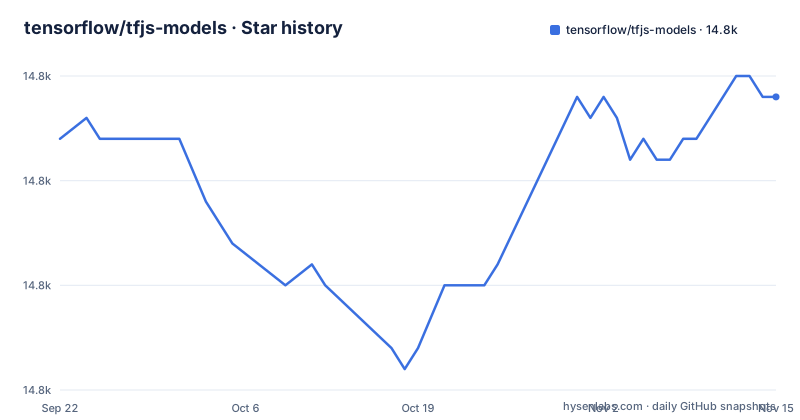
- tensorflow/tfjs-models14,814 ★ · +2
| Repository | 2026-09-22 | 2026-11-15 |
|---|---|---|
| tensorflow/tfjs-models | 14.8k | 14.8k |
2 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Four pose packages where you would expect two
The top level of this repository contains more pose packages than there are poses.
There is a hand pose detection package and there is a separate hand pose package. There is a pose detection package and there is a separate pose net package. Plus a face landmarks package, a face detection package and a blaze face directory.
That is four packages covering two body parts.
The README's own links hint at the split. The live demo for the newer hand pose package passes model=mediapipe_hands, and the face landmarks demo passes model=mediapipe_face_mesh, so the newer packages expose MediaPipe models, while the README table does not list the older handpose and posenet packages at all.
Both sets still have top-level directories in the repository.
So the consequence is that there is no single answer to which pose package to install. If you search for a pose package by task you will find two, and you have to work out from the directory names which generation each belongs to before you write any code against it.
The only tagged releases are two pre-releases from 2021
The release history of this repository is two entries, and both are pre-releases from the same spring five years ago.
One is an alpha build of a task-oriented package. The other is a release candidate build of the pose detection package. Neither is a stable release, and neither has been followed by one.
Meanwhile the default branch took a push in June 2026, so the code is being worked on.
There is a reasonable explanation. This repository is not one package. It is twenty-odd packages, each published separately under its own name and its own version, as the install commands in the front page's table show. A repository-level release tag has little meaning when the artefacts are the individual packages, so tagging has become occasional and ceremonial.
That is a defensible arrangement and it is also the reason you cannot use this repository to answer whether it is maintained. Every package has its own release history on its own registry page, and that is where the answer is.
So the consequence is that adoption decisions here have to be made package by package. A model whose directory has recent commits is a different proposition from one that has not been touched since 2021, and the repository-level view tells you nothing about which is which.
A development dependency is pinned to a version literally named security
There is a line in the development dependencies of the workspace manifest that reads like a joke and is not one.
The package is fs, at ~0.0.1-security, a placeholder version on the registry.
The question is why it is there at all. A build running on a real runtime has no need for the shim, and a bundler for the browser would need it only if some code imported it. Its presence as a direct dependency suggests either that something in the tree does import it, which is a real dependency on a package that does nothing, or that it was added to silence an install warning and never removed.
Either way it is a placeholder that reached the dependency list and stayed, and it is declared with a tilde range on a placeholder version.
The consequence for you is small but it is a signal. It suggests the dependency list here is not curated the way the package manifests of the individual models are, and that the workspace root has accumulated scaffolding over a long period without anyone doing a pass over it.
The build tooling in the workspace root is from 2022 and uses a linter that was deprecated
Read the development dependencies at the root of this repository and you are looking at a snapshot of about 2022.
The TypeScript compiler is pinned to exactly 4.9.5. The Node type definitions are declared as ~18.13.0, and ts-node as ~5.0.0.
And the linter is TSLint, with a plugin for detecting circular imports, plus a configuration directory and a configuration file at the root. TSLint was deprecated years ago in favour of a different linter, and it no longer receives fixes.
The bundler is rollup ^3.15.0 and the local-linking tool is the pre-release yalc ~1.0.0-pre.50, alongside rollup-plugin-sourcemaps and rollup-plugin-terser.
There is a plausible reason. Pinning the compiler in a workspace whose packages each declare their own tooling is how you keep twenty packages building consistently, and a monorepo that upgraded its compiler would have to verify every model package at once.
So the consequence is that contributing here means working inside a 2022 toolchain, while the individual packages you install are built and published by whatever their own configurations say. The root tooling tells you nothing about the toolchain your consumers get.
There are two test systems, a cloud build file and a pre-submit script
The repository has more kinds of automation than a set of model wrappers strictly needs, and each one tells you something.
There is a TypeScript pre-submit script referenced from the manifest, which is the local gate before a change goes anywhere. There is a shared test utility file at the root. There is a shell script that runs the Python tests, which tells you that not everything in this repository is TypeScript even though the language detection says it is.
There is a shell script to update the dependency lockfile, and a workspace file that opens the whole tree in an editor as one workspace rather than twenty folders.
And there is a cloud build configuration file, cloudbuild.yml, at the root.
The Python test script is the one to note. If some of the conversion or verification tooling for these models is in Python, that is consistent with how machine learning models are usually validated, and it means a contributor touching that tooling needs a second runtime.
So the consequence is that the definition of done here spans several systems, and a contributor who only runs the JavaScript gate may miss the Python tests.
Several models have no live demo linked, and the install column is the only reliable one
The models table on this front page has five columns and one of them is unreliable.
There is a type, a model name, a live demo, details, and an install command. The install column is complete for every model: each row has a package name and a command.
The live demo column is not. Several rows have an empty link. The object detection model has no live demo. The semantic segmentation model has none. The sentence encoder has none.
Each of those rows does have a source link to the demo folder inside the repository, so the code is there and you can run it locally.
Rows with a live demo point at a hosted storage bucket, and the ones that are missing are the ones whose hosted demo was either never published or has been taken down. The speech commands model, for instance, points at a bucket path with a date in it from early 2019.
So the consequence is that the hosted demos are not a reliable index of what works. The install commands and the source folders are. If you are evaluating a model, read its directory documentation rather than trusting that a demo link exists, and expect to run the source demo yourself if there is no hosted one.
The front page explains the design intent, which is that you should not have to know about tensors
One paragraph in this front page states what the project is optimising for, and it is worth reading because it sets the expectation for every package here.
It says the documentation for each model is in its own directory, and that in general the project tries to hide tensors so the API can be used by people who are not machine learning experts.
That is the design principle. You get a function that takes an image or text and gives you a prediction, rather than a tensor you have to know how to read.
It also explains why the repository accepts new models on a particular basis. The contribution note asks you to file an issue on a different repository first to gauge interest, and says the project is trying to add models that complement the existing set and can be used as building blocks in other applications.
So there is a gate before a model is accepted, and a stated criterion for what earns a place: it fills a gap rather than duplicating something already there.
The consequence for you as a user is that the packages should be usable without reading a machine learning textbook, which is a real and under-appreciated property. And if you want to contribute a model, the process starts in another repository, not here.
Editorial conclusion
This is still where you go if you want a working vision or text model in a browser tab without wiring a runtime yourself, because each model is a separate package with its own documentation and a demo page, and the front page states the design intent plainly, which is to hide tensors so the API is usable by people who do not work in machine learning. Two things to check before you start. Which package you actually want, since four of them are pose models and picking the wrong one means a different API and a different model. And whether you can accept the maintenance signal, because the only releases ever tagged in recent times are two pre-releases from 2021 while the branch itself keeps receiving commits.
Frequently asked questions
What are the pre-trained TensorFlow.js models?
A set of pre-trained models ported to run in the browser, published on the JavaScript package registry and a content delivery network so they work out of the box, and usable directly or in a transfer learning setting. The set covers image classification, hand and body pose detection, object detection, semantic segmentation, face detection and facial landmarks, audio classification, text embeddings, toxicity scoring, depth estimation, text generation, question answering, and a nearest-neighbour classifier. Each is a separate package with its own documentation.
How do I install a model from this repository?
Each model is a separate package under one scope, and the front page's table gives the exact command per model, such as installing the image classification package, the hand pose package, the body pose package, the object detection package, or the sentence encoder. The models are also served from a content delivery network if you would rather load one without a bundler.
Is TensorFlow a Python module?
This repository does not answer that. It holds pre-trained models ported to JavaScript for the browser, published as JavaScript packages, and its own tooling includes a script for running Python tests, so Python appears in the build process. The README says the models have been ported to TensorFlow.js.
Does anyone still use TensorFlow?
The front page makes no claim about the framework's adoption and does not address the question. What it does state is its own intent: the models are ported to run in the browser, the API hides tensors so it can be used by people who are not machine learning experts, and new models are accepted when they complement the existing set and can be used as building blocks in other applications.
Which is better, TF or PyTorch?
Not addressed here. This repository is a set of pre-trained models for one JavaScript framework, ported from elsewhere: the object detection model is based on the TensorFlow object detection API, and the newer hand and face packages' demos load MediaPipe models. The front page compares nothing.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tensorflow-tfjs-models)Star history chart for your README
[](https://hysenlabs.com/projects/tensorflow-tfjs-models)Was this useful?