tflite-micro: the line length is set and then the check is switched off
Infrastructure to enable deployment of ML models to low-power resource-constrained embedded targets (including microcontrollers and digital signal processors).
At a glance
- What is it?
- TensorFlow Lite for Microcontrollers is a port of TensorFlow Lite aimed at processors and signal processors with little memory, and its readme is mostly status tables: eight continuous integration workflows, eight community ports that live in other repositories, about twenty documentation pages and two design records. Its Python configuration sets a line length and then ignores it, indents by two spaces, and preserves whatever quote style each author chose.
- Who is it for?
- TFLM suits a team porting a quantised model to a specific microcontroller and willing to read the porting and memory management documents rather than expect a framework, because what is here is an interpreter, a kernel porting guide and a set of build targets rather than an application layer.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
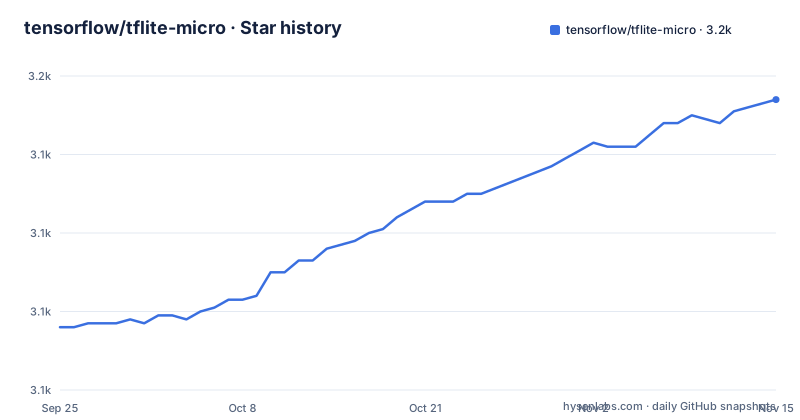
- tensorflow/tflite-micro3,154 ★ · +58
| Repository | 2026-09-25 | 2026-11-15 |
|---|---|---|
| tensorflow/tflite-micro | 3.1k | 3.2k |
58 Stars in the last 51 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The line length is set and then the check is switched off
The repository's Python configuration is short enough to read in full and contains one contradiction. It sets a maximum line length of eighty characters, and then, in the rule selection block further down, it explicitly ignores the rule that checks line length. So the number is configured and not enforced, which means the eighty-character value survives only for whatever consumes it outside the linter, such as a formatter, and a line of any length will pass the check. The rest of the selection is narrower than it looks. Two whole rule families are opted into, covering style and common errors, and then exactly three individual checks from a third-party plugin are added: mutable default arguments, unused loop variables, and loop variables that shadow the iterable. Those three are a deliberate concession in a codebase that embeds generated kernels, because generated code violates them by nature. Everything else from that plugin is left out. The three settings that carry the contradiction and the two choices are short enough to see together:
line-length = 80
indent-width = 2
target-version = "py310"
The indentation is configured to two spaces
The same configuration sets the indent width to two, which is half the value the language's own style guide recommends and half what most Python formatters assume by default. It sits next to a line length of eighty, so the project has deliberately chosen the width of a compact layout and the width of a readable measure together, and the two are consistent with each other. Neither choice is wrong on its own. The point is that both are set in a repository whose primary language is not Python at all, where the Python is the tooling layer, and where a large part of the Python present comes from elsewhere. A reader arriving at this file for a different reason, from a lint failure or a contributor guide, will find a style configuration that does not match what they are used to, with no comment explaining the choice.
Quote style is preserved so the formatter will never normalise a quote
The formatter block contains one setting and it is a negation. Quote style is set to be preserved, which means the formatter will not rewrite single quotes to double or the reverse. Most Python formatters normalise to one style so that a diff touching one line of a string does not also show a change of quote characters. Turning that off trades consistency for smaller diffs and for letting a codebase keep whatever it already has. The practical consequence is that this repository's Python can, and probably does, contain both quote styles permanently, and that a reformat will not converge them. It is a defensible preference in a repository carrying synced code from more than one source, since preserving is the only behaviour that does not produce diffs in files the project does not own.
The community port table is eight repositories and two of them are personal
The table titled as community supported examples lists eight platforms, and each row is a link to a different repository rather than to anything inside this one. Arduino, Espressif, Renesas, Silicon Labs, Coral, Sparkfun and Texas Instruments all point at organisation repositories. Two do not: one Ingenic MIPS port and the Sparkfun Edge port both live under individual accounts. One row is formatted differently again, because its platform cell is a link to a vendor product page rather than a plain name, and the Arduino row is the only one whose cell contains a continuous integration status badge rather than a link. The readme does not say which of these platforms are tested by this project as opposed to by their maintainers; it points at a document about adding platform support and leaves the distinction implicit in the table title.
The monthly meeting link points at a bare host name
The Getting Help section says a GitHub issue should be the primary route to the project team, which is the right default. Below it is a list of community resources, and the second item is broken in a way that is worth knowing about before you rely on it. The special interest group entry pairs an email group with monthly meetings, and the meeting link's host is a single word that is not a domain. The chat room in the next item points at a chat service whose operator wound it down. What is left working is the issue tracker and the email list, and the last item correctly routes anything not specific to this project to four broader project venues. So the practical answer to getting help is the issue tracker, and the meeting link that would otherwise be the most useful thing on the page does not resolve.
A third of the lint exclusions exist because the tree is synced
Five paths are excluded from the Python linting. One is the continuous integration directory and one is the notebook pattern. The other three are the vendored dependency directory, a Python directory inside the nested TensorFlow tree, and a tools directory inside it. That is three exclusions out of five that exist for code the project did not write, and the pattern is the clearest signal on the page that this repository is partly a mirror. The continuous integration table includes a workflow named for syncing, the documentation index carries a page about automatically generated files, and the tree holds both a vendored directory and a nested copy of the parent project's source space, with the documentation links pointing into it. So the exclusions are not a style preference; they are a boundary, and the boundary is between what this project maintains and what arrives from upstream.
The table of contents lists the heading that appears after it
The readme's table of contents is generated, not written, and you can see both the mechanism and a small artefact of it. Two marker comments bracket the block, and inside them sits a second comment naming who added the block and the exact date and time it was added. The generated list opens with an entry for the document's own main heading, even though that heading sits below the list, which is why the first thing a reader sees is a link to the title they are already looking at. That is a two-line artefact in a page that is otherwise entirely tables and links, and it is worth mentioning only because it confirms that the contents will be rewritten by a script rather than by hand, which is also why the table of contents has drifted away from the sections further down: the RFC section and the additional documentation section sit under headings that the generated list does cover, but the list stops at the contributing section and the several documentation groups that follow it are absent from it.
The project keeps two design records and both are about memory and quantisation
The RFC section at the bottom of the readme contains two documents, numbered one and two in their paths, which means the project's entire design record is those two. The first is about pre-allocating tensors, which is the memory question asked before the kernel question: on a device with tens of kilobytes of RAM, deciding where a tensor's storage comes from is the decision everything else depends on. The second is a port of a sixteen-bit-by-eight-bit quantised operator set, which is the arithmetic question, cutting the width of weights and activations so a model fits at all. Together they say what this port is for. The documentation index points the same way, with pages for memory management, compression and an MNIST compression tutorial, and separate pages for porting kernels from the parent project and for the optimised implementations of those kernels.
Editorial conclusion
TFLM suits a team porting a quantised model to a specific microcontroller and willing to read the porting and memory management documents rather than expect a framework, because what is here is an interpreter, a kernel porting guide and a set of build targets rather than an application layer. It is a poor fit if you need one supported story across many boards, because the eight ports outside the core are community maintained in separate repositories with their own continuous integration and, in two cases, personal maintainers. Before you commit to a board, check whether it appears in the core workflows or only in the community table, and read the generated-files documentation to find out how much of the tree you would be editing by hand versus how much arrives from the parent project on the next sync.
Frequently asked questions
what is tflite micro
TensorFlow Lite for Microcontrollers is a port of TensorFlow Lite designed to run machine learning models on digital signal processors, microcontrollers and other devices with limited memory. The repository holds the C++ core, build configuration for several processor architectures, around twenty documentation pages, and a table of eight community maintained ports that live in separate repositories.
tflite micro vs tflite
This project is the port, not a different format. The readme describes it as a port of TensorFlow Lite intended for constrained devices, and the difference it makes is in kernels, memory handling and build targets rather than in the model file. It does not discuss how the format itself differs between the two, and it points at documentation on compression and on porting kernels from the parent project.
Which platforms does TFLM support?
The readme surfaces eight continuous integration workflows grouped as Core, Targets and Misc, with the Targets group naming four processor architectures, and it lists eight community supported ports that live in their own repositories, including two under individual accounts. The page does not state which platforms are tested by this project rather than by their maintainers.
How do I get help with TFLM?
The readme says a GitHub issue should be the primary method of reaching the team. Below that it lists an email group and monthly meetings for a special interest group, a chat room, and four broader project venues for questions that are not specific to this project. The meeting link's host is a bare word rather than a domain and does not resolve, and the chat room points at a service whose operator has wound it down.
How much of the TFLM repository is generated rather than written here?
The documentation index includes a page specifically about automatically generated files, the continuous integration table includes a workflow named for syncing, and the tree carries both a vendored dependency directory and a nested copy of the parent project's source space that the documentation links point into. Three of the five paths excluded from Python linting are inside that nested tree.
Is TensorFlow Lite free, and what is the file format used for?
This page does not address pricing or describe the model file format. It describes a port of a runtime for constrained devices and points at documentation on compression, memory management, kernel porting and a two-entry design record covering pre-allocated tensors and a low-bit-width quantised operator port.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tensorflow-tflite-micro)Star history chart for your README
[](https://hysenlabs.com/projects/tensorflow-tflite-micro)Was this useful?