open-rag-eval scores a RAG pipeline without a golden answer set
RAG evaluation without the need for "golden answers"
At a glance
- What is it?
- A Vectara-maintained Python toolkit that evaluates retrieval-augmented generation with UMBRELA and AutoNuggetizer instead of hand-labelled references. The metrics are the interesting part; the dependency list and the container command are what you will notice later.
- Who is it for?
- Adopt open-rag-eval if you have a RAG system, no labelled reference answers, and a tolerance for LLM-judged scores that cost money on every run. Do not adopt it if you need reproducible offline metrics or a light install: the pip dependency set pulls torch and transformers, and the default factual-consistency path needs either a gated Hugging Face model or a paid Vectara API key.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 38 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
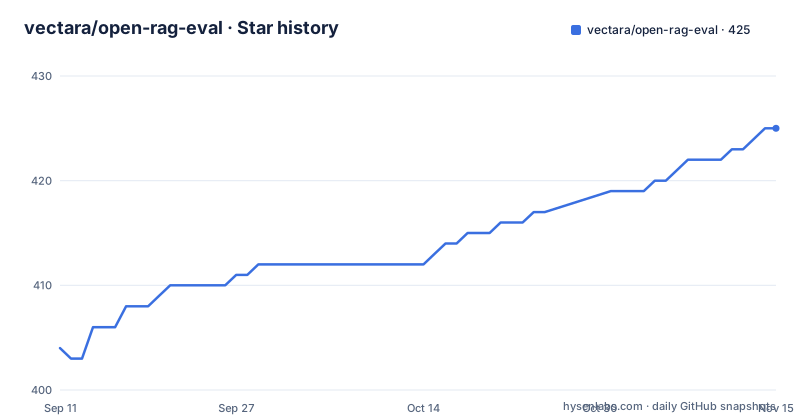
- vectara/open-rag-eval425 ★ · +21
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| vectara/open-rag-eval | 404 | 425 |
21 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The metrics that make golden answers optional
Most RAG evaluation wants a reference set: correct chunks, or correct answers, labelled by hand. open-rag-eval is built around two techniques that do not ask for either. UMBRELA and AutoNuggetizer come from research done in Jimmy Lin's lab at UWaterloo, and the project credits those two papers as the source of the approach rather than presenting the metrics as its own invention.
That is the whole pitch in the repository description: evaluation without the need for golden answers. The corollary is that scores are produced by a model judging text rather than by string comparison against a known right answer, so a run costs tokens and needs an API key.
Golden answers are not banned. The toolkit supports optional evaluation against reference answers when you have them, using metrics chosen for that job. METRICS.md at the repository root holds the detailed documentation for the set, and the default metric implementation is the one used in the TREC-RAG benchmark.
pip install open-rag-eval also installs the CLI
The package installs from pip, and the distribution ships a command called `open-rag-eval`, so you can evaluate and plot without cloning anything:
pip install open-rag-evalThe alternative is a source checkout, which is what you want if you intend to edit example configs or work on the metrics themselves:
git clone https://github.com/vectara/open-rag-eval.git
cd open-rag-eval
pip install -e .
The packaging is old-fashioned and easy to read. `setup.py` registers a single console script, `open-rag-eval=open_rag_eval.cli:main`, pulls its dependency list straight out of `requirements.txt`, and takes the version from `open_rag_eval/_version.py` with a regular expression rather than hardcoding it. `python_requires` is `>=3.9`, matching the prerequisite the README states, and the classifiers mark the project as Beta. The author of record is Suleman Kazi at Vectara, and the documentation URL in the metadata points at a GitHub Pages site rather than the repository itself.
Three connectors, one of which is the vendor's own
Out of the box the toolkit can query three systems: the Vectara RAG platform, LlamaIndex and LangChain, with more described as coming. Two of those are mainstream open source, and the third is the platform this project is maintained by, which is worth keeping in mind when you read the configuration examples.
The Vectara path is the one documented end to end. Enabling it needs a Vectara account, a corpus containing already indexed data, an API key with querying permissions, and your Customer ID and Corpus key. That is four things to collect before an evaluation can run, three of which come from a paid service.
The LlamaIndex and LangChain connectors exist but the visible documentation does not walk through either of them. They are listed as supported, and the config layout for them is not shown here, so anyone adopting this for a LangChain pipeline is reading connector source rather than a guide.
One YAML file decides connector, evaluator and metrics
Evaluation is configured through a YAML file, and the Vectara example is `eval_config_vectara.yaml` under `config_examples/`. The same file controls connector options, evaluator choice and metric settings, which means a run is reproducible from one artefact you can commit.
Five keys carry most of the weight. `input_queries` points at the query file, `generated_answers` and `eval_results_file` name the two output files, and `results_folder` collects every artefact a run produces. The connector block sits under `options` and `query_config`, where your Vectara `corpus_key` goes, alongside any Vectara query parameter you want to change.
Secrets do not belong in that file. The example interpolates `${oc.env:VECTARA_API_KEY}` through OmegaConf, so the key comes from the environment and the config stays shareable. Synthetic query generation is also reachable from the configuration: instead of writing queries by hand you can have the toolkit produce them, which is the point of a system that does not want golden data in the first place.
queries.csv is one column and nothing else
The query file is a CSV with a single column named `query`, one row per question you want to put through the pipeline:
query
What is a blackhole?
How big is the sun?
How many moons does jupiter have?
That is the entire contract for input, and it is deliberately dull. A run reads the file, sends each query through the configured connector, and writes per-query scores plus intermediate output so you can see what the retriever returned rather than only the final number.
Those intermediate outputs are the debugging path. When a score drops, the report is supposed to let you trace which retrieved chunk caused it, which is the difference between a metric you can act on and one you can only quote. The plotting utilities exist to compare scores across configurations or across runs, so a change to chunk size or a query parameter can be read as a line rather than a claim.
A prompt template that falls back instead of failing
Vectara generates its own answer from retrieved results, and the toolkit lets you override that generation prompt. There are two ways, and the difference is one line of YAML. Point `prompt_template` at a file path:
connector:
  type: "VectaraConnector"
  options:
    api_key: ${oc.env:VECTARA_API_KEY}
    corpus_key: "your-corpus-key"
    query_config:
      generation:
        prompt_template: "path/to/my_prompt.txt"
Or put the prompt string inline under the same key. `sample_prompt.txt` at the repository root is there to copy from.
The behaviour on a bad path is the detail worth knowing. File-based templates are read as UTF-8, leading and trailing whitespace is stripped, and if the file cannot be read at all the connector logs a warning and carries on with Vectara's default prompt. That is a deliberate choice for a template file, and it is exactly the wrong behaviour for anything load-bearing, because a typo in the path produces a green run against the wrong prompt.
Every path through this needs a key from somewhere
The prerequisites are the real cost of the project. Python 3.9 or higher, and an OpenAI API key exported as `OPENAI_API_KEY`, because the default LLM judge model is used by some of the metrics. An evaluation run is a sequence of model calls.
Factual consistency, which is the hallucination detection path, has two options. The default is the open source HHEM model, which needs a Hugging Face token in `HF_TOKEN` and accepted access to the `vectara/hallucination_evaluation_model` model on Hugging Face. The alternative is the Vectara commercial Factual Consistency API, which needs a Vectara API key instead.
So there are three keys in play across the default and alternative paths, and two of them point at a hosted commercial service. That is a reasonable trade for a metric that needs no labelled data, and a poor fit for an air-gapped evaluation run or a budget that cannot absorb a judge call per query.
A tokenizer install for an evaluation CLI
The dependency list is where a reviewer should stop and read. `requirements.txt` pins `torch==2.7.1` and `transformers==4.50.2` for the local HHEM path, and then adds `pandas==2.2.3`, `pydantic==2.11.7`, `flask==3.0.3`, `streamlit`, `matplotlib`, `seaborn`, `rouge` and `torchmetrics`, plus the whole LangChain stack and `llama_index`. Optional `unstructured[pdf]` covers PDF ingestion.
That is a machine learning install attached to a command whose primary job is counting tokens and judging text. It is defensible when you want the local HHEM model, and expensive when you only want the LLM-judged metrics.
The container shows the same weight. The image is `python:3.10-slim`, installs `build-essential`, copies the whole repository into `/app`, and runs `pip install --no-cache-dir -r requirements.txt` on port 5000. Its command is `python run_server.py --host 0.0.0.0 --port 5000`, and `run_server.py` does not appear among the top-level entries of the repository, so that path does not resolve from a fresh clone. The Makefile has a second quiet problem: `lint` and `mypy` both end in `|| true`, so neither reports a failure to the build.
Editorial conclusion
Adopt open-rag-eval if you have a RAG system, no labelled reference answers, and a tolerance for LLM-judged scores that cost money on every run. Do not adopt it if you need reproducible offline metrics or a light install: the pip dependency set pulls torch and transformers, and the default factual-consistency path needs either a gated Hugging Face model or a paid Vectara API key. Verify two things first. Put your model name in a config file and read the resulting per-query report, because the score is only as good as the query set you wrote. Then check which judge model the metric defaults to, since that choice sets your per-run cost.
Frequently asked questions
What are RAG evals?
They measure how well a retrieval-augmented generation pipeline answers questions, so you can tell whether a change to retrieval or generation helped. open-rag-eval does this with UMBRELA and AutoNuggetizer, which need neither golden chunks nor golden answers, and it also supports optional evaluation against reference answers when you have them.
How do I install open-rag-eval?
Run pip install open-rag-eval, which also installs the open-rag-eval command line tool. For development or access to the example configs, clone the repository and use pip install -e . instead. Python 3.9 or higher is required.
Which systems can open-rag-eval query?
Connectors ship for the Vectara RAG platform, LlamaIndex and LangChain, with more described as coming. The Vectara connector additionally needs an account, a corpus of indexed data, an API key with querying permissions, and your Customer ID and Corpus key.
What does open-rag-eval need to detect hallucinations?
Two options for factual consistency. The default is the open source HHEM model, which needs a Hugging Face token in HF_TOKEN and accepted access to the vectara/hallucination_evaluation_model model. The alternative is the Vectara commercial Factual Consistency API, which needs a Vectara API key.
What happens if open-rag-eval cannot read a prompt template file?
File templates are read as UTF-8 with leading and trailing whitespace stripped, and if the file cannot be read the connector logs a warning and continues with the Vectara default generation prompt. A wrong path therefore produces a run against the default prompt rather than an error.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/vectara-open-rag-eval)Star history chart for your README
[](https://hysenlabs.com/projects/vectara-open-rag-eval)Was this useful?