GLM-OCR: the SDK installs in three sizes, and only one of them is small
GLM-OCR: Accurate × Fast × Comprehensive
At a glance
- What is it?
- GLM-OCR is a 0.9B multimodal OCR model for complex documents, shipped with a Python SDK that installs in three sizes: a thin cloud client, a self-hosted pipeline that pulls torch, and a Flask server. The deployment paths are unusually well specified, with exact vLLM and SGLang commands including speculative decoding flags for the model's multi-token prediction. The number to keep in mind is 0.1.5, because that is the SDK version and its classifier still says alpha.
- Who is it for?
- Use it when documents arrive as images or PDFs and you want layout-aware Markdown rather than a raw text dump, and pick your path early: cloud MaaS for the smallest install, vLLM or SGLang when you must keep documents local. Before you deploy either, read the self-hosted client configuration, because the example server validates no API keys and turns off SSL verification.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 31 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
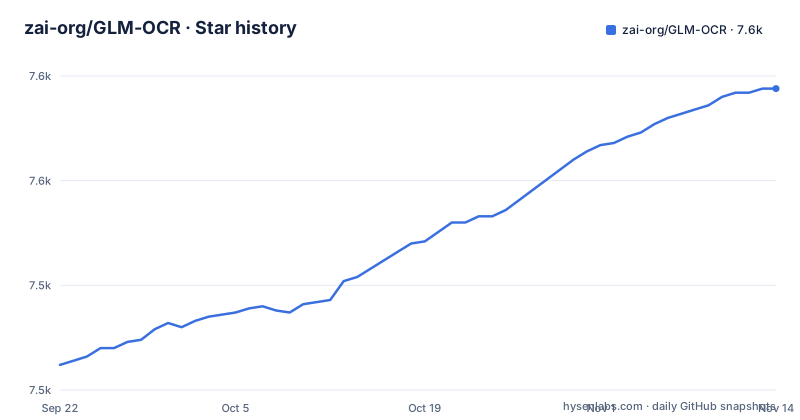
- zai-org/GLM-OCR7,594 ★ · +132
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| zai-org/GLM-OCR | 7.5k | 7.6k |
132 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three extras, and only the cloud one avoids torch
The SDK install is presented as a choice of three sizes, which is the clearest signal in the README about what each deployment costs:
# Cloud / MaaS + local images / PDFs (fastest install)
pip install glmocr

# Self-hosted pipeline (layout detection)
pip install "glmocr[selfhosted]"

# Flask service support
pip install "glmocr[server]"
The base install pulls a modest set: pillow, numpy, requests, pydantic, PyYAML, portalocker, python-dotenv, tqdm and pymupdf. The self-hosted extra adds opencv-python-headless, torch, torchvision, transformers, sentencepiece, accelerate and pypdfium2. So the promise of a 0.9B model with low compute comes with a dependency tree that is not small until you notice which extra you installed. From source the path is a git clone, a uv virtual environment on Python 3.12, and `uv pip install -e .`. The console entry point is registered as `glmocr = glmocr.cli:main`, so a correct install gives you a command, not just an import.
In MaaS mode the SDK forwards your documents and rewrites your payload
The cloud path is described as the fastest way in and is honest about what it is: a thin wrapper. You get an API key from open.bigmodel.cn and a config file with `pipeline.maas.enabled` set to true plus your key, after which the SDK forwards your documents to the Zhipu cloud API and returns Markdown plus JSON layout details, with no local processing and no GPU required. The input note is the part worth reading twice. The upstream API accepts `file` either as a URL or as a `data:<mime>;base64,...` data URI, and if you hand over raw base64 without the `data:` prefix the README recommends wrapping it, and the SDK will auto-wrap local file paths, bytes and raw base64 into a data URI when calling MaaS. The practical consequences are that your documents leave the machine, and that the library is rewriting your payload shape for you rather than passing bytes through unchanged.
Self-hosting means a speculative decoding flag in both serving paths
The model's training choices reappear as serving flags, which is the most interesting mechanical detail in the README. The vLLM path installs `vllm>=0.19.0` or pulls `vllm/vllm-openai:v0.19.0-ubuntu2404`, adds `transformers>=5.3.0`, and then serves the model with a speculative config written as JSON that turns on the MTP method with three speculative tokens. The SGLang path pins `sglang>=0.5.10` or `lmsysorg/sglang:v0.5.10` and launches with `SGLANG_ENABLE_SPEC_V2=1`, a NEXTN speculative algorithm, three steps, topk 1 and four draft tokens. Both launch commands carry a note to add your own length and memory flags to handle large images or PDFs. The consequence is coupling: the architecture's multi-token prediction is wired into serving configuration, so an upgrade of vLLM or SGLang means re-checking that JSON rather than only that the model loads.
The self-hosted server validates no keys and the client disables SSL verification
Option 4 lets you run the SDK server on a GPU machine and connect from a client with no GPU, over a MaaS-compatible protocol. The client configuration makes the trust model explicit:
# Client config.yaml
pipeline:
  maas:
    enabled: true
    api_url: http://<SERVER_IP>:5002/glmocr/parse
    api_key: any-string    # self-hosted server does not validate keys
    verify_ssl: false
Two things in those lines deserve attention rather than copying. The key field is documented as any-string because the self-hosted server does not validate keys, and TLS verification is turned off. That combination is fine on a trusted network and dangerous anywhere else, since anyone who can reach that endpoint can submit documents and receive parsed results. If you deploy this, put it on a private interface or behind something that authenticates, and turn verification back on. The path itself is `/glmocr/parse` on port 5002, which is the contract to keep in mind when you put anything in front of it.
Layout analysis by PP-DocLayout-V3 runs in front of recognition
The architecture explains the dependency weight better than the feature list does. GLM-OCR is built on the GLM-V encoder-decoder design and combines a CogViT visual encoder pre-trained on large-scale image-text data, a lightweight cross-modal connector that does efficient token downsampling, and a GLM-0.5B language decoder. Multi-token prediction loss and stable full-task reinforcement learning are introduced on top to improve training efficiency, recognition accuracy and generalization. In front of that sits a two-stage pipeline of layout analysis and parallel recognition based on PP-DocLayout-V3. So what you download is not one model but a pipeline with a layout detector before the recognizer, which is why self-hosting needs torch and transformers even though the language decoder is only half a billion parameters. The reported result is a score of 94.62 on OmniDocBench V1.5, ranked first overall, with claims for formula recognition, table recognition and information extraction.
Version 0.1.5, classifier Alpha, and a release list that stopped in April
Versioning is where expectations need adjusting. The package name is glmocr at version 0.1.5, the licence is Apache-2.0, and the classifier says Development Status :: 3 - Alpha, with Python 3.10 through 3.13 declared as supported and requires-python set to >=3.10. The release list matches that framing: v0.1.5 published 2026-04-08, after v0.1.4 on 2026-03-19 and v0.1.3 on 2026-03-13. The repository is not archived and the last push is dated 2026-10-14. Nothing here is hidden, but the combination of a zero major version, an alpha classifier and a 0.1.x line means you should pin the SDK and pin your serving stack separately, because the two upgrade on different schedules and the serving commands in the documentation name exact vLLM and SGLang versions.
The skill mode exists for agents and skips both the GPU and the YAML
The most recent news entry changes the shape of the quick start. As of 2026.3.12 the SDK supports an agent-friendly Skill mode: install with `pip install glmocr`, set an API key, and it is ready to use from the CLI or from Python with no GPU and no YAML configuration. The skill itself lives at skills/glmocr/SKILL.md, and the repository also carries an agent.md at the top level. Two other resources sit alongside it. A fine-tuning tutorial based on LLaMA-Factory is in examples/finetune/, and a technical report is published on arXiv, so the reasoning behind the layout-plus-recognition design is documented rather than implied. Read together with the deployment guides, the picture is of a project with an opinionated self-hosted path, a deliberately thin cloud path, and a machine-readable entry point for tools that would rather not edit a configuration file at all.
Editorial conclusion
Use it when documents arrive as images or PDFs and you want layout-aware Markdown rather than a raw text dump, and pick your path early: cloud MaaS for the smallest install, vLLM or SGLang when you must keep documents local. Before you deploy either, read the self-hosted client configuration, because the example server validates no API keys and turns off SSL verification. And pin both the SDK version and your serving stack version, since the speculative decoding flags are tied to specific vLLM and SGLang releases.
Frequently asked questions
What does GLM-OCR do?
It is a multimodal OCR model for complex document understanding, built on the GLM-V encoder-decoder architecture with a CogViT visual encoder, a lightweight cross-modal connector and a GLM-0.5B language decoder. A two-stage pipeline of layout analysis and parallel recognition based on PP-DocLayout-V3 runs in front of it, and the SDK returns Markdown plus JSON layout details.
Can I run a GLM-OCR locally?
Yes, through vLLM, SGLang or Ollama, with an additional MLX path documented for Apple Silicon Macs. Self-hosting requires the glmocr[selfhosted] extra, which installs opencv-python-headless, torch, torchvision, transformers, accelerate and pypdfium2, and the model is served with speculative decoding flags for its multi-token prediction method.
how to install glm ocr
Three extras match three scenarios: pip install glmocr for cloud MaaS with local images or PDFs, pip install "glmocr[selfhosted]" for a self-hosted pipeline with layout detection, and pip install "glmocr[server]" for the Flask service. From source it is a git clone, a uv venv on Python 3.12, and uv pip install -e ., after which the glmocr console command is available.
is glm ocr a vlm
Structurally it is built as one: a GLM-V encoder-decoder with a CogViT visual encoder pre-trained on large-scale image-text data, a cross-modal connector that does efficient token downsampling, and a GLM-0.5B language decoder, for 0.9B parameters in total. Layout analysis by PP-DocLayout-V3 sits in front of recognition, so the practical system is a pipeline rather than a single vision language model call.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/zai-org-glm-ocr)Star history chart for your README
[](https://hysenlabs.com/projects/zai-org-glm-ocr)Was this useful?