apple/ml-mdm: Matryoshka Diffusion Models as a Training Framework
Train high-quality text-to-image diffusion models in a data & compute efficient manner
At a glance
- What is it?
- Apple's ml_mdm package trains nested-resolution diffusion models in pixel space, and its multi-scale nesting is the part that decides whether it fits your hardware. The framework is real, the API surface is narrow, and the constraints are worth reading before you clone it.
- Who is it for?
- Adopt ml_mdm if you are experimenting with nested multi-resolution diffusion and want the U-Net and nested U-Net implementations plus a working training CLI in one MIT-licensed package. Do not adopt it if you need a production inference server or a maintained model zoo, because the README points to a single research paper and three checkpoint URLs, not a supported product.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 64 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
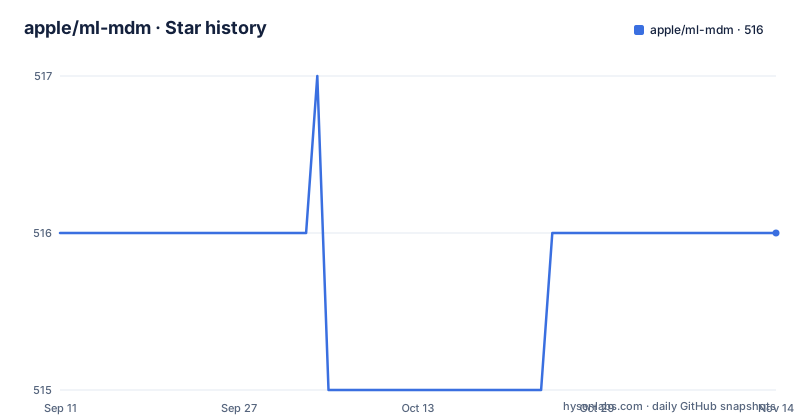
- apple/ml-mdm516 ★ · +0
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| apple/ml-mdm | 516 | 516 |
0 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem ml_mdm addresses: high-resolution diffusion without a latent stage
Most text-to-image diffusion pipelines compress images into a latent space before the U-Net ever sees them, which keeps compute manageable but adds an autoencoder that has to be trained or borrowed. Matryoshka Diffusion Models take the other route: the README describes the project as an end-to-end framework for high-resolution image and video synthesis that operates in pixel space, and it states that a single pixel-space model can be trained at resolutions up to 1024x1024 pixels. The audience is narrow and identifiable. This is for researchers who want to study nested multi-resolution denoising, and for engineers who need a reference implementation of U-Nets and nested U-Nets under an MIT licence. It is not a product for teams that want to call an image generation endpoint. The repository ships models, configs, CLIs, and a web demo, and the framing throughout is research code that accompanies a paper.
Nested U-Nets and the multi-scale pipeline
The mechanism is a nesting of denoising networks across resolutions. The README includes an architecture diagram labelled as the MDM multi-scale pipeline, and the ml_mdm.models submodule is described as containing implementations of U-Nets and nested U-Nets. The configs directory is split by role: configs.models holds configuration files for different resolution models, and the pretrained checkpoint URLs are organised the same way, with separate flickr64, flickr256, and flickr1024 paths. That layout tells you the resolutions are trained or loaded as distinct stages rather than one monolithic network. The diffusion logic lives in ml_mdm.diffusion, described as model pipelines such as DDPM, so the sampling procedure is separated from the network definitions. What the README does not give is the nesting algorithm itself in prose, the loss formulation, or the parameter counts. Anyone evaluating the method at that level has to read the arXiv paper, because the repository documentation stops at module boundaries.
Config dataclasses, SimpleParsing, and the --config_path flag
Configuration is the part of this codebase with the most visible design. The README states that many models, CLIs, and functions are configured by passing in a dataclass object, and that SimpleParsing is used to dynamically create command line interfaces and to allow passing YAML config representations through a --config_path argument. That is a real constraint on how you work with the project. You are not editing a flat YAML file and calling a script; you are composing dataclasses and letting SimpleParsing derive the flags. The payoff is that a config file and a set of CLI overrides share one code path. The cost is that error messages for a malformed config come from the dataclass layer, and the README does not document the schema of any individual config. The configs directory is the only reference, so reading configs.models and configs.datasets is not optional.
Getting it running: install, checkpoints, tests, and the web demo
Installation is a single editable install, and the README states the default dependencies in pyproject.toml are chosen so the library installs on a CPU-only machine. The command is pip install -e ., followed by pre-commit install for developers. The README notes users have run the codebase with Python 3.9 and 3.10 and with CUDA 12 and CUDA 11.8. Tests are split by marker: pytest runs cases that work on CPU only, pytest -m gpu runs only GPU cases, and pytest -m '' runs everything including the GPU tests. Pretrained checkpoints are three .pth files served from docs-assets.developer.apple.com, one each for 64, 256, and 1024 pixel models, downloaded with curl into vis_model_64x64.pth, vis_model_256x256.pth, and vis_model_1024x1024.pth. The web demo runs through torchrun --standalone --nproc_per_node=1 ml_mdm/clis/generate_sample.py --port $YOUR_PORT. Note the README says those released models were trained on 50M text-image pairs collected from Flickr, and that the repo provides CC12M download scripts and configs for training equivalent models on CC12M instead.
The dataset and prompt-file requirement is heavier than it looks
Training is not a matter of pointing the trainer at a folder of images. The data directory contains vocabulary files (bert.vocab, c4_wpm.vocab, cifar10.vocab, t5.vocab, tokenizer_spm_32000_50m.vocab) and paired prompt TSVs, including prompts_cc12m-64x64.tsv, prompts_cc12m-256x256.tsv, prompts_cifar10-32x32.tsv, prompts_cifar10-64x64.tsv, prompts_imagenet-64px.tsv, and prompts_WebImage-ALIGN-64px.tsv. The naming convention embeds both dataset and resolution, which means each resolution stage expects its own prompt file. If your dataset is not CC12M, CIFAR-10, ImageNet, or WebImage-ALIGN, you are writing a new prompt TSV and a new config before the first training step. The README points to CC12M download scripts, and the paper's headline claim is zero-shot generalisation from CC12M's 12 million images, but the released checkpoints come from a different 50M Flickr corpus. That mismatch between the released weights and the documented training data is a real friction point for anyone trying to reproduce a specific result.
Where ml_mdm is the wrong tool
Three failure modes stand out. First, production serving. The only inference path described is a web demo launched with torchrun and a single process, which the README presents as a demo, not a service. There is no mention of batching, quantisation, ONNX export, or a serving API. Second, teams that want a latent-space pipeline. If your existing stack is built around a VAE and a latent diffusion U-Net, ml_mdm's pixel-space approach means the checkpoints and the training loop do not plug into your existing inference code at all. Third, anyone who needs documented config schemas. SimpleParsing generates flags from dataclasses, and the README does not enumerate those flags, so trial and error against the configs directory is the expected workflow. There is also the maintenance question: the README lists no release tags, and the repository is a paper companion. Treat the code as a snapshot of a research method rather than a library with a deprecation policy.
How it differs from the Hugging Face diffusers route
The obvious alternative for text-to-image work is the diffusers library from Hugging Face, and the difference is architectural rather than cosmetic. Diffusers is built around a registry of pipelines and schedulers, with pretrained models loaded by identifier and a broad set of community checkpoints. It assumes you will consume models more often than you will define new ones, and its latent-space defaults mean you inherit a VAE. ml_mdm inverts that. It gives you the U-Net and nested U-Net definitions, a dataclass config system, and training CLIs, and it expects you to bring data and compute. The nesting of resolutions is the research contribution, and diffusers does not ship an equivalent nested U-Net as a standard building block. If your goal is to generate images today, diffusers has the shorter path. If your goal is to modify the denoising architecture across resolutions, ml_mdm exposes the parts you would otherwise have to write from scratch.
Maintenance cost, licence, and what to check before adopting
The repository is MIT licensed, which permits commercial use, modification, and redistribution provided the copyright notice and permission notice are included. That is a permissive default, and it is the main reason a research codebase can be worth adopting despite thin documentation. The practical costs are elsewhere. You inherit SimpleParsing as a dependency for every CLI interaction, and you inherit the dataclass config layer, so upgrading means checking whether config fields moved. The pretrained checkpoints are hosted on Apple developer asset URLs with no versioning scheme described, and the README gives no checksums, so a re-download is not verifiable against a published hash. Before adopting, download one checkpoint and run pytest -m gpu to confirm your CUDA setup matches the two configurations the README mentions. If that passes, the module layout in ml_mdm.models and ml_mdm.diffusion is small enough to read in an afternoon, which is the right way to judge whether the nesting approach fits your work.
Editorial conclusion
Adopt ml_mdm if you are experimenting with nested multi-resolution diffusion and want the U-Net and nested U-Net implementations plus a working training CLI in one MIT-licensed package. Do not adopt it if you need a production inference server or a maintained model zoo, because the README points to a single research paper and three checkpoint URLs, not a supported product. Verify first that your PyTorch and CUDA combination matches what the README states users have run (Python 3.9 or 3.10, CUDA 12 or 11.8), and confirm you can download one of the three vis_model.pth files before committing to a training run.
Frequently asked questions
What is ml-mdm?
A Python package for training high-quality text-to-image diffusion models, released alongside the Matryoshka Diffusion Models paper. It is an end-to-end framework for high-resolution image and video synthesis built on U-Nets and nested U-Nets.
What pretrained models does ml-mdm ship?
Three checkpoints at 64, 256 and 1024 resolution, hosted on an Apple developer asset domain. They were trained on 50 million text-image pairs collected from Flickr, while the repository ships scripts and configs for training equivalent models on the 12 million-image CC12M dataset instead.
Does ml-mdm install on a machine without a GPU?
Yes. The default dependencies in the packaging metadata are chosen so the library installs on a CPU-only machine. Users report Python 3.9 and 3.10 with CUDA 11.8 and CUDA 12, and a bare pytest run is limited to the CPU-capable tests.
How do you run the ml-mdm web demo?
After downloading the checkpoints, launch the sample generator under torchrun on a single process and pass the port you want. A downloaded checkpoint can also be supplied as an argument to training and to sampling.
How is ml-mdm configured?
Models, command line tools and functions are configured with dataclass objects. A parsing library converts command line arguments and YAML files into typed configuration classes, and YAML representations can be supplied through a configuration path argument.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/apple-ml-mdm)Star history chart for your README
[](https://hysenlabs.com/projects/apple-ml-mdm)Was this useful?