LLM-RL-Visualized: A Diagram Library for LLM and Reinforcement Learning Concepts
100+ original LLM/RL algorithm diagrams, from the author of the book Large Model Algorithms (100+ LLM/RL Algorithm Maps).
At a glance
- What is it?
- This repository packages over 100 original SVG and PNG diagrams covering LLM, VLM, RLHF, DPO, PPO, GRPO, and reasoning techniques. It is a reference companion to a Chinese textbook, not a software tool.
- Who is it for?
- Adopt this repository if you are a student, educator, or practitioner who needs a broad visual survey of LLM and RL concepts, especially if you read Chinese and want diagrams that pair with a structured textbook. Do not use it as a reference for implementation details, because the diagrams are pedagogical illustrations, not engineering blueprints.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 66 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
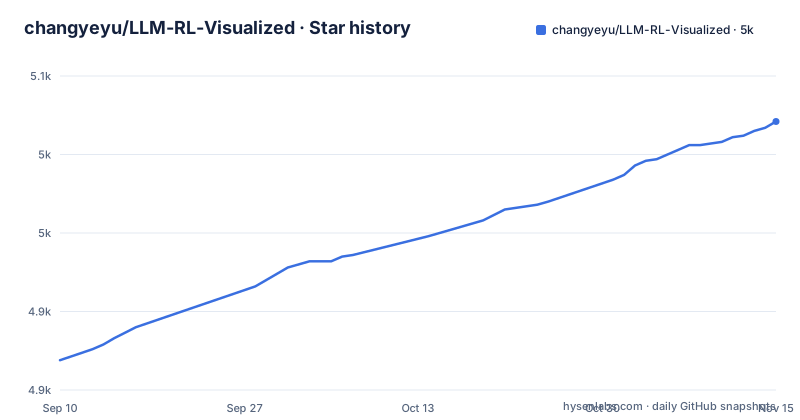
Star history
- changyeyu/LLM-RL-Visualized5,021 ★ · +152
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| changyeyu/LLM-RL-Visualized | 4.9k | 5k |
152 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What This Repository Actually Contains
LLM-RL-Visualized is not a software project. It is a collection of static image files, mostly SVG and PNG, organized as a visual index for large language model and reinforcement learning topics. The README lists over 120 named diagrams, each linked to a section. The scope spans basic LLM architecture, decoding methods, SFT, LoRA, DPO, RLHF, PPO, GRPO, RAG, Monte Carlo methods, DQN, policy gradients, multi-agent RL, and even position encodings like RoPE and ALiBi. The author claims these are original creations. The repository also points to a Chinese book, "大模型算法:强化学习、微调与对齐", as a companion text for deeper explanation. The primary audience is someone studying these algorithms, not someone building or deploying them.
The Diagram Format: SVG as a Living Document
The repository emphasizes that images are available as SVG files, which the README calls "活图" or living images. The claimed benefits are infinite zoom and selectable text. That is a real advantage over raster PNGs. If you need to present a diagram in a lecture or embed it in a document, an SVG can scale cleanly. The repository layout shows images_chinese/ and images_english/ directories, which hold the images. The README instructs users to click an image for a high-resolution view or browse the SVG files directly. There is no code to run, no build system, and no package to install. The deliverable is the image set itself.
How the Content Is Organized and What It Covers
The table of contents is the main navigation. It is split into eleven parts. Part 1 offers an overall architecture map and a reinforcement learning algorithm map that the author calls the largest on the internet. Part 2 covers LLM structure, decoding, input and output layers, and VLM. Part 3 goes into SFT, LoRA, and packing. Part 4 is dedicated to DPO. Part 5 lists training-free techniques like CoT, sampling methods, and RAG. Parts 6 and 7 cover RL fundamentals and policy optimization, including PPO and GRPO. Part 8 handles RLHF and RLAIF. Part 9 covers reasoning optimization, including distillation and MCTS. Part 10 extends to model optimization topics like quantization and gradient checkpointing. Part 11 is an appendix with references. This is a broad curriculum, not a deep dive into any single algorithm. The organization mirrors a textbook, which makes sense given the companion book.
Getting Access: No Installation, Just Browsing
There is no command to run. You clone the repository or browse it on GitHub. The README's table of contents links to an anchored header for each diagram. The reinforcement learning algorithm map is a PDF file named 强化学习算法图谱 (rl-algo-map).pdf. The repository also includes an English README at src/README_EN.md, suggesting the author intends it for an international audience. The default branch is master. The last push was in September 2026, but there are no releases. The license is listed as NOASSERTION, meaning GitHub did not identify a standard license, although a LICENSE file sits at the root. That file is worth reading before reusing the images.
The Missing Software: No Code, No Verification
The repository is purely visual. The README describes no implementation of any algorithm, although GitHub lists Python as the primary language. You cannot test or run anything. The diagrams are static explanations. That is fine for learning, but it means the repository cannot serve as a reference for exact mathematical formulations or implementation details. The author relies on the companion book for detailed interpretation. If you need to verify a formula or understand a subtle point, you must go to the original literature. The diagrams are a starting point, not an authoritative source.
Licensing and Reuse: A Red Flag for Adopters
The license field says NOASSERTION, so GitHub could not match the repository to a standard license like MIT or Apache 2.0, even though a LICENSE file is present at the root. Read that file to learn the reuse terms. The README includes a BibTeX entry and citation format, which suggests the author wants academic citation. But citation is not a substitute for a license. If you plan to use these diagrams in a course, a blog, or a commercial product, check the LICENSE file first. The author also requests stars as encouragement, which is a common but not meaningful quality signal.
A Real Alternative: Textbook Diagrams and Interactive Visualizations
If you need visual explanations of LLM and RL concepts, there are alternatives. One is the original papers themselves, which include figures for PPO, DPO, and RLHF. Another is interactive visualization projects, which let you step through a model's data flow. The difference in approach is significant. LLM-RL-Visualized gives you a complete atlas of static diagrams, useful for quick reference and for building a mental map. Interactive tools let you see the mechanism in motion, which can be more effective for understanding a process like attention or policy gradient updates. The trade-off is breadth versus depth. This repository covers far more topics than any single interactive tutorial, but each diagram is a snapshot, not an animation.
Editorial conclusion
Adopt this repository if you are a student, educator, or practitioner who needs a broad visual survey of LLM and RL concepts, especially if you read Chinese and want diagrams that pair with a structured textbook. Do not use it as a reference for implementation details, because the diagrams are pedagogical illustrations, not engineering blueprints. Before relying on any figure, verify the underlying algorithm against primary sources, since the diagrams are illustrations, not implementations. If you need interactive or executable examples, look elsewhere. The repository's value is its breadth and its integration with the book; treat it as a study aid, not a specification.
Frequently asked questions
What is inside the LLM-RL-Visualized repository?
More than 100 original architecture maps for large language models and reinforcement learning, with the contents split into eleven parts covering LLM and VLM foundations, SFT, DPO, training-free techniques, RL basics, policy optimisation, RLHF and RLAIF, reasoning, and an appendix.
Does LLM-RL-Visualized ship anything you can install or run?
No. The root has no package manifest and no install command, only markdown indexes, the images_chinese and images_english directories, and two PDF maps. Clicking an image opens the high resolution version, and .svg files can be zoomed and have their text selected.
Which training algorithms does LLM-RL-Visualized cover?
The contents name RL, RLHF, GRPO, DPO, SFT and chain of thought distillation, along with PPO-Clip, TRPO, GAE, DQN, DDPG, LoRA, Prefix-Tuning, RAG and function calling.
Is there an English version of LLM-RL-Visualized?
Yes. The top of the README links to ./src/README_EN.md next to ./README.md, and the figures are held in separate images_chinese and images_english directories.
How do I cite a diagram from LLM-RL-Visualized?
The appendix part of the contents carries a citation format page, a BibTeX page and a page of book references. The licence field for the project reads NOASSERTION, so check the LICENSE file at the root before reusing a figure.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/changyeyu-llm-rl-visualized)Star history chart for your README
[](https://hysenlabs.com/projects/changyeyu-llm-rl-visualized)Was this useful?