All-in-RAG: A Structured, Hands-On Curriculum for Building Production RAG Systems
Practical LLM application development, part one: a full-stack guide to RAG technology. Read online: https://datawhalechina.github.io/all-in-rag/
At a glance
- What is it?
- Datawhale's All-in-RAG is a Chinese-language, chapter-based tutorial that walks Python developers from basic retrieval-augmented generation concepts through multimodal indexing, hybrid search, and a full graph-RAG project. Its strength is the scaffolded path from theory to a deployable codebase, but its fast-moving repository and optional chapters demand careful version pinning.
- Who is it for?
- Adopt All-in-RAG if you are a Python developer who wants a guided, project-based path from RAG fundamentals to a working system, especially if you read Chinese and are willing to run Docker and manage vector databases like Milvus. Skip it if you need a production framework or an English-first resource, or if you prefer a single maintained library over a tutorial that spans multiple tools.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 46 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
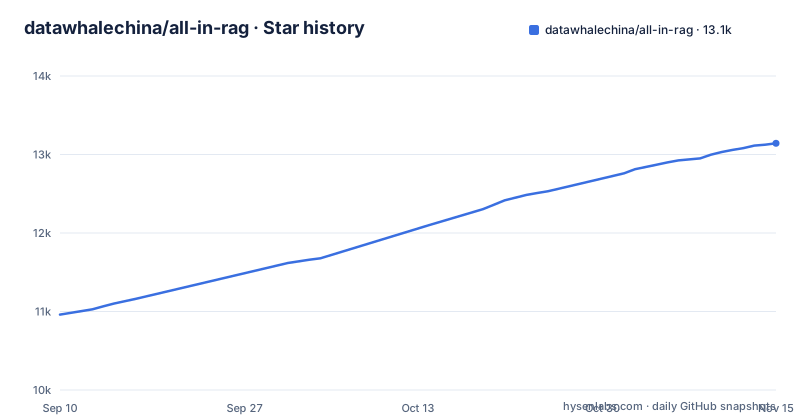
- datawhalechina/all-in-rag13,143 ★ · +2,182
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| datawhalechina/all-in-rag | 11k | 13.1k |
2,182 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What All-in-RAG Actually Delivers
All-in-RAG is not a software library. It is a structured, open-source tutorial repository from Datawhale, a Chinese AI education community, aimed at developers who want to build retrieval-augmented generation applications with large language models. The README describes it as a "full-stack guide" covering theory, practice, and engineering. The content is organized into ten chapters plus an extra-chapter section, with each chapter containing multiple markdown documents that include code examples. The target audience is explicit: developers with basic Python skills, some Docker familiarity, and a willingness to work on the Linux command line. The repository also assumes a basic understanding of LLM concepts, though the README marks that as recommended rather than required. The project's core value is its pedagogical structure, which moves from a simple four-step RAG implementation in chapter one to advanced topics like multimodal embeddings and graph-based RAG in later chapters.
The Chapter-by-Chapter Path from Basics to Graph RAG
The curriculum is the product. Chapter one introduces RAG and walks through a minimal setup, including a virtual environment guide. Chapter two covers data loading and text chunking, the often-underestimated preprocessing stage. Chapter three moves into indexing: vector embeddings, multimodal embeddings, vector databases, a hands-on Milvus practice, and index optimization. Chapter four tackles retrieval improvements: hybrid search that fuses dense and sparse vectors, query construction, Text2SQL, query rewriting, and advanced retrieval techniques. Chapter five covers formatted generation, and chapter six explains system evaluation methodologies and common tools. Chapter seven is a short extension on knowledge-graph-based RAG. Chapters eight and nine are the practical core: chapter eight builds a complete RAG application from environment setup to system integration, while chapter nine, marked as optional, redesigns that project with a graph RAG architecture, including graph data modeling and intelligent query routing. Chapter ten is listed as planned, so the path ends with the optional graph project. This structure is a genuine ladder, not a collection of unrelated snippets.
How the Material Is Organized and What You Run
Each chapter lives in the docs directory as a set of markdown files. For example, chapter one contains files named 01_RAG_intro.md, 02_preparation.md, and 03_get_start_rag.md. The README links to these files directly, and the full rendered version is available at datawhalechina.github.io/all-in-rag. The repository also includes an English README, but the chapter content itself is in Chinese. To work through the material, you need basic Python skills, plus Docker for services like Milvus and Neo4j. The extra chapters include a multimodal embedding practice with Jina v5-omni. The README does not provide a single install command or a requirements.txt in the top-level description, so you must follow each chapter's instructions. The extra-chapter section includes a Neo4j simple application and a multimodal embedding practice, both contributed by community members, which suggests the material is modular and extensible.
Real Limitations: Language, Version Drift, and Optional Gaps
The most obvious limitation is language. The README offers an English version, but the detailed chapter files are in Chinese, which narrows the audience. A second limitation is version drift. The repository was last pushed in September 2026, and the topics span fast-moving tools like Milvus, Neo4j and multiple embedding models. The README does not pin exact versions for these dependencies, so code from an earlier chapter may break if you use a newer release. The repository has no recent releases listed, which means you cannot rely on tagged stable snapshots. A third limitation is incompleteness: chapter ten is planned. The graph RAG project in chapter nine is optional, so a reader who finishes chapter eight may miss the most advanced material unless they choose to continue. Finally, the tutorial is not a turnkey framework. It teaches you how to assemble components, but you will still need to adapt the code to your own data and infrastructure.
Why It Stands Apart from Typical RAG Tutorials
Many RAG tutorials are either a single blog post or a collection of unrelated examples. All-in-RAG is different because it sequences topics into a coherent curriculum with a clear progression: start with a simple retrieval loop, then refine each stage, then build a full application, then rebuild it with a graph architecture. The inclusion of multimodal embeddings and a dedicated Milvus practice is also notable, because most introductory material stops at text-only vector search. The project's emphasis on evaluation in chapter six is another differentiator; it treats measurement as a core part of development, not an afterthought. The README's promise of "production-ready" engineering practices is supported by chapters on index optimization and system evaluation, though the actual production readiness depends on how you deploy the resulting code. The project also encourages community contributions through an extra-chapter section, which can keep the content fresh but also introduces variability in quality and style.
A Real Alternative: LangChain or LlamaIndex Documentation
If you want a more stable, English-language reference, the official documentation for LangChain or LlamaIndex is a practical alternative. Both projects provide tutorials, API references, and integration guides that cover many of the same topics: document loaders, text splitters, vector stores, and retrieval chains. The key difference is approach. LangChain and LlamaIndex are frameworks that you use to build applications, so their documentation is organized around components and APIs. All-in-RAG is a curriculum that teaches you how to think about the RAG pipeline, and it uses multiple frameworks and tools together. If you already know the concepts and need a specific API reference, the official docs are more direct. If you are new to RAG and want a guided path with worked examples, All-in-RAG provides a structure that framework docs lack. The trade-off is that All-in-RAG may fall behind the official docs when a library changes its interface, so you should cross-check any code you plan to reuse.
Maintenance, Licensing, and Upgrade Cost
The README states the work is licensed under the Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International licence (CC BY-NC-SA 4.0), so check its non-commercial terms before using the material in a product. The last push was September 2026, indicating active maintenance, but the absence of tagged releases means you cannot easily track changes. The upgrade cost for a learner is moderate: because the tutorial spans multiple libraries, you may need to update code as each library evolves. For a maintainer of a derived project, the cost is higher because you would need to port changes from a moving target. The community contribution model via extra chapters adds content but also increases the need to review code for quality and consistency. The project's homepage is a GitHub Pages site, which is easy to deploy, but the content is markdown, so you would need to convert it if you want a different format.
Editorial conclusion
Adopt All-in-RAG if you are a Python developer who wants a guided, project-based path from RAG fundamentals to a working system, especially if you read Chinese and are willing to run Docker and manage vector databases like Milvus. Skip it if you need a production framework or an English-first resource, or if you prefer a single maintained library over a tutorial that spans multiple tools. Before starting, verify that the chapter code matches the current versions of the libraries and embedding models it uses, because the repository is updated frequently and optional chapters are still evolving.
Frequently asked questions
What does RAG actually mean?
In this project RAG means retrieval-augmented generation, and the guide treats it as a full stack rather than a single technique: core concepts, data loading and cleaning, text chunking, vector and multimodal embedding, vector databases, hybrid retrieval, query construction, Text2SQL, formatted generation, and system evaluation with common tools and metrics.
Why is RAG outdated?
The README argues the opposite, treating RAG as a core technology for building intelligent question answering and knowledge retrieval systems as large models advanced. Its stated gap is the tutorials rather than the technique, which it describes as scattered and lacking a systematic learning path.
Is ChatGPT a RAG?
The guide does not analyze specific products. Its scope is building retrieval-augmented systems yourself, across embedding, hybrid retrieval, query rewriting and dispatch, Text2SQL, formatted generation and evaluation, and the audience listed is developers, AI engineers, product developers and researchers.
What is RAG slang for?
The README never uses the term as slang. It expands RAG as 检索增强生成, retrieval-augmented generation, and that expansion is the subtitle of the guide, which is also published in English as README_en.md and readable online at the project homepage.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/datawhalechina-all-in-rag)Star history chart for your README
[](https://hysenlabs.com/projects/datawhalechina-all-in-rag)Was this useful?