MOSS-TTS-Nano and the case for a 100M-parameter autoregressive TTS model
A 100M-parameter multilingual TTS model for real-time CPU inference, voice cloning, and 48 kHz stereo generation
At a glance
- What is it?
- MOSS-TTS-Nano is a 0.1B-parameter multilingual TTS model built for streaming on CPU, with a 48 kHz stereo output and voice cloning. Its two dependency lists, requirements.txt and pyproject.toml, disagree, which is the first thing an integrator will hit.
- Who is it for?
- Adopt MOSS-TTS-Nano if you need streaming, voice-cloned speech on a CPU or on Android and can live with exact-pinned dependencies plus a checkpoint and tokenizer download. Skip it if you need a tagged release, a container image, or a mono output path that does not need resampling.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 69 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
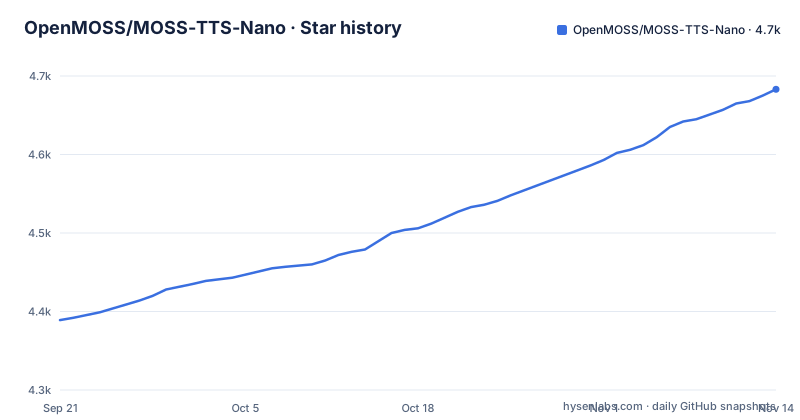
- OpenMOSS/MOSS-TTS-Nano4,683 ★ · +294
| Repository | 2026-09-21 | 2026-11-14 |
|---|---|---|
| OpenMOSS/MOSS-TTS-Nano | 4.4k | 4.7k |
294 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The 0.1B ceiling is the whole design brief
MOSS-TTS-Nano from MOSI.AI and the OpenMOSS team targets a narrow slice of text to speech: speech that starts playing before the sentence is finished, on hardware that has no GPU. At 0.1B parameters it fits the kind of machine that runs a local demo, a small FastAPI service or a browser extension, not a research cluster. The stated audience is therefore an integrator rather than a research lab, someone wiring a reading feature into a product and needing a short time to first audio.
The output format is the other decision that shapes everything downstream. The model is native 48 kHz, 2-channel audio, so files land as stereo rather than the mono most small TTS systems emit. If your pipeline assumes mono, this is where the surprises start, and it is worth settling before you write any glue code.
Coverage is broad for a model this size: the language table lists 20 entries starting with Chinese (zh), English (en), German (de), Spanish (es) and French. Long input is handled by automatic chunked voice cloning, which matters when a single paragraph is the unit of work rather than a single sentence.
Audio Tokenizer plus LLM, with the tokenizer shipping as a second model
The architecture is pure autoregressive: an audio tokenizer turns sound into discrete tokens, an LLM generates those tokens, and a decoder gives you a waveform. Nothing about this is a duration predictor or a vocoder bolted onto a mel spectrogram, and that is why the token vocabulary and its tokenizer weights matter as much as the LLM weights.
That is visible in how the weights are distributed. The main checkpoint sits on Hugging Face under OpenMOSS-Team, and the audio side is a separate model, MOSS-Audio-Tokenizer-Nano, with its own repository and its own evaluation section comparing reconstruction quality on speech, audio and music benchmarks. So the download you need for voice cloning is not one file. It is a checkpoint plus a tokenizer, and the tokenizer is the component whose reconstruction quality sets the ceiling on everything you can hear.
Streaming inference is claimed as a property of the pipeline rather than a wrapper script: low realtime latency and fast first audio, with generation said to run on a 4-core CPU. The repository layout backs the terminal and web paths directly. infer.py is the script path, app.py serves a local web demo, and both have ONNX twins named infer_onnx.py and app_onnx.py.
requirements.txt and pyproject.toml name different dependency sets
Two installation surfaces ship in the repository and they are not identical. pyproject.toml drives the packaged install and pins torch, torchaudio, transformers, onnxruntime, fastapi, uvicorn, sentencepiece and numpy. requirements.txt carries the same core plus WeTextProcessing>=1.0.4.1 and soundfile, which the packaged metadata never declares.
That gap matters because the repository also ships text_normalization_pipeline.py and a standalone single-script normalizer at the top level, so text normalization is part of the shipped surface rather than an afterthought. An install that goes through the packaged metadata can leave you with the normalizer modules present and the normalizer dependency missing.
The core ML pins are exact, not floors. torch==2.7.0 and torchaudio==2.7.0 alongside transformers==4.57.1 mean you inherit a working combination chosen by the authors and inherit its constraints too, since Python 3.10 or newer is required by pyproject.toml. Versioning is thin: pyproject.toml reads 0.1.0, the licence file at the root is Apache-2.0, and no GitHub release tags a build.
First run: the scripts the README points at, then the packaged CLI
Clone the repository and install from the requirements file, which is the list that includes the normalizer and audio I/O packages:
numpy>=1.24
fastapi>=0.110.0
python-multipart>=0.0.9
sentencepiece>=0.1.99
torch==2.7.0
torchaudio==2.7.0
transformers==4.57.1
uvicorn>=0.29.0
WeTextProcessing>=1.0.4.1
soundfile
onnxruntime>=1.20.0
For a first synthesis, the two entry points are the scripts, one for the terminal and one for a browser:
python infer.py
python app.py
Running app.py gives you a local web demo through FastAPI and uvicorn, with python-multipart in the dependency list for uploads such as a reference clip.
Installing the package itself puts a single console entry point on your PATH. The entry point is declared in pyproject.toml as:
[project.scripts]
moss-tts-nano = "moss_tts_nano.cli:main"
That gives two subcommands, generation and serving:
moss-tts-nano generate
moss-tts-nano serve
The README's quickstart sections are where the per-flag detail lives; the console script and the two scripts cover the whole documented first-run surface.
The ONNX path drops PyTorch, but the install keeps installing it
The second deployment route is the ONNX build, published as MOSS-TTS-Nano-100M-ONNX and MOSS-Audio-Tokenizer-Nano-ONNX on Hugging Face. Its stated purpose is to keep the full voice cloning workflow while removing the PyTorch dependency during inference, and the reported figure is nearly 2x the processing efficiency of the original version, running on a single CPU core of a MacBook Air M4.
The catch sits one level up. The April announcement says PyTorch is gone at inference, yet requirements.txt and pyproject.toml both still pin torch==2.7.0 and torchaudio==2.7.0 for the project as a whole. The torch-free promise belongs to the ONNX runtime path, not to a lighter pip install of the repository.
The code confirms the split. onnx_tts_runtime.py and ort_cpu_runtime.py sit alongside the PyTorch runtime modules, and examples/android_onnx_runtime/ shows the intended mobile target. If you deploy to a device where the torch dependency is the problem you are trying to solve, the ONNX weights are the answer, and the top-level dependency list is not.
Where this setup breaks down: containers, rollbacks, chunked prosody
No Dockerfile exists at the repository root, so the container story for moss-tts-nano on a server has to be built by you, and you inherit the full torch pin in the image unless you construct the environment around the ONNX runtime instead.
Two more boundaries are worth knowing. The tokenizer is a separate model with its own weights.
For long input the project handles chunking itself, which is convenient until you need one continuous prosody contour across a whole chapter. The README states that long text is supported with automatic chunked voice cloning.
Choosing between the two runtimes, and against the wider MOSS-TTS family
The real alternative inside this project is the PyTorch path itself. infer.py and app.py run the checkpoint through torch and transformers, which is the path to take when you want the shortest route from clone to audio and the tokenizer is the same file you already have. The ONNX path trades the PyTorch conveniences for a torch-free inference graph and a mobile target, at the cost of a separate weights download.
Outside the repository, the tokenizer is the comparison point. MOSS-Audio-Tokenizer-Nano is evaluated against other open-source tokenizers on LibriSpeech speech metrics, and the README carries reconstruction comparisons on speech, audio and music. Read that table first, because a stronger decoder cannot rescue a tokenizer that loses detail at encode time.
Surrounding projects widen the picture rather than compete: MOSS-TTS-Nano-Reader runs the model in the browser as an extension with no local inference service, mlx-audio gained support for MOSS-TTS, MOSS-TTS-Nano and MOSS-Audio-Tokenizer in May 2026, and the studio.mosi.cn endpoints host an online demo and hosted documentation. Work on MOSS-TTS 2.0 was signalled in April 2026 through a public feedback form.
Editorial conclusion
Adopt MOSS-TTS-Nano if you need streaming, voice-cloned speech on a CPU or on Android and can live with exact-pinned dependencies plus a checkpoint and tokenizer download. Skip it if you need a tagged release, a container image, or a mono output path that does not need resampling. Before anything else, install from requirements.txt and confirm the text normalization packages resolve, because pyproject.toml and requirements.txt declare different dependency sets, and a packaged install can leave the normalizer modules in place with nothing to import.
Frequently asked questions
What is MOSS-TTS-Nano and how big is the model?
It is an open-source multilingual speech generation model from MOSI.AI and the OpenMOSS team with 0.1B parameters, designed for realtime generation on CPU. It outputs native 48 kHz, 2-channel audio.
How do you run MOSS-TTS-Nano voice cloning locally?
The README gives a terminal script and a local web demo, run as python infer.py and python app.py after installing from requirements.txt. Long input is handled with automatic chunked voice cloning.
Does MOSS-TTS-Nano support ONNX inference without PyTorch?
Yes. The ONNX CPU version is backed by the MOSS-TTS-Nano-100M-ONNX and MOSS-Audio-Tokenizer-Nano-ONNX Hugging Face repositories and removes the PyTorch dependency during inference, with an Android ONNX Runtime example under examples/android_onnx_runtime.
What languages does MOSS-TTS-Nano support?
The language table lists 20 languages, starting with Chinese (zh), English (en), German (de), Spanish (es) and French. The README describes support as Chinese, English and more.
What licence is MOSS-TTS-Nano released under?
Apache-2.0, with the LICENSE file at the repository root.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/openmoss-moss-tts-nano)Star history chart for your README
[](https://hysenlabs.com/projects/openmoss-moss-tts-nano)Was this useful?