Qwen3-ASR: multilingual speech recognition and forced alignment
Qwen3-ASR is an open-source series of ASR models developed by the Qwen team at Alibaba Cloud, supporting stable multilingual speech/music/song recognition, language detection and timestamp prediction.
At a glance
- What is it?
- Qwen3-ASR is a family of speech recognition models with 0.6B and 1.7B variants, plus a separate 0.6B forced aligner. The project documents Transformers and vLLM inference, streaming constraints and benchmark results.
- Who is it for?
- Qwen3-ASR is worth evaluating when multilingual transcription or text-to-audio alignment fits your workload. Select a model and backend for your hardware, check the current model and package licenses and dependencies, and measure recognition accuracy, latency and memory on representative audio.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 142 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
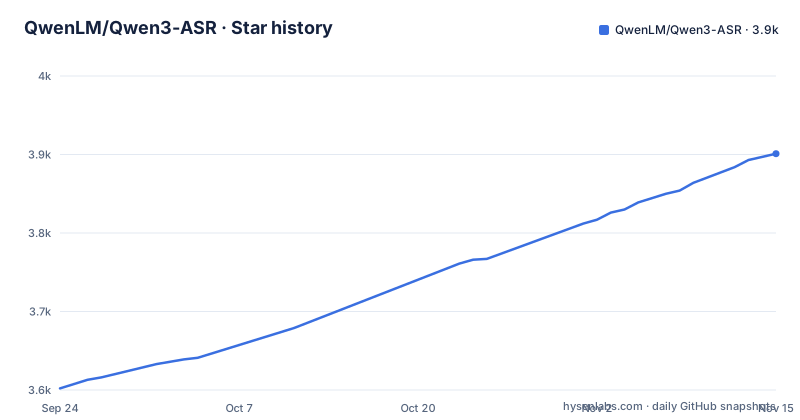
- QwenLM/Qwen3-ASR3,901 ★ · +299
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| QwenLM/Qwen3-ASR | 3.6k | 3.9k |
299 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Model family and language coverage
The Qwen team describes two recognition models, Qwen3-ASR-0.6B and Qwen3-ASR-1.7B, and a separate Qwen3-ForcedAligner-0.6B. The recognition models support multilingual speech recognition and language identification; the project lists 30 languages and 22 Chinese dialect categories. Coverage does not imply equal accuracy across languages, accents or recording conditions.
The forced aligner accepts audio and corresponding text to produce timestamps. It is a separate model and its documented language coverage is narrower than the recognizers'.
Installing and choosing a backend
The README documents a Python package with Transformers and vLLM backends. Install the package and consult the current repository instructions for backend-specific dependencies; the vLLM backend is an optional extra. Exact dependency pins in a given release can conflict with an existing environment, so use an isolated environment and inspect the version you install.
GPU, CUDA, precision and optional acceleration requirements vary with the chosen backend and version. Test the target hardware rather than assuming a particular throughput or memory footprint.
Transcribing audio
The documented Transformers example loads `Qwen3ASRModel.from_pretrained` with a model identifier and calls `transcribe`. Inputs can include a local file, URL, encoded data or an array with its sample rate. A language can be specified or detected automatically. The README also provides batch and vLLM examples.
Use audio you are authorized to process, review how URLs and model weights are fetched, and validate output before using transcripts in decisions where errors matter.
Streaming and timestamps
The README describes offline and streaming recognition. Its documented streaming implementation currently uses the vLLM backend and does not support batch inference or returning timestamps in streaming mode. For supported offline timestamp workflows, the examples use the separate forced aligner.
Streaming responsiveness and accuracy depend on chunking, audio and hardware; benchmark the actual deployment and consult current documentation for changes.
Downloading models for offline use
The README provides ModelScope and Hugging Face download examples for environments that need local model files. Download the selected checkpoint and tokenizer or processor assets in advance, record the revision, and point the documented loader at the local directory. Check the current CLI syntax for the installed tool rather than relying on a truncated command.
Verify storage capacity, file integrity and licensing for each artifact; a cached package alone does not necessarily include model weights.
Forced alignment and language coverage
The forced aligner takes a text–speech pair and returns word- or character-level timestamps for its documented languages. Alignment assumes an appropriate transcript; incorrect or missing text can produce misleading timestamps. The project lists a maximum audio length per input, so segment longer recordings according to the current model documentation.
Language and dialect labels in model tables describe the authors' supported categories; they are not evidence of equivalent performance on every variety or on every song.
Reading the reported benchmarks
The README includes author-reported public and internal benchmark tables, including comparisons with Whisper large-v3 and other systems, as well as language identification and streaming results. Scores differ by dataset and inference mode. Check the evaluation setup, language composition and metric definitions, and note that internal datasets may not be independently reproducible.
Run a representative evaluation for your own languages, speakers and noise conditions; compare word error rate alongside latency, resource use and timestamp quality.
Deployment and operational considerations
The repository contains examples, deployment and fine-tuning material and links to model cards, a paper and hosted demos. Consult those sources for the exact checkpoint and revision in use; repository owner redirects or package metadata alone do not establish a broken link or missing asset.
If exposing a demo or inference server, restrict network access and handle recordings and transcripts as sensitive data. Verify model downloads, dependency provenance and the runtime's current security updates before deployment.
Editorial conclusion
Qwen3-ASR is worth evaluating when multilingual transcription or text-to-audio alignment fits your workload. Select a model and backend for your hardware, check the current model and package licenses and dependencies, and measure recognition accuracy, latency and memory on representative audio. Published benchmarks are useful context, not a guarantee of performance on your data.
Frequently asked questions
What is Qwen 3 ASR?
It is a family from the Qwen team at Alibaba Cloud: Qwen3-ASR-1.7B and Qwen3-ASR-0.6B, which do language identification and speech recognition across 30 languages and 22 Chinese dialects, and Qwen3-ForcedAligner-0.6B, a non-autoregressive model that predicts timestamps for units within up to 5 minutes of speech in 11 languages. The Apache-2.0 release ships a qwen-asr Python package, not GitHub releases.
how to use qwen3 asr
The project documents installing `qwen-asr`, loading a checkpoint through `Qwen3ASRModel.from_pretrained` for Transformers, and using the vLLM extra for its vLLM backend. Follow the current README and model card for supported versions, hardware and offline downloads.
is qwen3 asr open source
The repository is Apache-2.0 licensed, and the project publishes model weights and inference code. Check the specific model card and the licenses of dependencies before use or redistribution.
What are the key differences between Qwen3-ASR and Whisper Large V3?
The project README includes author-reported word-error-rate tables comparing Qwen3-ASR with Whisper large-v3 on several public and internal datasets. Results vary by dataset; compare the evaluation conditions and test both on representative audio before choosing.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/qwenlm-qwen3-asr)Star history chart for your README
[](https://hysenlabs.com/projects/qwenlm-qwen3-asr)Was this useful?