MLAlgorithms keeps its implementations in mla/, but its packaging metadata points at a different repository and its dependency floors date from the numpy 1.11 era
Minimal and clean examples of machine learning algorithms implementations
At a glance
- What is it?
- rushter/MLAlgorithms is an MIT-licensed set of from-scratch machine learning implementations in Python using numpy, scipy and autograd, with 14 algorithm families and 16 runnable example scripts. It is built to be read rather than depended on: the package version is a frozen 0.0.1, requirements.txt sets lower bounds with no ceilings, and there is no top-level tests directory.
- Who is it for?
- Read this repository when you want to see how an algorithm is written out from scratch, and copy the file you need into your own project instead of adding mla as a dependency.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 47 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
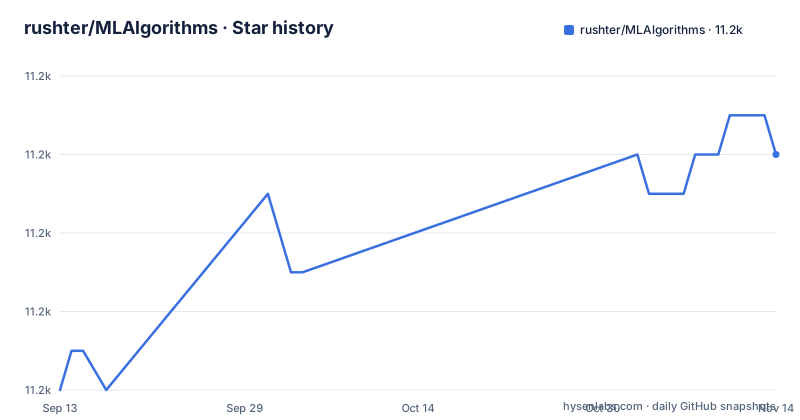
- rushter/MLAlgorithms11,182 ★ · +6
| Repository | 2026-09-13 | 2026-11-14 |
|---|---|---|
| rushter/MLAlgorithms | 11.2k | 11.2k |
6 Stars in the last 62 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
setup.py names the package mla and sends both URLs to rushter/mla
The packaging metadata and the repository are not the same place. setup() sets name='mla', url='https://github.com/rushter/mla', and download_url built as 'https://github.com/rushter/mla/tarball/' plus the version, while the clone instructions in the documentation point at rushter/MLAlgorithms. The author field says Artem Golubin with author_email [email protected], and the long description is read straight out of README.md at build time, so the package description on any index is this same file. Consequence: anything that trusts package metadata, an index page, a dependency resolver cache, or a download link, is being handed a repository path that is not the one you cloned. Use the clone URL from the documentation and ignore the fields in setup.py when you want to find the source.
The version is a literal 0.0.1 and no release has ever been published
The version is not derived from tags or history. setup.py sets __version__ = '0.0.1' as a constant, and the repository has no GitHub releases at all, so there is nothing else that could ever produce a different number. The last push to master is 2026-09-29, which tells you work is landing, but it tells you nothing about which code you would get from an install. Consequence for a reader: you cannot pin this project, you cannot tell whether a bug you fixed is fixed for anyone else, and a version comparison against any other checkout is meaningless. If you need a stable point in history, choose a commit hash yourself and record it next to the file you copied.
numpy and scipy get two different floors, and install_requires is parsed out of a text file
Two dependency declarations disagree inside one repository. setup_requires lists numpy>=1.10 and scipy>=0.17, while requirements.txt asks for numpy>=1.11.1 and scipy>=0.18.0. Which one binds depends on whether your tooling still honors setup_requires at all, since the modern path resolves install_requires only. The install_requires list is not typed out, it is generated: setup.py reads requirements.txt, splits it on newlines, keeps every line that does not contain git+ as an install requirement, and rewrites the git+ lines into dependency_links. Consequence: if you add a git+ dependency for a local experiment, it is silently converted into a link that your installer will not fetch, and the package imports something that is not there. Read requirements.txt directly rather than trusting the derived list.
Every requirement is a floor with no ceiling, and the floors are from the numpy 1.11 era
requirements.txt names eight packages: tqdm, matplotlib>=1.5.1, numpy>=1.11.1, scikit-learn>=0.18, scipy>=0.18.0, seaborn>=0.7.1, autograd>=1.1.7, and gym with no floor at all. No line carries an upper bound, so a fresh install resolves to whatever is newest at that moment, which is not the stack these files were written against. The stated design is that everything is implemented with numpy, scipy and autograd, yet scikit-learn, seaborn, matplotlib and gym sit in the same requirement list. Consequence: the first thing that breaks after a major library release is an import or a renamed function inside an example, and nothing in the repository declares the version at which that starts.
find_packages excludes docs and tests, and neither exists in the tree
The package build calls find_packages(exclude=['docs', 'tests*']) and sets include_package_data=True, alongside a MANIFEST.in at the root. Look at what is actually there: .github/, .gitignore, AUTHORS, Dockerfile, LICENSE, MANIFEST.in, README.md, examples/, mla/, requirements.txt, setup.cfg and setup.py. No docs directory and no tests directory. So the exclude list guards against nothing, and, more importantly, there is no top-level tests directory. Consequence: nothing verifies that k-means, the SVM kernels, t-SNE or the neural networks still behave after you upgrade a dependency, and a pull request cannot be gated by a test run because there is nothing to run. That exclusion pattern also reads as a leftover from a template rather than a statement about this repository.
examples/ is a package, so it ships with mla and drags the whole plotting stack along
examples/ contains an __init__.py and sixteen runnable scripts, including gaussian_mixture.py, gbm.py, kmeans.py, linear_models.py, naive_bayes.py, nearest_neighbors.py, nnet_convnet_mnist.py, nnet_mlp.py, nnet_rnn_binary_add.py, nnet_rnn_text_generation.py, pca.py, random_forest.py, rbm.py, rl_deep_q_learning.py, svm.py and t-sne.py, and the exclusion list in setup.py does not name it. Because examples is a package and it is not excluded, an install of mla carries the example scripts with it. Consequence: someone who wants only the algorithm modules still gets scripts that may need the plotting and machine learning packages listed in requirements.txt, so the install and the import surface are both larger than the thing they asked for. Grabbing the single file you want from mla/ is the cheaper path.
FROM python:3 floats, and there is no .dockerignore in the tree
The container recipe is short. It starts FROM python:3, creates /var/app, sets it as the work directory, copies the whole tree in with COPY. /var/app, and runs pip install scipy numpy followed by pip install. . The documented container path is these commands:
cd MLAlgorithms
docker build -t mlalgorithms .
docker run --rm -it mlalgorithms bash
python -m examples.linear_models
The base image tag carries no version, so the interpreter your container runs is whatever python:3 resolved to on the build day, which means a build that worked last month is not the same build today. The root listing also has no .dockerignore, so COPY. pulls in your .git directory and anything else sitting in the checkout. One saving grace: the image installs with pip install ., so it avoids the legacy python setup.py develop that the local instructions use.
The no-install path still needs the eight dependencies, and two example names cannot be imported
The documentation offers a route that skips installation entirely:
cd MLAlgorithms
python -m examples.linear_models
Nothing precedes it, and the section title only promises to skip installation, not to skip dependencies, so a fresh clone fails at the import unless you have already installed numpy, scipy and the rest yourself. The module form also assumes you are in the repository root, since examples/ is resolved as a package. Then there is the naming: the implementation is mla/knn.py but the example is examples/nearest_neighbors.py, and the implementation is mla/tsne.py while the example is examples/t-sne.py, a filename with a hyphen in it. Consequence: example filenames do not always match the implementation names, so read the example list rather than guess filenames.
Editorial conclusion
Read this repository when you want to see how an algorithm is written out from scratch, and copy the file you need into your own project instead of adding mla as a dependency. Treat it as teaching material rather than as a library: the version is pinned at 0.0.1 with no release ever published, install_requires is generated by splitting requirements.txt on newlines, there is no top-level tests directory to catch a library API change, and the numeric floors go back to the numpy 1.11 era with nothing above them. Before you run anything, install the eight requirements yourself on the interpreter you actually use, and expect to patch deprecated numpy or scipy calls yourself when a recent version is what resolves.
Frequently asked questions
What are the main ML algorithms?
The repository implements linear and logistic regression, random forests, gradient boosting trees, support vector machines with linear, polynomial and RBF kernels, k-means, Gaussian mixture models, k-nearest neighbors, naive Bayes, PCA, factorization machines, restricted Boltzmann machines, t-SNE, deep Q learning, and neural networks covering MLP, CNN, RNN and LSTM. All of them are written in Python with numpy, scipy and autograd.
how to use ml algorithms
There are three documented routes. Install from a clone with git clone, cd, pip install scipy numpy and python setup.py develop. Run an example with no install using cd MLAlgorithms followed by python -m examples.linear_models. Or use the container: cd MLAlgorithms, docker build -t mlalgorithms ., docker run --rm -it mlalgorithms bash, then python -m examples.linear_models. All three require the packages in requirements.txt to be importable.
ml algorithms vs models
The repository does not draw that line. It calls itself a collection of minimal and clean implementations of machine learning algorithms, and states that it targets people who want to learn the internals of the algorithms or implement them from scratch, saying the code is easier to follow than optimized libraries. Each entry is an implementation file or package under mla/.
What are the 7 types of machine learning?
The repository does not organize itself by taxonomy, so you have to map that yourself. The implementation files sit as single modules such as mla/linear_models.py, mla/kmeans.py, mla/pca.py and mla/tsne.py, and as packages for mla/neuralnet, mla/svm, mla/rl and mla/ensemble.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/rushter-mlalgorithms)Star history chart for your README
[](https://hysenlabs.com/projects/rushter-mlalgorithms)Was this useful?