turbovec filters inside the SIMD kernel and skips the training phase
A vector index built on TurboQuant, written in Rust with Python bindings.
At a glance
- What is it?
- turbovec is a Rust vector index with Python bindings built on Google's TurboQuant, a data-oblivious quantiser with no separate training phase, so vectors are indexed as you add them. It searches the compressed vectors with agent-optimised SIMD kernels on ARM and x86, and the kernel skips whatever an allowlist filter excludes.
- Who is it for?
- turbovec fits a retrieval service that ingests continuously, filters by tenant or permission, and has to stay on one machine, which is exactly what the incremental sync and the in-kernel filtering are built for. It does not fit a static corpus you index once, because there is no training phase to tune and therefore nothing to gain from it, and quantization is lossy, so results are not exact float results.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 38 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
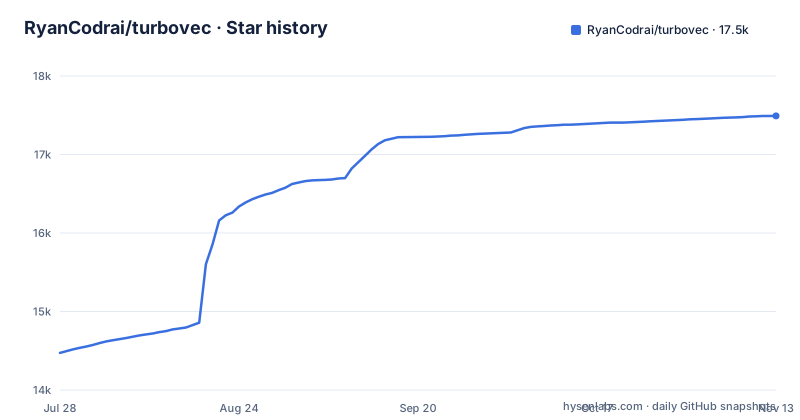
- RyanCodrai/turbovec17,492 ★ · +3,019
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| RyanCodrai/turbovec | 14.5k | 17.5k |
3,019 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
There is no training phase, so there is no stale codebook
The index is built on Google Research's TurboQuant algorithm, whose codebook comes from the maths rather than your data, so there is no separate training phase, and the consequences arrive before any tuning. Adding vectors indexes them. No train step, no parameter tuning, no rebuilds as the corpus grows. That removes the failure mode that dominates other quantised indexes, where a codebook was trained on the first batch and silently degrades as the distribution moves underneath it, and where the fix is a full rebuild at an awkward moment. What it gives up is the tuning knob itself. A data-oblivious quantiser has no parameters to fit, so there is nothing to search over and nothing to overfit, and the only decision you make up front is the width. The headline claim frames the result in the terms that follow from that: a ten million document corpus is 31 GB of RAM as float32 and 4 GB here. Installing it from Python is one command, and the first call constructs an index with a dimension and a bit width:
pip install turbovecfrom turbovec import TurboQuantIndex
index = TurboQuantIndex(dim=1536, bit_width=4)
index.add(vectors)
index.add(more_vectors)
scores, indices = index.search(query, k=10)The Rust crate installs with cargo add turbovec and takes the same two numbers, TurboQuantIndex::new(1536, 4). Vectors and queries have to be two-dimensional float32 arrays, and any other dtype is rejected rather than quietly converted, so an accidental float64 array fails at the call instead of costing you recall.
bit_width is the whole decision, and the two widths are not the same product
Every example constructs the index with bit_width=4, and the measured comparisons are reported separately for each width. Against FAISS IndexPQFastScan the README claims 4.4 times faster at 4-bit and 2.2 times at 2-bit, with 3.8 to 5.1 times and 1.8 to 2.5 times across the eight cells of each width on ARM and x86. The recall numbers are split the same way, and the split matters. On the OpenAI corpora at d=1536 and d=3072, turbovec beats FAISS at Recall@1 on three of four cells, by 1.0 to 2.5 points, and both always return the true nearest neighbour within the first 8 results. On GloVe at d=200 it is still ahead at Recall@1 at both widths, 0.860 against 0.842 at 4-bit and 0.572 against 0.565 at 2-bit. So the width that makes the library fast is not the width where it wins most clearly on quality, and that is the trade to make deliberately.
Filters run inside the kernel at 32-vector block granularity
This is the part that changes how a filtered search behaves. You can pass an id allowlist, or a slot bitmask, to search(), and the kernel honours it directly rather than the library fetching candidates and discarding them. The README says the kernel skips what the filter excludes, so a selective filter avoids scoring work instead of paying for it and throwing the answer away. It returns up to k results from the allowed set; the README example with three allowed ids returns shape (1, min(k, 3)). For a multi-tenant system or an ACL-filtered search, that is the difference between a filter that costs a constant factor and one that quietly costs you recall.
sync() writes the delta, write() writes the whole file, and the extensions differ
Two persistence models sit side by side, and they use different extensions. sync(path) persists only what changed since the last sync, with one fsync per call, crash-safe at any byte, so a removal or a small append costs milliseconds however large the index is. write() and load() remain for whole-file snapshots. The reason to care is that a service that ingests continuously and a batch job that snapshots an index want opposite things, and the incremental path is the one that makes an index of this size practical to keep current. The README examples save a TurboQuantIndex to index.tv.
IdMapIndex exists because a slot is not an identifier
The plain index returns positions in the index, which is fine until you delete something. IdMapIndex takes your own uint64 identifiers, so add_with_ids attaches them, search returns your ids rather than slot numbers, and remove is O(1) by id. The README pitches IdMapIndex for "ids that survive deletes", so slot positions your application stored from an earlier search are not a stable reference once you delete. The id-backed variant removes that class of bug by making the mapping explicit,. If your application is going to hold references to results across a delete, this is the class you want, and the cost is that you now own the identifier space.
Two crates, and a smoke test kept outside the workspace on purpose
The Cargo manifest is a workspace with two members, turbovec and turbovec-python, and one deliberate exclusion. examples/downstream-smoke is excluded, and the comment above it explains why: it is a standalone smoke test crate that lives outside the workspace on purpose so it must mimic a real downstream user of cargo add turbovec, with no inherited workspace settings and no shared lockfile. That is a small decision with a large payoff, because the bugs it catches are exactly the ones that only appear when a crate is consumed the way a stranger consumes it, and they never appear in a test run inside the workspace. The release profile is tuned the same way, with link-time optimisation on, a single codegen unit and opt-level 3. Around that sit benchmarks/, a deny.toml for dependency policy, a .claude directory, SECURITY.md and a changelog.
Four framework integrations swap the store, not the pipeline
The integration pages are written for people who already have a pipeline. Each one replaces a framework's own reference store rather than asking you to rewrite your chain: each framework's in-memory store, for LangChain, LlamaIndex, Haystack and Agno, each behind its own extra, turbovec[langchain], turbovec[llama-index], turbovec[haystack] and turbovec[agno]. The claim is the same public surface, the same persistence semantics and the same retriever and pipeline wiring, so the swap is an import change. Read that as what it is: the store you were using was a placeholder, and what you lose is whatever behaviour lived in it. One more detail from the Python section is worth carrying into any integration, which is that inputs must be two-dimensional float32 arrays and other dtypes are rejected rather than silently converted.
Editorial conclusion
turbovec fits a retrieval service that ingests continuously, filters by tenant or permission, and has to stay on one machine, which is exactly what the incremental sync and the in-kernel filtering are built for. It does not fit a static corpus you index once, because there is no training phase to tune and therefore nothing to gain from it, and quantization is lossy, so results are not exact float results. Before you adopt it, pick the bit width deliberately: 4-bit is 4.4 times FAISS FastScan and 7.8 times smaller than float32, while 2-bit is 2.2 times faster and 15.5 times smaller. Then decide whether you need IdMapIndex, which keys results by your own uint64 ids that survive deletes.
Frequently asked questions
What is Google's turbo quant?
TurboQuant is a Google Research algorithm whose codebook comes from the maths rather than your data, so there is no separate training phase. turbovec is an implementation of it as a Rust vector index with Python bindings, so vectors are indexed as they are added rather than after a training step.
how to use turbovec
Install it with pip install turbovec, then create an index with a dimension and a bit width, add your vectors, and call search with a query and a k. Persist with write for a whole-file snapshot or sync for a durable incremental save, and add an allowlist to search to restrict results to a candidate set.
what is turbovec
turbovec is a vector index written in Rust with Python bindings, built on the TurboQuant algorithm. It is distributed on PyPI and on crates.io, and searches the compressed vectors with agent-optimised SIMD kernels on ARM and x86.
what does turbovec do
It stores and searches dense vectors. Vectors are quantised and indexed as they are added, search returns scores and indices, and filtering by an id allowlist or a slot bitmask is applied inside the SIMD kernel, so a selective filter skips most of the scoring work instead of discarding results afterwards.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ryancodrai-turbovec)Star history chart for your README
[](https://hysenlabs.com/projects/ryancodrai-turbovec)Was this useful?