hunyuanimage-3.0: an 80 billion parameter model whose package declares no dependencies
HunyuanImage-3.0: A Powerful Native Multimodal Model for Image Generation
At a glance
- What is it?
- Tencent's HunyuanImage-3.0 is an autoregressive mixture of experts image model released in stages: weights and inference code first, then vLLM support, then an instruct checkpoint with reasoning, then a distilled one. The readme's open-source plan has one item unticked. The packaging around it has several more problems, and the licence is the one a user most needs to resolve.
- Who is it for?
- Use it if you want the autoregressive approach to image generation and can satisfy the environment yourself, since the requirements file deliberately leaves the framework out and asks you to install it separately. Three things to resolve first.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 145 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
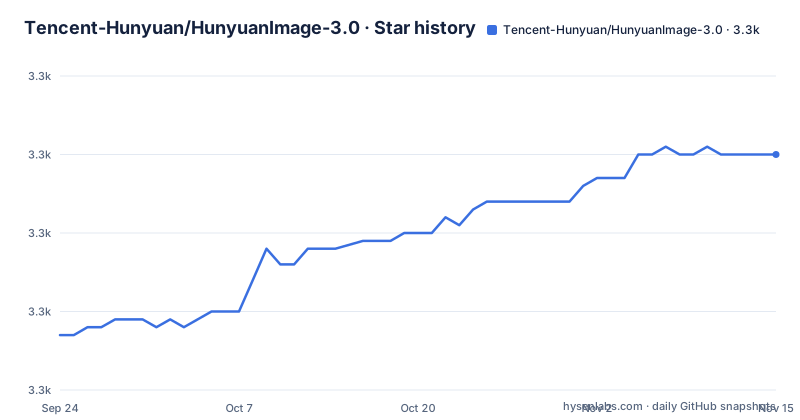
- Tencent-Hunyuan/HunyuanImage-3.03,300 ★ · +23
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| Tencent-Hunyuan/HunyuanImage-3.0 | 3.3k | 3.3k |
23 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Seven items in the open-source plan, six ticked, one not
The repository carries an open-source plan as a checklist, and it is the clearest statement of what has actually shipped.
Six items are ticked. Inference code. The main checkpoints. The instruct checkpoints, noted as being with reasoning. vLLM support. Distilled checkpoints. And image-to-image generation.
One is not ticked: multi-turn interaction.
That single open item is the boundary of the release as the project describes it. Everything the documentation demonstrates is single-turn, and the news entries match the checklist: inference code and weights in September 2025, the technical report the same day, vLLM acceleration in October, then the instruct and distilled checkpoints on the same day in January 2026 with a recommendation of eight sampling steps for the distilled one.
The naming is worth keeping straight, because the documentation is organised around three separate tracks: the base model for text-to-image, the instruct model for reasoning and editing, and the distilled instruct model for cheaper deployment. Two of the three are instruction-tuned and only one is distilled.
The package classifier says proprietary, the project metadata says nothing
The licence question in this repository is answered in three places and the three do not agree.
The project metadata records no licence at all. The package manifest's classifier list declares an Other/Proprietary License. And a licence file sits in the repository root, whose contents are not visible from here.
That combination is worth pausing on for an open weights release. A readme that says inference code and model weights are publicly available, with a technical report, a demo, and a checklist of released artefacts, reads as open source in the ordinary sense. The classifier says otherwise.
There is also no licence section in the readme, so a reader has no prose to consult and no statement about commercial use, redistribution, or the weights as opposed to the code.
This matters more here than in most repositories because the whole point of the release is that someone else runs the model on their own hardware. The difference between a permissive licence and a proprietary one determines whether that is a weekend project or a procurement conversation.
The declared dependency list is empty and the real one is read from a file
The most consequential defect in this repository is in the packaging, and it is quiet.
The declarative metadata declares its dependencies as an empty list, with a comment saying they will be read automatically from a requirements file. Nothing in the standard declarative format will do that.
The legacy build script does do it, by opening that requirements file, keeping every line that is not a comment, and handing the result to the installer as the requirement list. It wraps the read in a try block and prints a warning if the file is missing, then proceeds with whatever it got, which in that case is nothing.
Two properties follow. A build that runs somewhere other than the repository root reads nothing, because the path is relative, and succeeds with an empty list. And a build where the file simply is not present behaves the same way.
So the two things that make this project usable, the framework and the transformer stack, are only present if whoever installed it remembered to read the readme's first install step.
The framework is commented out of the requirements file
The install section's first command is a single line, and it is the thing the requirements file does not do for you:
pip install torch==2.8.0 torchvision==0.23.0 torchaudio==2.8.0 --index-url https://download.pytorch.org/whl/cu128The requirements file explains why: the framework is marked as needing separate installation, and the three lines for it are present but commented out, with the same command repeated above them as a comment.
The same pattern appears twice more in that file. A performance package is commented out with a note that it is recommended for up to three times faster inference. And the interactive demo's dependency is left active, which means a library install pulls in a web interface framework whether or not you want the demo.
There is a defensible reason for separating the framework: it needs a specific build for a specific CUDA version, and pinning it in a plain requirements file tends to fight with whatever else is installed. The cost is that the single most important dependency is the one a script has to fetch by hand.
Two build configurations, and a console script pointing outside the package
The repository ships both a declarative manifest and a legacy build script, and they duplicate the same metadata field by field: name, version, author, description, classifiers, and the Python floor.
That is workable as long as they are edited together, and it is the arrangement most projects move away from rather than towards.
The sharper problem is the console script. The manifest declares one entry point, named for the tool and pointing at a module that sits at the repository root rather than inside the package directory the build is configured to include.
So the installed package contains the library and not the module its own command is supposed to call. From a source checkout where the root happens to be importable it works, which is presumably how it is tested, and from a real installation it does not.
Package discovery is configured to include only the package directory and its subpackages, and to exclude cache and compiled artefacts. The demo scripts, the image generation script, and the helper scripts sit outside that boundary, which is the right call for the demo and the wrong one for a declared entry point.
One dependency has no version at all and one has only a floor
The core requirement block is eight entries, and the pinning style is not consistent across them.
Six are pinned exactly, to the patch: an array library, a numeric library, an imaging library, a diffusion library, a safe-tensors library, and a tokenizer library, plus the transformer stack with two extras attached.
Two are not. One is a logging library with a floor and no ceiling, so a future major release satisfies it. The other, the model hub client with a command line extra, carries no version constraint at all, so whatever the index serves is what installs.
That one matters more than it looks. The model hub is how the documented quick start obtains weights, and it is also the component whose breaking changes most often affect download and caching code. Everything else in the file is reproducible and that entry is not.
The file also opens with a blank line before its first comment, which is harmless, and closes with several blank lines after the demo entry.
Unquoted links in the badge block and a word split in a sentence
Two small things in the readme are worth recording because they are the kind of detail that makes a document feel unproofed.
The eight links in the centred block at the top, which point at the project site, three model pages on a model hub, the repository, a technical report, a social account, and an internal document, all have their addresses written without quotation marks. The paragraph below them, which links a chat group and a hosted chat page, quotes its addresses correctly.
Both forms work in most renderers. The unquoted form is not valid markup, so a stricter renderer will drop the link, and the difference between the two blocks is invisible until something renders them differently.
The other is in the features section, where a sentence about the model's reasoning contains the phrase split across two words as if a space had been inserted mid-word, in the middle of explaining that it interprets an input image and elaborates sparse prompts.
Neither matters. Both are the sort of thing that tells you which parts of the document were written quickly and which were revised, and in this readme the parts with typos are the parts making performance claims.
Editorial conclusion
Use it if you want the autoregressive approach to image generation and can satisfy the environment yourself, since the requirements file deliberately leaves the framework out and asks you to install it separately. Three things to resolve first. The package declares an empty dependency list and reads its real one from a file by relative path, so a plain install gives you nothing. The project's own classifier calls its licence proprietary while the metadata records none. And the one item left open in the open-source plan is multi-turn interaction, so do not plan around it.
Frequently asked questions
how to use hunyuan image 3.0
Install the framework yourself first, because the requirements file leaves it commented out with the install command repeated in a note. The repository then ships separate demo scripts for the instruct checkpoint and the distilled one, plus a text-to-image script, and documents a path that downloads weights and runs them through the transformer library, along with a browser demo for the interactive version.
is hunyuan image 3.0 open source
The readme is explicit about the boundary. Its open-source plan has seven items and six are ticked, covering inference code, checkpoints, the instruct checkpoint with reasoning, serving support, distilled checkpoints, and image-to-image generation. Multi-turn interaction is the single item left unticked. The project's licence field records nothing while its own package classifier declares a proprietary licence.
is hunyuan image 3.0 free
The repository says nothing about cost. What it does say about terms is indirect: the licence field on the project is unasserted, the package classifier declares an Other/Proprietary License, and a licence file sits in the repository root without being quoted in the readme. Anyone who needs a definitive answer has to read that file rather than the documentation.
what is hunyuan image 3.0
It is a multimodal image generation model that handles understanding and generation inside one autoregressive framework, which the readme says moves beyond the diffusion-transformer approach used by comparable models. It is a mixture of experts with 64 experts, 80 billion total parameters, and 13 billion active per token, released as a base checkpoint, an instruct checkpoint with reasoning, and a distilled instruct checkpoint.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tencent-hunyuan-hunyuanimage-3-0)Star history chart for your README
[](https://hysenlabs.com/projects/tencent-hunyuan-hunyuanimage-3-0)Was this useful?