MMEB-V3 counts 190 tasks from 78 plus 111, and its directories change name on extraction
This repo contains the code for "VLM2Vec / MMEB" [ICLR 2025], "VLM2Vec-V2 / MMEB-V2" [TMLR 2026], and "MMEB-V3" [COLM 2026]
At a glance
- What is it?
- A benchmark for omni-modality embedding models across text, image, video, audio, visual documents and agent retrieval, hosted as a Hugging Face dataset and evaluated with a single Python entry point. The dataset preparation instructions are the interesting part, because they encode two naming conventions that differ by one character.
- Who is it for?
- MMEB-V3 fits a researcher who needs a single number for how an embedding model handles audio, video, documents and agent retrieval rather than only images and text, and who has a GPU and disk budget for a dataset spanning six modality families.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 23 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
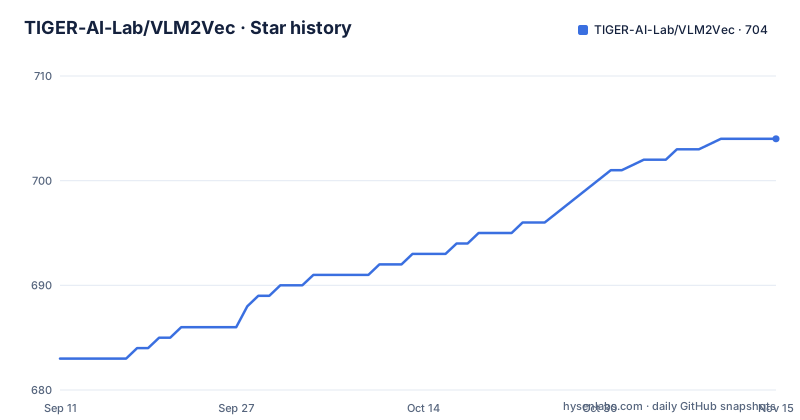
- TIGER-AI-Lab/VLM2Vec704 ★ · +21
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| TIGER-AI-Lab/VLM2Vec | 683 | 704 |
21 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Seventy-eight plus one hundred and eleven is not one hundred and ninety
The arithmetic in the introduction does not close. The second-generation benchmark is described lower down as having 78 tasks, and the third generation is described as extending it by adding 111 new tasks to reach 190 in total, which is 189. Either the extension count or the total is off by one, or one task was counted twice across the generations. For a benchmark whose purpose is to be compared against other results, an off-by-one in the headline count is the kind of detail that gets noticed immediately and undermines confidence in the rest of the table. The three new evaluation categories are stated separately and are not in question: audio, text retrieval and agent tasks.
Two directory conventions that differ by one character
The dataset preparation section contains a trap that will cost you an afternoon if you miss it. Downloaded archives store raw compressed assets in directories whose names use an underscore, such as a video tasks directory and a visual document tasks directory, and the setup script materialises them into directories whose names use a hyphen. Both forms appear in the same section, one describing what to upload and one describing what will exist on disk. The page even spells out the upload side of the rule, telling contributors not to upload already-materialised directories for the video and document tasks if the corresponding archives are uploaded. Some archive filenames also carry a trailing hyphen and asterisk, which reads like a partial or chunked upload rather than a finished file.
The setup script is idempotent by dropping marker files
Materialising the download is one script with a verification mode:
python experiments/public/data/dataset_setup_v3.py --root $MMEB_V3_ROOT
python experiments/public/data/dataset_setup_v3.py --root $MMEB_V3_ROOT --check-only
It is described as idempotent, which it achieves by skipping directories already marked with a sentinel file, extracting archives safely, and checking that the final layout is what the evaluation code expects. That design matters because the download is large and re-running the script after a partial failure should not re-extract what already worked. One directory does not follow the archive pattern: the image query set sits at the root of the expected layout rather than inside a tasks directory, and if your local download does not include it you pass its location explicitly. Check the layout with the verification mode before you spend GPU hours discovering a missing directory.
Two invocation styles and three environment variables
Standard evaluation is a Python entry point configured entirely by long, dotted command-line flags:
CUDA_VISIBLE_DEVICES=0 python eval.py \
  --pooling mean \
  --normalize true \
  --per_device_eval_batch_size 8 \
  --dataloader_num_workers 1 \
  --model_backbone nvomniembed \
  --model_name /path/to/omni-embed-nemotron-3b \
  --dataset_config experiments/public/eval/image.yaml \
  --encode_output_path exps/vlm2vec/omni-embed-nemotron-3b/image \
  --data_basedir $MMEB_V3_ROOT
The diagnostic component runs through a shell script configured by environment variables instead:
MODEL_PATH=/path/to/omni-embed-nemotron-3b \
MODEL_BACKBONE=nvomniembed \
DATA_BASEDIR=$MMEB_V3_ROOT/omniset \
OUTPUT_PATH=exps/vlm2vec/omni-embed-nemotron-3b/omniset \
PER_DEVICE_EVAL_BATCH_SIZE=8 \
bash experiments/public/eval/eval_omniset.sh
The reason for the split is visible in the paths: the standard script takes the dataset root, while the diagnostic script is pointed directly at the extracted directory inside it. Adapted baselines are supported by swapping the backbone name, the model path, the pooling choice and the output path. And a third convention appears only for models with no audio capability, where you either set a boolean to skip those tasks or point a separate environment variable at a configuration file that excludes them.
Every documented example pins a visible GPU
Both example invocations begin by restricting the process to a single device, and neither offers a CPU alternative. The evaluation flags that follow are the ones you would tune on real hardware: the pooling strategy, whether vectors are normalised, the per-device batch size and the number of data loader workers, all of which affect throughput on a memory-constrained card. With a benchmark spanning audio, video and visual documents, the data loading path is likely to be the bottleneck rather than the model, which is why the worker count is exposed at all. The batch size of eight in both examples is a conservative starting point rather than a recommendation, and nothing on the page tells you how it should change with more memory.
Two Hugging Face organisations across two generations
The badge row at the top of the page links to dataset repositories under two different organisation names. The third-generation dataset lives under one, while the second-generation suite and an earlier evaluation set live under another, and the model organisation is a third name. That is what an organisation rename looks like from the outside, and it means old instructions and blog posts will point at a namespace that no longer receives updates. The page also carries three preprint identifiers in one badge row, one per generation, while the repository description still covers all three papers and their three venues and the readme itself now describes only the third. The default branch has moved on from the tagged releases as well: the newest tag is from mid-2025 and the last push is from September 2026.
Two OpenCV packages, one pinned numpy and a floating torch
The requirements file is close to thirty entries and almost none are versioned. The exceptions are instructive. One numeric library is pinned exactly, along with the transformers version, and a third package carrying a video-decoding extra is pinned for a documented reason with a link to a discussion thread about the problem. Torch and its vision counterpart are completely unpinned, sitting next to a transformers version that is pinned to three decimal places. Two different OpenCV distributions are both listed, which is the classic way to end up with whichever one was installed first. The attention extension is unpinned and carries a note to consult its own repository for installation, since it compiles rather than installing from a wheel, and a build helper is listed to support that.
OmniSET appears twice in the tree, and four scripts sit at the root
The repository root has a directory named after the diagnostic component and the dataset layout also creates a directory with the same name inside the dataset root, so the word means two different things depending on where you are reading. Alongside it are four top-level scripts, one for evaluation, one for training, and two more for a specific omni-model training path, plus a helper module for that model sitting at the repository root rather than inside the source package. There is also a directory for one-off scripts, a vendored third-party directory, and a conda environment export file. The documented dataset helper does not live at the root either; it sits several levels down under an experiments directory that includes a component named public.
Editorial conclusion
MMEB-V3 fits a researcher who needs a single number for how an embedding model handles audio, video, documents and agent retrieval rather than only images and text, and who has a GPU and disk budget for a dataset spanning six modality families. It does not fit a CPU-only evaluation, since every documented example pins a visible GPU, and it does not fit anyone who needs the V2 or V1 suites as separate downloads, because the instructions push all three generations into one root directory. Before running anything, download with the dataset client rather than a browser, run the setup script and then its check-only mode before evaluating, and read the archive layout section closely so you upload or extract the right form. The newest release is v2.0.1 from 2025-06-30 and the last push is dated 2026-09-21.
Frequently asked questions
How many tasks does MMEB-V3 contain and what are they?
The page states 190 tasks in total, extending the 78-task second-generation benchmark by adding 111. The new categories are audio tasks, text retrieval tasks and agent tasks, and the benchmark also spans image, video and visual document retrieval.
How do I download and prepare the MMEB-V3 dataset?
Set a root path, download the dataset repository with the dataset client, then run the setup script against that root to materialise the evaluation-ready layout. Run the same script with the check-only flag afterwards to verify the layout before evaluating.
What is OmniSET in MMEB-V3?
A diagnostic component that groups semantically equivalent instances across text, image, video and audio. It is intended for controlled analysis of modality effects and instruction-conditioned cross-modal retrieval, and it runs through its own script pointed at its own extracted directory.
Can I evaluate a model that does not support audio on MMEB-V3?
Yes. Set the skip-audio-tasks flag to true, or point a data configuration path variable at the configuration that excludes audio tasks. Adapted omni-modality baselines are supported by changing the backbone, model path, pooling and output path.
Does MMEB-V3 evaluation run on CPU?
Every documented example restricts the process to a visible GPU, and no CPU path is described. The tunable flags in the example are pooling, normalisation, per-device batch size and data loader worker count.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tiger-ai-lab-vlm2vec)Star history chart for your README
[](https://hysenlabs.com/projects/tiger-ai-lab-vlm2vec)Was this useful?