jina-ai/node-DeepResearch: an iterative search-read-reason agent you can self-host
Keep searching, reading webpages, reasoning until it finds the answer (or exceeding the token budget)
At a glance
- What is it?
- node-DeepResearch loops search, page reading and reasoning until it finds an answer or runs out of token budget. It is built for concise grounded answers, not for long AI-written reports, and the README says so directly.
- Who is it for?
- Adopt node-DeepResearch if you want a self-hosted agent that returns short grounded answers with citations, and you are comfortable running Node 20 plus an LLM key and a Jina Reader key. Do not adopt it if you need long-form generated reports, since the README states that is a completely different problem and this project is not for it.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
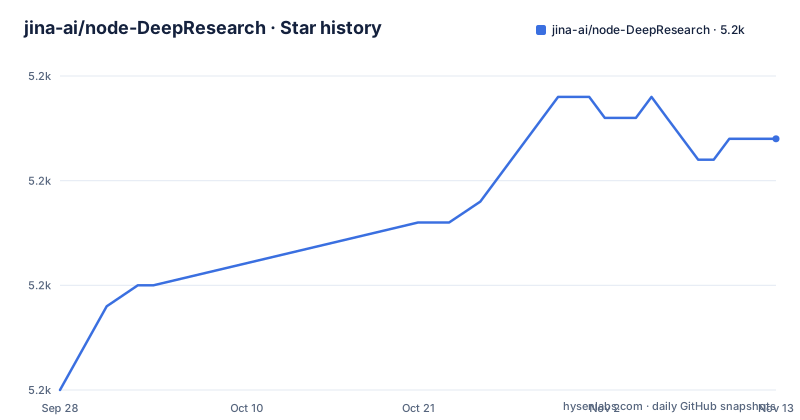
- jina-ai/node-DeepResearch5,242 ★ · +12
| Repository | 2026-09-28 | 2026-11-13 |
|---|---|---|
| jina-ai/node-DeepResearch | 5.2k | 5.2k |
12 Stars in the last 46 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem node-DeepResearch solves, and who it is actually for
A single retrieval call answers simple questions and fails on everything else. The question needs a search, then a page read, then a judgement about whether the page actually answered anything, then another search phrased differently. node-DeepResearch packages that loop as a runnable program rather than a hosted product. The repository description is the whole design statement: keep searching, reading webpages, reasoning until it finds the answer, or until the token budget is exceeded.
The README is unusually direct about the target user. It contrasts itself with OpenAI, Gemini and Perplexity deep research features and states that it focuses solely on finding the right answers through an iterative process, and that it does not optimize for long-form articles. That sentence disqualifies a large chunk of the audience that searches for deep research tools. If you want a generated report with sections and headers, this is the wrong repository. If you want a short answer with footnotes and you want to run the loop yourself, it fits.
The practical audience is engineers building a search-grounded answering feature into their own product, plus people who want to point the reasoning step at a local model instead of a hosted one. The project ships a server mode for that second group, which is covered below.
The search, read, reason loop and where the token budget bites
The README includes a Mermaid diagram that shows the control flow plainly: a Query enters a loop containing Search, Read and Reason, the loop is labelled until budget exceed, and it exits to Answer. There is no planner stage in front of the loop and no synthesis stage after it beyond the final answer.
Reasoning is delegated to an LLM through the Vercel AI SDK packages listed in package.json, specifically @ai-sdk/google and @ai-sdk/openai. The README says the default reasoning model is Gemini, latest gemini-2.0-flash, with OpenAI as an alternative. Search and page reading go through Jina Reader, which is why a JINA_API_KEY is required alongside the model key. That is the data flow: the model decides what to search for, Jina Reader returns page content, the model reads and reasons over it, and the cycle repeats.
The step count is not fixed and the README's own demo section makes that concrete. A question about the latest Jina AI blog post title took 3 steps. A question about the context length of readerlm-v2 took 2 steps. A request to list as many Jina AI employees as possible took 11 steps and is described as partially correct. A prediction question about Jina AI's biggest competitor took 42 steps and is described as arguably correct. Those examples show the budget is the real termination condition for open-ended questions, not the model deciding it is done.
package.json defines an eval script that runs src/evals/batch-evals.ts, so step count and answer quality are measurable rather than a matter of impression.
Installing node-DeepResearch and running a first query
The README gives clone-and-install as the supported path and explicitly says the npm package exists but is not recommended for now, because the code is still under active development. Take the README at its word and work from a clone.
git clone https://github.com/jina-ai/node-DeepResearch.git
cd node-DeepResearch
npm install
Before the first run you need two keys. The README says a free Jina API key with 1M tokens is available from jina.ai, and that Gemini or OpenAI handles reasoning. Note the provider switch: OpenAI is selected by setting LLM_PROVIDER, not by removing the Gemini variable.
export GEMINI_API_KEY=...
# export OPENAI_API_KEY=... # for openai
# export LLM_PROVIDER=openai # for openai
export JINA_API_KEY=jina_...

npm run dev $QUERY
The README's example queries are worth copying verbatim to see the loop behave. A trivial query such as the capital of France should terminate almost immediately, while an ambiguous one exercises the multi-step path.
npm run dev "1+1="
npm run dev "what is the capital of France?"
npm run dev "who is bigger? cohere, jina ai, voyage?"
If you would rather not run the CLI, the repository also ships an OpenAI-compatible server on port 3000, and the Dockerfile builds it as a two-stage image with node:20-slim and starts it with node ./dist/server.js. docker-compose.yml passes GEMINI_API_KEY, OPENAI_API_KEY, JINA_API_KEY and BRAVE_API_KEY into the container and maps port 3000.
npm run serve
# or with authentication:
npm run serve --secret=your_secret_token
With the secret flag, clients must send that value as a Bearer token. The README lists CherryStudio and Chatbox as GUI clients that can point at the server.
Local models, structured output and the constraint that decides everything
You can redirect reasoning to a local model. The README's instructions are counterintuitive at first read: for a local LLM you still set LLM_PROVIDER to openai, because the code talks to a local endpoint through the OpenAI client.
export LLM_PROVIDER=openai
export OPENAI_BASE_URL=http://127.0.0.1:1234/v1
export OPENAI_API_KEY=whatever
export DEFAULT_MODEL_NAME=qwen2.5-7b
The port 1234 and the model name qwen2.5-7b come from the README's example, which mentions Ollama and LMStudio as the local runtimes. The dummy API key is fine unless your local server authenticates.
Here is the limitation that matters more than any other. The README states plainly that not every LLM works with the reasoning flow, and that the project needs models which support structured output, sometimes called JSON Schema output or object output, well. A model that answers in free prose will break the loop, because the agent needs machine-readable decisions about what to search next. The README invites pull requests to add working open-source models, which tells you the verified list is short. If your candidate model is not on it, budget time for testing rather than assuming compatibility.
The second constraint is dependency on Jina Reader for both search and reading. That is a hosted service with its own key and quota, so a fully air-gapped deployment is not what this repository offers. The Dockerfile does declare a BRAVE_API_KEY environment variable, which suggests a search path beyond Jina exists, and package.json also lists a duck-duck-scrape dependency.
When node-DeepResearch is the wrong tool
The clearest failure case is the one the README names itself: long-form report generation. OpenAI, Gemini and Perplexity optimize for that, this project does not, and the README calls it a completely different problem. Choosing this repository for report generation means fighting the design.
Prediction and opinion questions are a second weak spot, and the README's own demo admits it. The competitor question ran 42 steps and is described as arguably correct, with the author noting he does not currently see weaviate as a competitor. A 42-step run is expensive, and the output is a judgement call rather than a fact. Questions with no ground truth will burn budget without converging.
Ambiguous questions are a third. The README labels the who is bigger comparison as ambiguous because big has no definition, and the employee-listing query is described as partially correct. When the question itself is underspecified, more search steps do not fix it.
Finally, there is a latency and cost shape to consider. Every step is an LLM call plus a page read. The README documents rate limits on the hosted API between 10RPM and 30RPM depending on key tier. A high-volume, low-latency question-answering feature is a poor fit; a research assistant that tolerates seconds to minutes per answer is a good one.
The hosted API and how it differs from running the code yourself
Jina operates an online deployment of what the README calls this exact codebase at search.jina.ai, and a stable API at the OpenAI-compatible endpoint https://deepsearch.jina.ai/v1/chat/completions. The model name is jina-deepsearch-v1. Any OpenAI-compatible client can call it.
The difference from self-hosting is not the algorithm, it is the operational surface. The hosted API returns two things a caller must handle. First, special tokens in the form think tags, which the README says should be rendered with care. Second, citations in GitHub-flavored markdown footnote format such as [^1] and [^2], which means your renderer needs footnote support or the citations degrade into literal bracket text.
Rate limits apply, between 10RPM and 30RPM depending on key tier, and the README points to a contact-sales page for the limit table. New API keys get 1M free tokens. The README also tells client builders to guide users toward obtaining a Jina API key from jina.ai, which is a reasonable signal that the hosted path is the intended on-ramp and self-hosting is the escape hatch.
For a comparison point, the UI is a separate repository, jina-ai/deepsearch-ui, so the front end is not bundled here. If you expected a complete application with a web interface in one clone, you will be assembling two repositories.
Licence, maintenance and upgrade cost
The licence is Apache-2.0, declared in both the LICENSE file and the license field of package.json. That is a permissive licence with an explicit patent grant, which matters if you plan to embed the agent in a commercial product. The usual obligations apply: keep the licence and notice files, and state changes you make. This is a description of the licence text, not legal advice; have counsel review anything you ship.
Maintenance status should be read from dates rather than adjectives. The last push to the default branch was on 2026-05-01, and the repository is not archived. The most recent tagged release is v1.4.0 from 2025-02-12, with v1.3.0 and v1.2.0 landing earlier that same week. The gap between the last tag and the last push is worth noting: activity on main does not automatically become a release, so pinning to v1.4.0 and pinning to a commit are different decisions.
The README's own warning is the upgrade warning. It says the code is still under active development, and that is the stated reason the npm package is not recommended. Upgrading means pulling from git and rebuilding, which the Dockerfile does in a builder stage with npm install --ignore-scripts followed by npm run build. Note that both stages pass --ignore-scripts, so any package that relies on a postinstall step will not complete it; that is a deliberate hardening choice with a compatibility cost. Version drift in the AI SDK packages, which are pinned with caret ranges in package.json, is the most likely source of build breakage on an upgrade.
Editorial conclusion
Adopt node-DeepResearch if you want a self-hosted agent that returns short grounded answers with citations, and you are comfortable running Node 20 plus an LLM key and a Jina Reader key. Do not adopt it if you need long-form generated reports, since the README states that is a completely different problem and this project is not for it. Before committing, verify that your chosen model supports structured output, because the README warns that not every LLM works with the reasoning flow, and check the current rate limits on the Jina deepsearch API tier you plan to use.
Frequently asked questions
What does node-DeepResearch do?
It runs a loop of search, read and reason until it finds an answer or exceeds the token budget. The README states it focuses solely on finding the right answers through an iterative process rather than producing long-form articles.
How do I install node-DeepResearch?
Clone the repository, run npm install, then export GEMINI_API_KEY and JINA_API_KEY before running npm run dev with your query. The README notes an npm package exists but is not recommended while the code is under active development.
Can node-DeepResearch run with a local LLM such as Ollama or LMStudio?
Yes. The README says to set LLM_PROVIDER=openai, point OPENAI_BASE_URL at your local endpoint, set a dummy OPENAI_API_KEY and set DEFAULT_MODEL_NAME. The model must support structured output, and the README warns not every LLM works with the reasoning flow.
Does node-DeepResearch provide an API?
It ships an OpenAI-compatible server started with npm run serve on port 3000, optionally with a Bearer secret. Jina also hosts a separate API at https://deepsearch.jina.ai/v1/chat/completions using the model name jina-deepsearch-v1.
What is the licence for node-DeepResearch?
Apache-2.0, as declared in the LICENSE file and the license field of package.json.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/jina-ai-node-deepresearch)Star history chart for your README
[](https://hysenlabs.com/projects/jina-ai-node-deepresearch)Was this useful?