LongLive's fastest checkpoint is 45.7 FPS and scores lowest on the benchmark
Long Video Gen Infrastructure
At a glance
- What is it?
- LongLive is NVIDIA's long video generation research repository, Apache-2.0 licensed, holding three generations of the project side by side: an interactive version accepted at ICLR 2026, a parallel training and inference infrastructure built on four-bit quantization, and a distillation system for reusing one capability across models.
- Who is it for?
- LongLive suits a research team working on long or interactive video generation who needs training and inference code rather than a product, and who is prepared to pick one of the three directories and treat it as its own project. Three things to know before you start.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
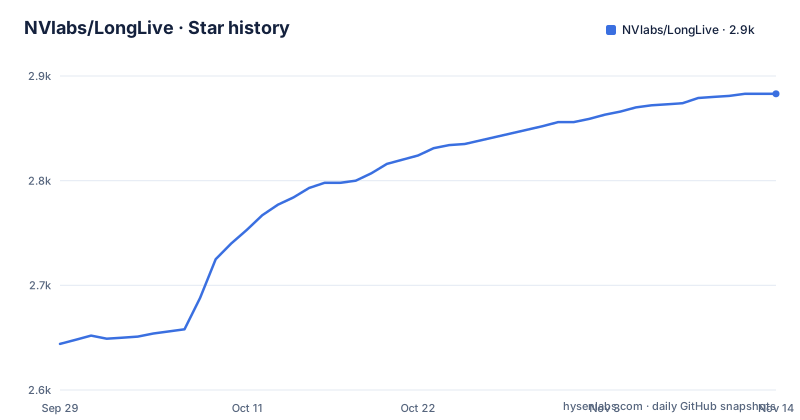
- NVlabs/LongLive2,883 ★ · +239
| Repository | 2026-09-29 | 2026-11-14 |
|---|---|---|
| NVlabs/LongLive | 2.6k | 2.9k |
239 Stars in the last 46 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three generations, three directories, three sets of weights
The repository does not have a version history in the usual sense. It has three subdirectories, each described as self-contained, each with its own code, its own documentation and its own model weights, and each corresponding to a different stage of the work. One is a real-time interactive system where you type prompts and steer a long video as it appears. One is an infrastructure for training and serving those models, built on four-bit floating point quantization and sequence parallelism. The third is a distillation system whose stated purpose is to train a capability once on a base model and reuse it across downstream models without retraining. The top level holds nothing else of substance: a licence, a contributing guide, a gitignore and this readme.
The clone command asks for one branch and no history
The install instruction is a single clone command with three flags, and it is worth reading before you copy it. It asks for a single branch rather than all of them, it names the default branch explicitly, and it sets the depth to one so no history is transferred:
git clone --single-branch --branch main --depth 1 https://github.com/NVlabs/LongLive.git
cd LongLive/LongLive-Plug   # or LongLive2.0, or LongLive1.0
That is efficient for a first look, and it has two consequences. There is no history to bisect when something in the newest directory breaks, and there is no history if you want to diff two of the three generations against each other. The demo table at the top of the file and the news timeline below it are the orientation material the readme offers instead.
The fastest checkpoint is also the lowest scoring one
Four checkpoints are tabulated with frames per second, parameter count, a quality benchmark score and a multi-shot column. The base five-billion-parameter model of the newer line runs at just under twenty-five frames per second with a score above eighty-five. Its four-step quantized variant runs at just under thirty and scores a little lower again. Its two-step variant runs at forty-five point seven, the fastest number in the table, and scores lowest of the three, just over eighty-three. The first generation's smaller model is the slowest entry and sits between the base and the four-step variant on quality. So the table encodes a speed and quality trade rather than a ranking, and the two-step variant buys its extra frames with about two points of benchmark score. Note also that all three newer rows are five-billion-parameter models, so parameter count is held constant across the comparison and the only variables are the number of sampling steps and the quantization.
Multi-shot is a column, and only the newer line fills it
The last column of the model table is a check mark rather than a number, which is the kind of column that quietly determines whether a checkpoint is usable for your task. All three checkpoints from the second generation carry it. The model from the first generation, the smaller one, does not, and the cell is simply empty. Multi-shot is named in the news entry that announced the second generation, listed there among the infrastructure features alongside four-bit quantization, parallelism, training for autoregressive models and a distillation method. So the distinction is architectural rather than a matter of tuning, and anyone who needs a model that produces more than one continuous segment is looking at the newer directory only.
The Plug table is a coverage matrix of six adapters
The newest directory ships adapters rather than standalone models, and the readme tabulates them as a coverage matrix. Six rows, in three pairs, one pair per base model. Each base model has a few-step adapter and a guidance-distillation adapter, and each row lists up to five downstream models it has been applied to. One base model is a compact architecture from a different lab, and its supported set reads like a list of world models and control systems. The second is a fourteen-billion-parameter text-to-video base, and the third is a five-billion-parameter image-and-video base. The readme is careful about the provenance of that list: the examples come from an appendix in the paper covering complete transfer coverage and additional cases. It also notes that coverage for the fourteen-billion-parameter base is reported twice, once for each adapter type, and that the two adapters for the compact base are used separately rather than together, which is the detail to carry into a reproduction attempt.
An 18.6% throughput gain came from six named changes
One news entry from May 2026 is the most useful engineering record in the file, because it lists what changed rather than only what improved. Fused kernels written in Triton for the rotary position and adaptive layer norm operations. Reduced synchronisation overhead in the key-value cache. Updates to the quantized cache applied in place. Faster dequantization of four-bit cache entries. Pinned transfers for the variational autoencoder. And a safer ordering of the low-rank adapter before quantization. The stated result is an eighteen point six percent improvement in overall throughput, with no quality figure attached. Two other entries from the same month record teacher-forcing training and distillation for image-to-video on a five-billion-parameter base.
Two of the components come from outside the organisation
Read the news timeline and the collaborations show up clearly. In April 2026 the project added key-value cache compression using an attention method implemented in someone else's repository, reported as halving the cache with no quality drop. In June 2026 a retrieval-augmented framework for long video generation was announced, and its repository sits under a different account entirely rather than in this organisation. Neither is folded into the three directories. So the repository is the training and inference infrastructure for one line of work, while adjacent research directions live in repositories that this one points at. The timeline also shows the project's own publication path in order: the first generation's paper, code, weights and demo page all appeared on the same day in September 2025, acceptance at ICLR came in late January 2026, and the second generation followed in May. The last push to the default branch is dated 30 September 2026 and the repository has no published releases, so the model files on the model hub are the only durable artefacts beyond the branch itself.
Editorial conclusion
LongLive suits a research team working on long or interactive video generation who needs training and inference code rather than a product, and who is prepared to pick one of the three directories and treat it as its own project. Three things to know before you start. Read the benchmark table as a trade, not a ranking, because the fastest checkpoint in it is also the lowest scoring on the quality metric. Decide whether multi-shot generation matters, since it is marked as a column and only the newer line fills it. And read the directory you intend to use on its own terms, since the repository's own instruction is to clone, change into one directory, and follow that directory's readme rather than this one. The materials are research artefacts with no releases and no versioned artefacts beyond the branch.
Frequently asked questions
What is NVIDIA LongLive?
A research repository for long video generation, Apache-2.0 licensed, holding three generations of the project in separate self-contained directories: a real-time interactive version accepted at ICLR 2026, a parallel training and inference infrastructure built on four-bit quantization, and a once-for-all distillation system for reusing a capability across downstream models.
Which LongLive generation should I use?
The repository's own table answers by intent. For real-time interactive generation steered while it runs, use the 1.0 directory. For fast training and serving with four-bit quantization and sequence parallelism, use 2.0. For distilling a capability once on a base model and reusing it downstream without retraining, use the Plug directory. Each has its own readme.
What are the LongLive 2.0 model benchmarks?
Four checkpoints are listed. The 5B base runs at 24.8 frames per second with a VBench score of 85.06, its four-step quantized variant at 29.7 and 84.51, its two-step variant at 45.7 and 83.14, and the 1.3B model from the first generation at 20.7 and 84.87. The three newer rows are marked as supporting multi-shot generation.
Does LongLive reduce its key-value cache?
Yes. A news entry from April 2026 records support for key-value cache compression using an external attention method, reported as a fifty percent reduction with no quality drop, implemented in a separate repository. A January 2026 entry records adapting the project's rotary position encoding into a cache-relative form, which the readme says allows generating infinite long videos.
Where are the LongLive model weights published?
On a model hub, under an organisation named for efficient large models: a collection for the Plug adapters, plus individual checkpoints for the 2.0 base, its two quantized few-step variants, and the 1.3B model from the first generation. The repository itself has no published releases.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/nvlabs-longlive)Star history chart for your README
[](https://hysenlabs.com/projects/nvlabs-longlive)Was this useful?