Chinese-CLIP: five published sizes and a news log that ends in 2023
Chinese version of CLIP which achieves Chinese cross-modal retrieval and representation generation.
At a glance
- What is it?
- A Chinese CLIP trained on roughly 200 million image-text pairs, published in five checkpoint sizes. The weights are easy to find. The state of the training extras and the dependency list is where the gaps are.
- Who is it for?
- Chinese-CLIP is worth picking when you want a checkpoint rather than a training run, because the five published sizes and their Hub links are the most settled part of this repository. Verify two things before you start. requirements.txt carries no upper bound on torch while the PyTorch 2.0 adaptation is dated 2023.5.9, and lmdb is the only exact pin in the list, so an environment holding a different lmdb build has to change it.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 7 months ago.
- What is it written in?
- Mainly Jupyter Notebook, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
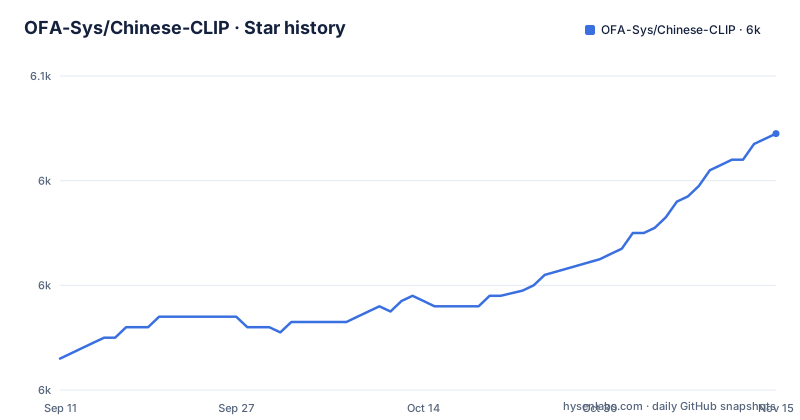
Star history
- OFA-Sys/Chinese-CLIP6,049 ★ · +43
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| OFA-Sys/Chinese-CLIP | 6k | 6k |
43 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Nine model configs ship in the package, five checkpoints are published
setup.py hands nine JSON model configs to data_files while the model table publishes five downloadable checkpoints. The nine files are RoBERTa-wwm-ext-base-chinese.json, RoBERTa-wwm-ext-large-chinese.json, ViT-B-16.json, ViT-B-32.json, ViT-L-14.json, ViT-L-14-336.json, ViT-H-14.json, RN50.json and RBT3-chinese.json. Only ViT-B-32 has no matching vision backbone in the table, where the ResNet-50 model pairs a ResNet50 tower with RBT3, and the text-tower naming does not agree: the configs say RoBERTa-wwm-ext while the table calls its text towers RoBERTa-wwm-Base and RoBERTa-wwm-Large. Backbone and resolution columns are the only keys to the mapping.
data_files=[('clip/model_configs', ['cn_clip/clip/model_configs/RoBERTa-wwm-ext-base-chinese.json',
                                    'cn_clip/clip/model_configs/RoBERTa-wwm-ext-large-chinese.json',
                                    'cn_clip/clip/model_configs/ViT-B-16.json',
                                    'cn_clip/clip/model_configs/ViT-B-32.json',
                                    'cn_clip/clip/model_configs/ViT-L-14.json',
                                    'cn_clip/clip/model_configs/ViT-L-14-336.json',
                                    'cn_clip/clip/model_configs/ViT-H-14.json',
                                    'cn_clip/clip/model_configs/RN50.json',
                                    'cn_clip/clip/model_configs/RBT3-chinese.json'
                                    ]),
            ('clip/', ['cn_clip/clip/vocab.txt'])
            ],
One exact pin, and no ceiling on torch
The dependency list is seven lines long and almost all of them float. numpy, tqdm, six, timm and torchvision carry no version at all. lmdb is the single entry pinned to an exact build, and torch states a floor of 1.7.1 with nothing above it. The dated news list records an adaptation to PyTorch 2.0 on 2023.5.9, yet the dependency file still opens the door to anything from 1.7.1 upward, so nothing in the package declares which torch releases the code is known to run on.
numpy
tqdm
six
timm
lmdb==1.3.0
torch>=1.7.1
torchvision
The news list stops on 2023.11.30, the last push is dated 2026-03-31
The Chinese README carries a dated news section that runs from the open-source release on 2022.7.8 up to a CoreML conversion script contributed on 2023.11.30. Between those two dates sit zero-shot image classification code for the ELEVATER benchmark, a Chinese version of that dataset, the FLIP finetuning strategy, ONNX and TensorRT deployment, FlashAttention, gradient accumulation, a ModelScope distillation path, and a merge of the model code and feature-extraction API into HuggingFace transformers. The repository has no GitHub releases at all, so version 1.5.1 sits in setup.py with no tag behind it. The last push on record is dated 2026-03-31, more than two years after the final news entry.
The documentation tree is bilingual, and one suffix is lowercase
Every topic ships twice. README.md and README_En.md, deployment.md and deployment_En.md, distillation.md and distillation_En.md, flash_attention.md and flash_attention_En.md all follow the same pattern with a capital E. The zero-shot dataset document breaks it: zeroshot_dataset.md is paired with zeroshot_dataset_en.md. setup.py reads README_En.md for its long_description, so the description published with the package is the English file even though the repository front page is the Chinese one. The Chinese file carries the model table, the dated news list and the result tables.
MUGE rows for three systems, with per-scale numbers pushed into Results.md
The evaluation section covers text-to-image retrieval on the official MUGE validation set in both zero-shot and finetune form, measured by R@1, R@5, R@10 and MR. Three rows are shown. Wukong moves from 42.7 at R@1 zero-shot to 52.7 after finetuning, R2D2 from 49.5 to 60.1, and CN-CLIP from 63.0 to 68.9. The Chinese text is explicit about the scope: it prints the baseline models and the single best-scaled Chinese-CLIP model, and sends every other size to Results.md. Zero-shot image classification is reported the same way, across ten ELEVATER datasets, with the Chinese version of that dataset released on 2022.12.3 and documented separately in zeroshot_dataset.md. A reader comparing model sizes has to leave the README for Results.md to do it.
cn_clip is declared twice in the same setup() call
The packaging block passes cn_clip to py_modules and then passes find_packages(exclude=["tests*"]) as packages, so the one directory reaches the installer through two mechanisms at once. include_package_data is set to True and the same nine config files are repeated under data_files, and the vocabulary file is declared under a clip/ key rather than a cn_clip/ key, which places it outside the importable package directory. The exclude pattern anticipates a tests package that the repository root does not contain. The metadata itself is thin in the way small research packages tend to be: author is a team name, author_email is an empty string, keywords is the single word clip, and the description is the phrase the Chinese version of CLIP.
Training extras live in four separate documents and one script under cn_clip/deploy
The dated news entries map onto specific files rather than a single guide. distillation.md and its English pair cover knowledge distillation finetuning through ModelScope, contributed in September 2023. flash_attention.md covers the training speed and memory work from February 2023. deployment.md covers the ONNX and TensorRT export announced in January 2023, which is also where pretrained TensorRT models are promised. The CoreML path is not a document at all: it is a single conversion script at cn_clip/deploy/pytorch_to_coreml.py. Gradient accumulation for contrastive learning, added 2023.3.20 to simulate a larger batch size, and the FLIP finetune strategy from December 2022 link from the news entries to sections of the README rather than to files of their own at the repository root.
Editorial conclusion
Chinese-CLIP is worth picking when you want a checkpoint rather than a training run, because the five published sizes and their Hub links are the most settled part of this repository. Verify two things before you start. requirements.txt carries no upper bound on torch while the PyTorch 2.0 adaptation is dated 2023.5.9, and lmdb is the only exact pin in the list, so an environment holding a different lmdb build has to change it. For fine-tuning, read Results.md for the per-scale numbers and treat the dated news list, which stops at 2023.11.30 against a last push dated 2026-03-31, as a record of what existed at that time.
Frequently asked questions
What is Chinese-CLIP and what was it trained on?
It is the Chinese version of CLIP, built on the open_clip project and trained on large-scale Chinese data of roughly 200 million image-text pairs. It is released under the MIT license as the cn_clip package, with five model sizes published.
How do I get Chinese-CLIP weights and the code that loads them?
The code installs as the cn_clip package, version 1.5.1 in setup.py, and the weights are not packaged with it. Each of the five checkpoints, from chinese-clip-rn50 through chinese-clip-vit-huge-patch14, is downloaded from the Hugging Face Hub or from ModelScope. The repository has no GitHub releases.
How many Chinese-CLIP model sizes are published and how do they differ?
Five. chinese-clip-rn50 is 77M parameters with a ResNet50 tower and an RBT3 text tower. chinese-clip-vit-base-patch16 is 188M, chinese-clip-vit-large-patch14 is 406M, chinese-clip-vit-large-patch14-336px is 407M at 336 resolution, and chinese-clip-vit-huge-patch14 is 958M with a ViT-H/14 tower and RoBERTa-wwm-Large on the text side.
Does the Chinese-CLIP repository publish tagged releases?
No. The repository has no GitHub releases. The package version is 1.5.1 in setup.py, so there is no tag to install from and nothing to diff against.
What does the ELEVATER zero-shot evaluation in Chinese-CLIP cover?
Zero-shot image classification is reported across ten ELEVATER datasets. Code for the zero-shot classification task was added on 2022.11.22 to support the benchmark, and the Chinese version of the dataset was released on 2022.12.3 with its own document in the repository root.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ofa-sys-chinese-clip)Star history chart for your README
[](https://hysenlabs.com/projects/ofa-sys-chinese-clip)Was this useful?