kvcached reserves GPU address space before the KV cache exists
Virtualized Elastic KV Cache for Dynamic GPU Sharing and Beyond
At a glance
- What is it?
- kvcached is a Python KV cache daemon for SGLang and vLLM that reserves GPU virtual memory at startup and attaches physical GPU memory at runtime. Its own tables disagree about which vLLM release is tested, and its latency range names no baseline.
- Who is it for?
- The virtual memory mechanism is the reason to read this project. Reserving address space and attaching GPU memory on demand changes how a serving engine sizes itself, and the repository ships the pieces to back that up: a native extension under csrc, a controller directory, an engine integration layer, and nine worked examples.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
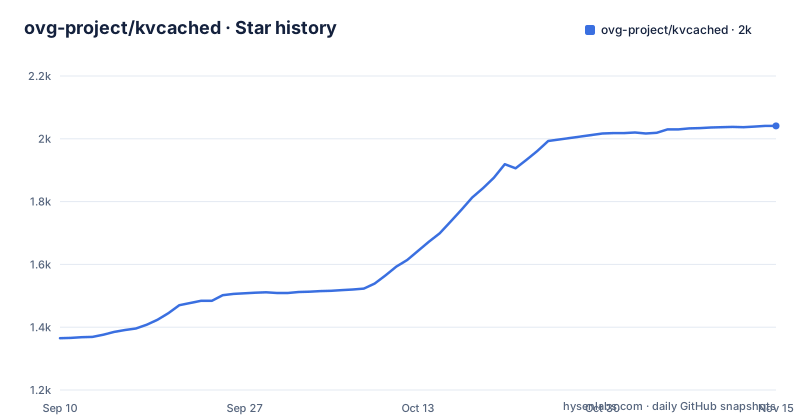
- ovg-project/kvcached2,041 ★ · +676
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| ovg-project/kvcached | 1.4k | 2k |
676 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Reservation first, physical memory only when the cache is touched
The design turns on one distinction that the rest of the project inherits: logical KV space and physical GPU memory are kept apart. A serving engine can reserve virtual memory at startup and leave it unbacked. When a request actually touches a region, kvcached maps real GPU memory behind it at runtime, and releases that backing when the load recedes. The project description phrases this as decoupling GPU virtual addressing from physical memory allocation, and the KV cache feature list phrases the same thing as runtime mapping that decouples logical KV from physical GPU memory.
That separation is what makes elastic allocation possible. Under static reservation, the memory a model could ever need has to be committed before the first token arrives, so a bursty workload pays for its worst minute permanently. Under this scheme capacity follows live load, and two models can share one device without the fixed partitioning that the multi-LLM serving case describes as the current practice.
Four deployment shapes are laid out side by side: concurrent multi-LLM serving on one GPU, serverless LLM deployment where models spin up and down on demand, compound AI pipelines that spread elastic allocation across specialized retrieval, reasoning and summarization models, and colocation of inference with training jobs, fine-tuning or vision models. The examples directory backs each of them with a numbered directory running from 01_simple_two_models to 09_prefix_caching.
The engine stays unmodified, and a root .pth file does the patching
The stated result is an unmodified vLLM engine run with dynamically allocated memory, and the repository layout is consistent with that claim. There is no engine fork in the tree. What sits at the root instead is kvcached_autopatch.pth, a path configuration file Python processes at interpreter startup, next to an engine_integration directory for the glue and a csrc directory holding the C++ and CUDA sources.
The build script treats that native layer as load bearing. setup.py imports from torch.utils.cpp_extension and raises ImportError("Torch not found, please install torch>=2.10.0 first.") when torch is missing, then walks csrc for every .cpp file while skipping the AppleDouble sidecar files macOS leaves in a checkout. It sets STABLE_ABI_TARGET to the pair (2, 10), builds against the libtorch stable ABI, and carries a comment stating that wheels are compatible with Torch 2.10 and above. get_extensions compares the running torch version against that target and refuses anything older with a RuntimeError.
The surrounding tooling is not incidental. A .clang-format file at the root, a .license-header.txt that the sources themselves carry as SPDX headers, and a .pre-commit-config.yaml tie the C++ layer to the same rules. A controller directory holds the daemon side, docker holds container builds, and tests and tools complete the tree.
Two different vLLM releases are called tested in the same file
The engine support table and the installation prerequisites disagree about vLLM. The table gives vLLM as v0.8.4 and above, tested up to v0.24.0. The prerequisites, written further down the same file, say vLLM tested with v0.19.0. For SGLang the two places agree, giving v0.4.9 and above tested up to v0.5.15 in the table and tested with v0.5.15 in the prerequisites. One engine therefore has a single tested ceiling stated twice, and the other has two ceilings five minor releases apart.
Attention coverage is given once, for both engines: MHA, GQA, MLA, sliding window and hybrid. The example models span DeepSeek-V3, Qwen3-8B, GPT-OSS-20B, Qwen3.5-9B, Gemma-4-E2B-it and Gemma-4-12B-it. The 2026-03 update entry is narrower than that list. It records pipeline parallelism support landing for MLA models such as DeepSeek-V3 and DeepSeek-V2 and for the GPT-OSS hybrid attention model openai/gpt-oss-20b in vLLM, and records GPT-OSS support in SGLang moving to v0.5.9.
Per-model results do not appear in the README at all. The table sends readers to issue 425 for per-model results on each engine and KV layout, which means whether a given checkpoint works with a given engine is settled by an issue thread rather than by a table inside the repository. Anyone with an unusual model in mind should read that thread before assuming support.
The build demands torch 2.10 while the dependency list never mentions it
pyproject.toml declares three runtime dependencies: numpy>=1.26.0, posix_ipc>=1.0 and wrapt>=1.15. Torch is not among them, in the main list or in the optional dev group, which holds only pre-commit, setuptools>=64 and wheel. Torch is nevertheless the first thing the build script looks for, and the message it raises names a specific floor: torch>=2.10.0. The keywords list carries pytorch and cuda, so the intent is plain even though nothing in the dependency metadata installs either.
That ordering is why the one install line the README gives turns build isolation off:
pip install kvcached --no-build-isolationWith isolation left on, the build would run in a fresh environment where the torch import at the top of setup.py fails and the install stops at that ImportError. Turning isolation off makes the command depend on the environment it runs in, which is the same environment the prerequisites describe: Python tested with 3.9 through 3.13, plus an existing SGLang or vLLM install for kvcached to attach to as a plugin. The package metadata agrees on the Python range, giving requires-python = >=3.9,<3.14 and classifiers for 3.9 through 3.13. The project also classifies itself as Development Status :: 3 - Alpha, and its own version field reads 0.1.5.
kvctl and kvtop get installed but the feature list names neither
Installing the package puts two commands on the path. pyproject.toml registers kvctl and kvtop under project scripts, pointing at kvcached.cli.kvctl:main and kvcached.cli.kvtop:main. Neither name appears in the part of the README that covers installation and key features. The feature list attributes memory control to a single command line tool, described as enforcing memory limits with a kvcached CLI, and it lists a frontend router with sleep mode separately, again without naming a binary.
Which command does what is left to the source. The examples directory hints at the split: 02_memory_control and 03_model_router_sleep line up with the two capabilities named without commands, and 06_serverless_serving covers the on-demand spin-up case. A reader who wants the router or wants a hard memory ceiling has to open the CLI package or run the examples, because the feature list, the installation chapter and the package metadata together never pair a name with a behavior.
The installation chapter is also short. It opens with a prerequisites list and a subsection headed Install from PyPI, and that subsection ends with the single pip line above. No other install route is written down in this README, even though the tree carries a docker directory that would hold one of them.
The 2-28x TTFT range names its workload and not its baseline
The headline performance claim is specific about the workload and silent about the comparison. Three Llama-3.1-8B models share one A100-80G under a workload with intermittent peaks, and against engines that reserve GPU memory statically at startup the README reports a 2-28x reduction in time to first token. The harness is named, benchmarks/bench_latency_benefit, so the numbers are reproducible by anyone with matching hardware.
What the range does not carry is a baseline engine version. The claim is worded against current serving engines in the abstract, with SGLang and vLLM named elsewhere in the same file as the supported integrations. Deciding whether the range applies to a given setup means opening the benchmark directory or the issue 425 thread to learn which engine version produced the low end and which produced the high end, and whether both ends come from the same hardware as the main table.
The chapter above it is thinner still. Under the heading kvcached in action, the README states that a simple example shows an unmodified vLLM engine run with dynamically allocated memory, and then shows no code. The demo that would follow is an image. The integration walkthrough a new user needs most therefore lives in the blog and video links in the page header rather than in the file itself.
requirements.txt asks to be mirrored in pyproject.toml and is not
requirements.txt opens with the line Should be mirrored in pyproject.toml, and the two files then diverge in four places. pytest and pytest-asyncio appear only in requirements.txt. The dev group in pyproject.toml carries pre-commit, setuptools>=64 and wheel, with no test runner, even though the same file sets asyncio_mode = "auto" and comments that async def tests and fixtures run on asyncio without per-test markers. numpy is missing from requirements.txt despite being a hard runtime dependency at numpy>=1.26.0. wrapt is pinned to wrapt>=1.15 in pyproject.toml and left bare in requirements.txt. Only posix_ipc>=1.0 matches on both sides.
The practical effect is that a pip install driven from requirements.txt will not build this project, because torch appears nowhere in it either. The file is best read as a developer environment file rather than an install recipe, which fits its contents but does not fit the header comment asking for it to be mirrored.
Package metadata has a smaller mismatch of its own. The project summary in pyproject.toml reads a KV cache management system that supports on-demand KV cache allocation for LLMs with GPU virtual memory, and the Homepage URL under project urls is the GitHub repository itself, while the header links in the README point to kvcached.org. No separate homepage is recorded for the repository.
Three tags in three months, then six months of commits without a new one
The release record is regular at first and then stops. v0.1.3 was tagged on 2026-01-10, v0.1.4 on 2026-03-05 and v0.1.5 on 2026-04-07, roughly two months apart. The branch tip is dated 2026-10-02, so the newest tag sits about six months behind the last commit while the version field in pyproject.toml still reads 0.1.5. The repository is not archived, which points at a paused release step rather than a stopped project.
Feature work continued through that window. The 2026-04 entries record prefix caching landing, with automatic prefix caching for vLLM and RadixCache for SGLang, giving cross-request prefix reuse while memory stays elastic and the memory bound stays configurable. The same month records a Red Hat writeup of Sardeenz, a project under rh-aiservices-bu, built on kvcached to provide dynamic multi-model serving with Kubernetes and OpenShift support.
The root of the repository is an unusual mix of developer documentation and agent configuration. AGENTS.md and CLAUDE.md sit beside a .gemini directory, with docs and examples carrying the reader-facing material and benchmarks carrying the latency harness. Anyone looking for the conventions the tooling enforces will find them split across those files rather than collected in one place.
Editorial conclusion
The virtual memory mechanism is the reason to read this project. Reserving address space and attaching GPU memory on demand changes how a serving engine sizes itself, and the repository ships the pieces to back that up: a native extension under csrc, a controller directory, an engine integration layer, and nine worked examples. Two things need checking before anyone builds on it. The engine support table and the installation prerequisites name two different tested vLLM releases, and the 2-28x time to first token figure comes with a GPU, a model count and a workload shape but no baseline engine version. Read the version support and the latency range as claims to confirm against benchmarks/bench_latency_benefit and issue 425 rather than settled numbers. Operators sharing one GPU across several models can read the code and judge the design. Anyone building a latency budget should measure on their own hardware first.
Frequently asked questions
What does kvcached actually do with GPU virtual memory?
It lets a serving engine reserve virtual memory at startup and attach physical GPU memory later, at runtime, only for the parts of the KV cache a live request touches. The result is elastic allocation across several models sharing one device.
Which serving engines does kvcached support, and at which versions?
SGLang and vLLM. The support table gives SGLang at v0.4.9 and above tested up to v0.5.15, and vLLM at v0.8.4 and above tested up to v0.24.0, while the installation prerequisites name v0.19.0 as the tested vLLM release.
Why does installing kvcached need --no-build-isolation?
setup.py imports torch at build time and raises ImportError("Torch not found, please install torch>=2.10.0 first.") when it is missing, so the build has to see a torch that is already installed in the target environment.
Which commands does the kvcached package put on the path?
Two: kvctl and kvtop, both registered under project scripts in pyproject.toml. The key features section attributes memory limit enforcement to a kvcached CLI without saying which of the two performs it.
What is the newest kvcached release, and how far behind is the source?
v0.1.5, tagged 2026-04-07 after v0.1.4 on 2026-03-05 and v0.1.3 on 2026-01-10. The default branch was pushed on 2026-10-02 and the version field in pyproject.toml still reads 0.1.5.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ovg-project-kvcached)Star history chart for your README
[](https://hysenlabs.com/projects/ovg-project-kvcached)Was this useful?