speech-to-text-benchmark: eleven engines, nine corpora, and only one metric every engine is scored on
speech to text benchmark framework
At a glance
- What is it?
- A deliberately flat Python framework from Picovoice for comparing speech-to-text engines. Installing it pulls the SDK for all eleven engines at once, four of the six metrics apply only to some of them, and two of the documented command blocks cannot be pasted as written.
- Who is it for?
- Use this when your decision is between engines on the same corpus and the only thing you truly need is an error rate you can compare. That is what the framework does well: it fixes the metric definitions, fixes the normalisation path, and runs the same loop over whichever engine you name.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
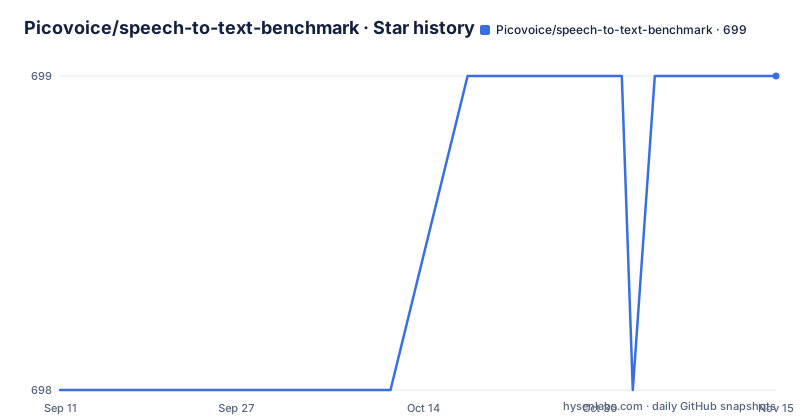
- Picovoice/speech-to-text-benchmark699 ★ · +1
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| Picovoice/speech-to-text-benchmark | 698 | 699 |
1 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Four of the six metrics apply only to some engines, which makes WER the honest column
The metrics section defines six measures, and the applicability rules are the interesting part. Word error rate is universal: edit distance over words, divided by the word count of the reference transcript. Character error rate follows the same shape over characters, and is reported only for Korean and Japanese, following industry standards. Punctuation error rate divides punctuation-specific errors by the number of punctuation-related operations in the reference, citing section 3 of a published paper. Core-Hour counts the CPU hours needed to process one hour of audio, and is explicitly omitted for cloud engines. Word emission latency measures the average delay from a word finishing being spoken to its transcription being emitted, and is measured only for streaming engines. Model size is the aggregate size of the acoustic and language models in megabytes, also omitted for cloud engines. So a cloud streaming engine can be scored on three metrics, a local batch engine on three others, and only WER is common to every row.
Installing the benchmark installs all eleven engine SDKs, including NeMo
The install step is one command:
pip3 install -r requirements.txtWhat that file contains is the real story. Every engine has a pinned SDK in it: amazon-transcribe, azure-cognitiveservices-speech, boto3, google-cloud-speech, ibm_watson, moonshine-voice, a NeMo toolkit with the asr extra, openai-whisper, pywhispercpp, vosk, and both Picovoice packages, pvcheetah and pvleopard. Alongside them are torch pinned to a CPU-only build at 2.11.0, reached through PyTorch's own CPU wheel index declared as an extra index URL at the top of the file. Most dependencies are pinned to exact versions while a handful, including numpy, matplotlib, requests and soundfile, are not pinned at all. The consequence for a user is that benchmarking a single cloud engine means installing the client libraries for all of them, plus a speech toolkit that is only needed for one streaming model. The framework is minimalist in its code and the opposite in its dependency surface.
Two of the command blocks are missing line continuations, and one placeholder has a nested brace
Each engine gets its own invocation, and two of them cannot be pasted as printed. The Azure block is:
python3 benchmark.py \
--dataset ${DATASET} \
--dataset-folder ${DATASET_FOLDER} \
--language ${LANGUAGE} \
--engine AZURE_SPEECH_TO_TEXT \
--azure-speech-key ${AZURE_SPEECH_KEY}
--azure-speech-location ${AZURE_SPEECH_LOCATION}
The key argument ends the command instead of continuing it, so the location argument on the next line becomes a separate invocation that will fail. The Watson block has the same defect on both of its trailing arguments. Above the Watson block the prose is also malformed: the URL placeholder is written with a nested brace, opening a substitution inside another substitution, where a single pair was meant. Neither fault is dangerous, both are annoying, and both are the kind of thing you discover only after the command returns an error rather than a result.
The metric section names two punctuation marks while the flag accepts three
The punctuation error rate is defined in the metrics section as being reported for periods and question marks. The usage section then describes the flag that controls it, with a punctuation set that accepts one or more of a period, a question mark and a comma, defaulting to the first two. So a third mark is computable and undocumented in the metric's own definition. That matters more than it sounds, because punctuation error rate is normalised by the number of punctuation-related operations in the reference transcript, so the denominator changes with the set of marks you score. Two runs of the same audio against the same engine with different punctuation sets are not comparable, and the document does not say so. The flag to enable the metric at all is separate again, so a full invocation needs both the punctuation switch and the set.
Nine flat modules, no package, no tests and no continuous integration
The repository is a script collection rather than an installable library. The root holds benchmark.py, a second entry point for latency named benchmark_latency.py, then dataset.py, engine.py, languages.py, metric.py, normalizer.py, plot_results.py and results.py, alongside requirements.txt, a results directory, a script directory with its own documentation, a licence file, a gitignore and the README. There is no package directory, no pyproject or setup file, and no import name to install, so you run it from a checkout against files in place. There is also no test directory and no workflow configuration in the root listing. For a framework whose entire purpose is producing numbers that other people will argue about, that absence is the thing to weigh: the normalisation module and the metric definitions are the parts that decide whether a comparison is fair, and nothing in the repository checks them.
Nine corpora, ten dataset constants, and two that need a separate download
The data section names nine sources: LibriSpeech, TED-LIUM, Common Voice, Multilingual LibriSpeech, VoxPopuli, Fleurs, JSUT Basic, Zeroth Korean and Pansori TEDxKR. The usage section then lists ten dataset constants, because LibriSpeech appears as two splits, a test clean and a test other. Nine language codes are supported, covering English, French, German, Spanish, Italian, both Brazilian and European Portuguese, Korean and Japanese. Two of the corpora are called out as needing their own download instructions rather than arriving with the rest, and both of those are hosted as datasets on Hugging Face, which is also why a Hugging Face hub client sits in the requirements. The pairing of corpora and languages is uneven by design, since a Korean corpus and a Japanese corpus exist precisely so the character error rate rule has something to apply to.
Eleven engines, of which four are cloud, two are the publisher's, and one is English-only
The engine list mixes hosted services and local models in one table without a column saying which is which. Four are cloud: Amazon Transcribe, Azure Speech-to-Text, Google Speech-to-Text and IBM Watson Speech-to-Text. Six are local or runnable yourself: Moonshine, Nemotron 3.5 ASR Streaming, OpenAI Whisper, Vosk, Whisper.cpp, and Picovoice's own Cheetah and Leopard, which makes seven local and two of those belong to the company that publishes the benchmark. The measurement rules encode the split rather than the prose: cloud engines get no Core-Hour and no model size, since neither is knowable from outside, and streaming engines get latency. Watson carries its own restriction, stated once in its own section, that it supports English only. So any table built from this framework mixes rows that were measured under different availability, which is fine for a word error rate comparison and misleading for anything else.
Editorial conclusion
Use this when your decision is between engines on the same corpus and the only thing you truly need is an error rate you can compare. That is what the framework does well: it fixes the metric definitions, fixes the normalisation path, and runs the same loop over whichever engine you name. Treat everything else in the results as conditional, because the table is assembled from six metrics with different applicability rules, so a row missing latency or model size is not a row that scored badly on it. Two practical warnings before you run anything. `pip3 install -r requirements.txt` installs the SDK for every one of the eleven engines, including a NeMo toolkit and a CPU-only PyTorch pinned from PyTorch's CPU index, whether or not you intend to benchmark them, so expect a heavy install for a single-engine comparison. And the documentation has copy-paste faults: the Azure and Watson command blocks are missing line continuations, and the Watson placeholder is written with a nested brace. Copy the arguments, not the blocks.
Frequently asked questions
Which metrics does the Picovoice speech-to-text benchmark report?
Six: word error rate, character error rate reported for Korean and Japanese following industry standards, punctuation error rate for periods and question marks, Core-Hour CPU hours per hour of audio, word emission latency for streaming engines only, and aggregate model size in megabytes. Core-Hour and model size are omitted for cloud engines.
Which speech-to-text engines does it benchmark?
Eleven: Amazon Transcribe, Azure Speech-to-Text, Google Speech-to-Text, IBM Watson Speech-to-Text, Moonshine, Nemotron 3.5 ASR Streaming, OpenAI Whisper, Vosk, Whisper.cpp, and Picovoice's own Cheetah and Leopard. Watson supports English only.
What does it take to run the benchmark?
It was developed and tested on Ubuntu 22.04 with Python 3.12. You install FFmpeg, download the datasets, and then run `pip3 install -r requirements.txt`. That file pins a CPU-only torch at 2.11.0 through PyTorch's CPU index and includes the SDK for every engine.
Which datasets and languages are supported?
Ten dataset constants covering LibriSpeech test clean and test other, TED-LIUM, Common Voice, Multilingual LibriSpeech, VoxPopuli, Fleurs, Zeroth Korean, Pansori and JSUT Basic, across nine language codes: EN, FR, DE, ES, IT, PT_BR, PT_PT, KO and JA.
How do I evaluate punctuation error rate?
Pass the `--punctuation` flag, and use `--punctuation-set` to choose which marks to score. The set accepts one or more of a period, a question mark and a comma, and defaults to the period and question mark.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/picovoice-speech-to-text-benchmark)Star history chart for your README
[](https://hysenlabs.com/projects/picovoice-speech-to-text-benchmark)Was this useful?